
Server · #60 trending MCP repo · ↗ +111 stars this week
Code Review Graph
tirth8205/code-review-graph
Local-first code intelligence graph for MCP and CLI. Builds a persistent map of your codebase so AI coding tools read only what matters, with benchmarked context reductions on reviews and large-repo workflows.
- Stars
- 33k
- This week
- +111
- Forks
- 3.0k
- Open issues
- 113
- Skills inside
- 8
Inside this repo
8 skills
code_review_graph/assets/code-review-graphbuild-graphBuild or update the code review knowledge graph. Run this first to initialize, or let hooks keep it updated automatically.skills/build-graphdebug-issueSystematically debug issues using graph-powered code navigationskills/debug-issueexplore-codebaseNavigate and understand codebase structure using the knowledge graphskills/explore-codebaserefactor-safelyPlan and execute safe refactoring using dependency analysisskills/refactor-safelyreview-changesPerform a structured code review using change detection and impactskills/review-changesreview-deltaReview only changes since last commit using impact analysis. Token-efficient delta review with automatic blast-radius detection.skills/review-deltareview-prReview a PR or branch diff using the knowledge graph for full structural context. Outputs a structured review with blast-radius analysis.skills/review-prDocumentation
README
code-review-graph
A local code knowledge graph that gives AI coding tools precise review context over MCP.
English | 简体中文 | 日本語 | 한국어 | हिन्दी




Usage · Commands · FAQ · Troubleshooting · GitHub Action · Reproducing the benchmarks · Roadmap
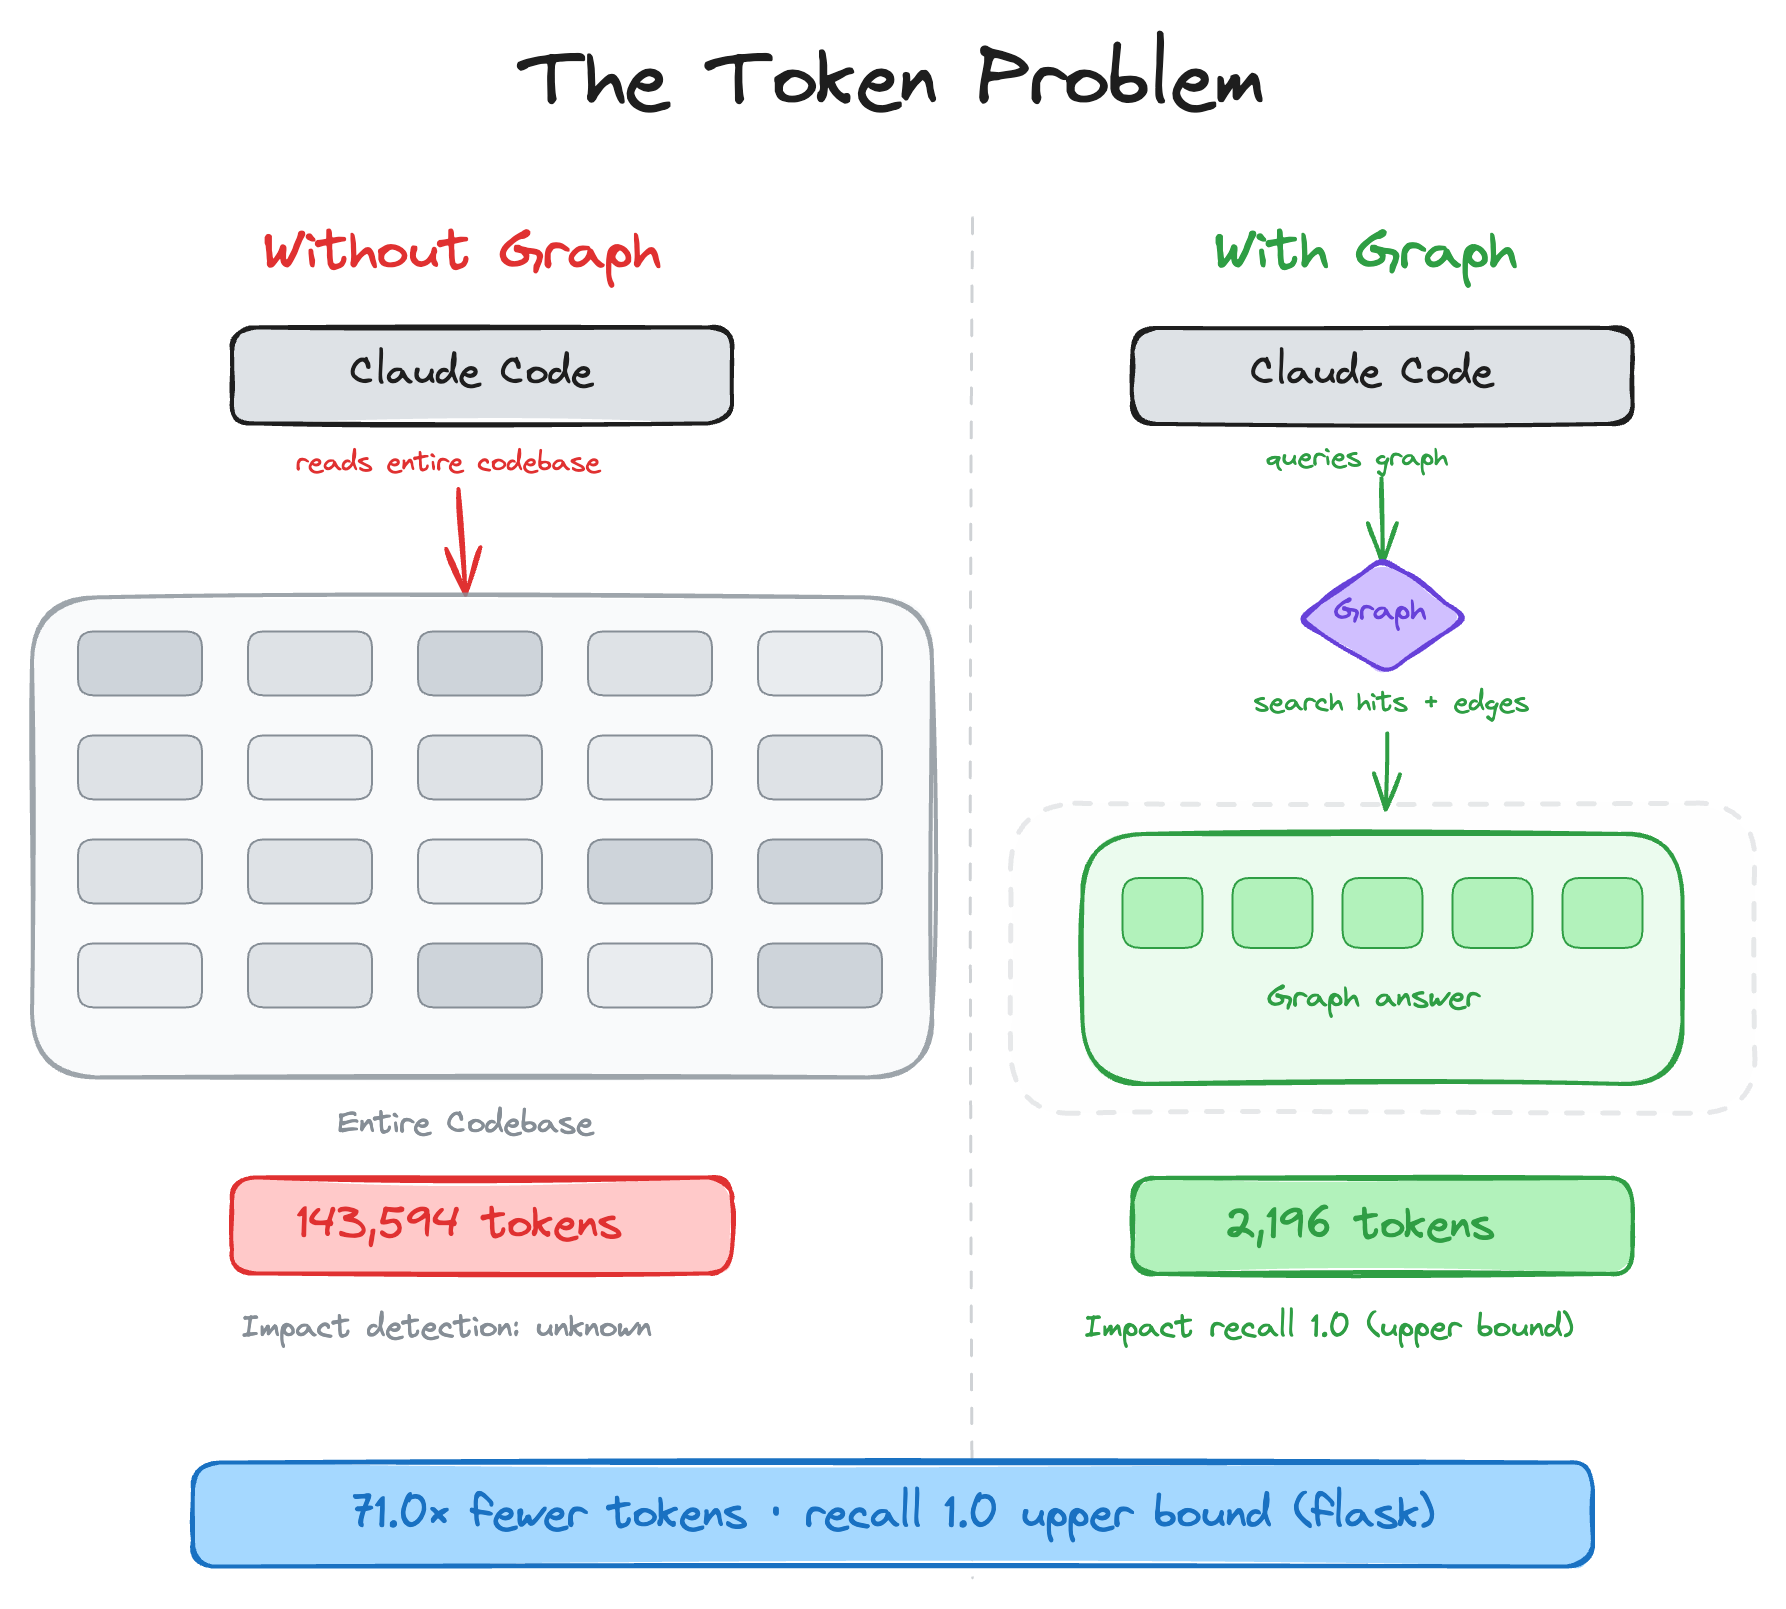
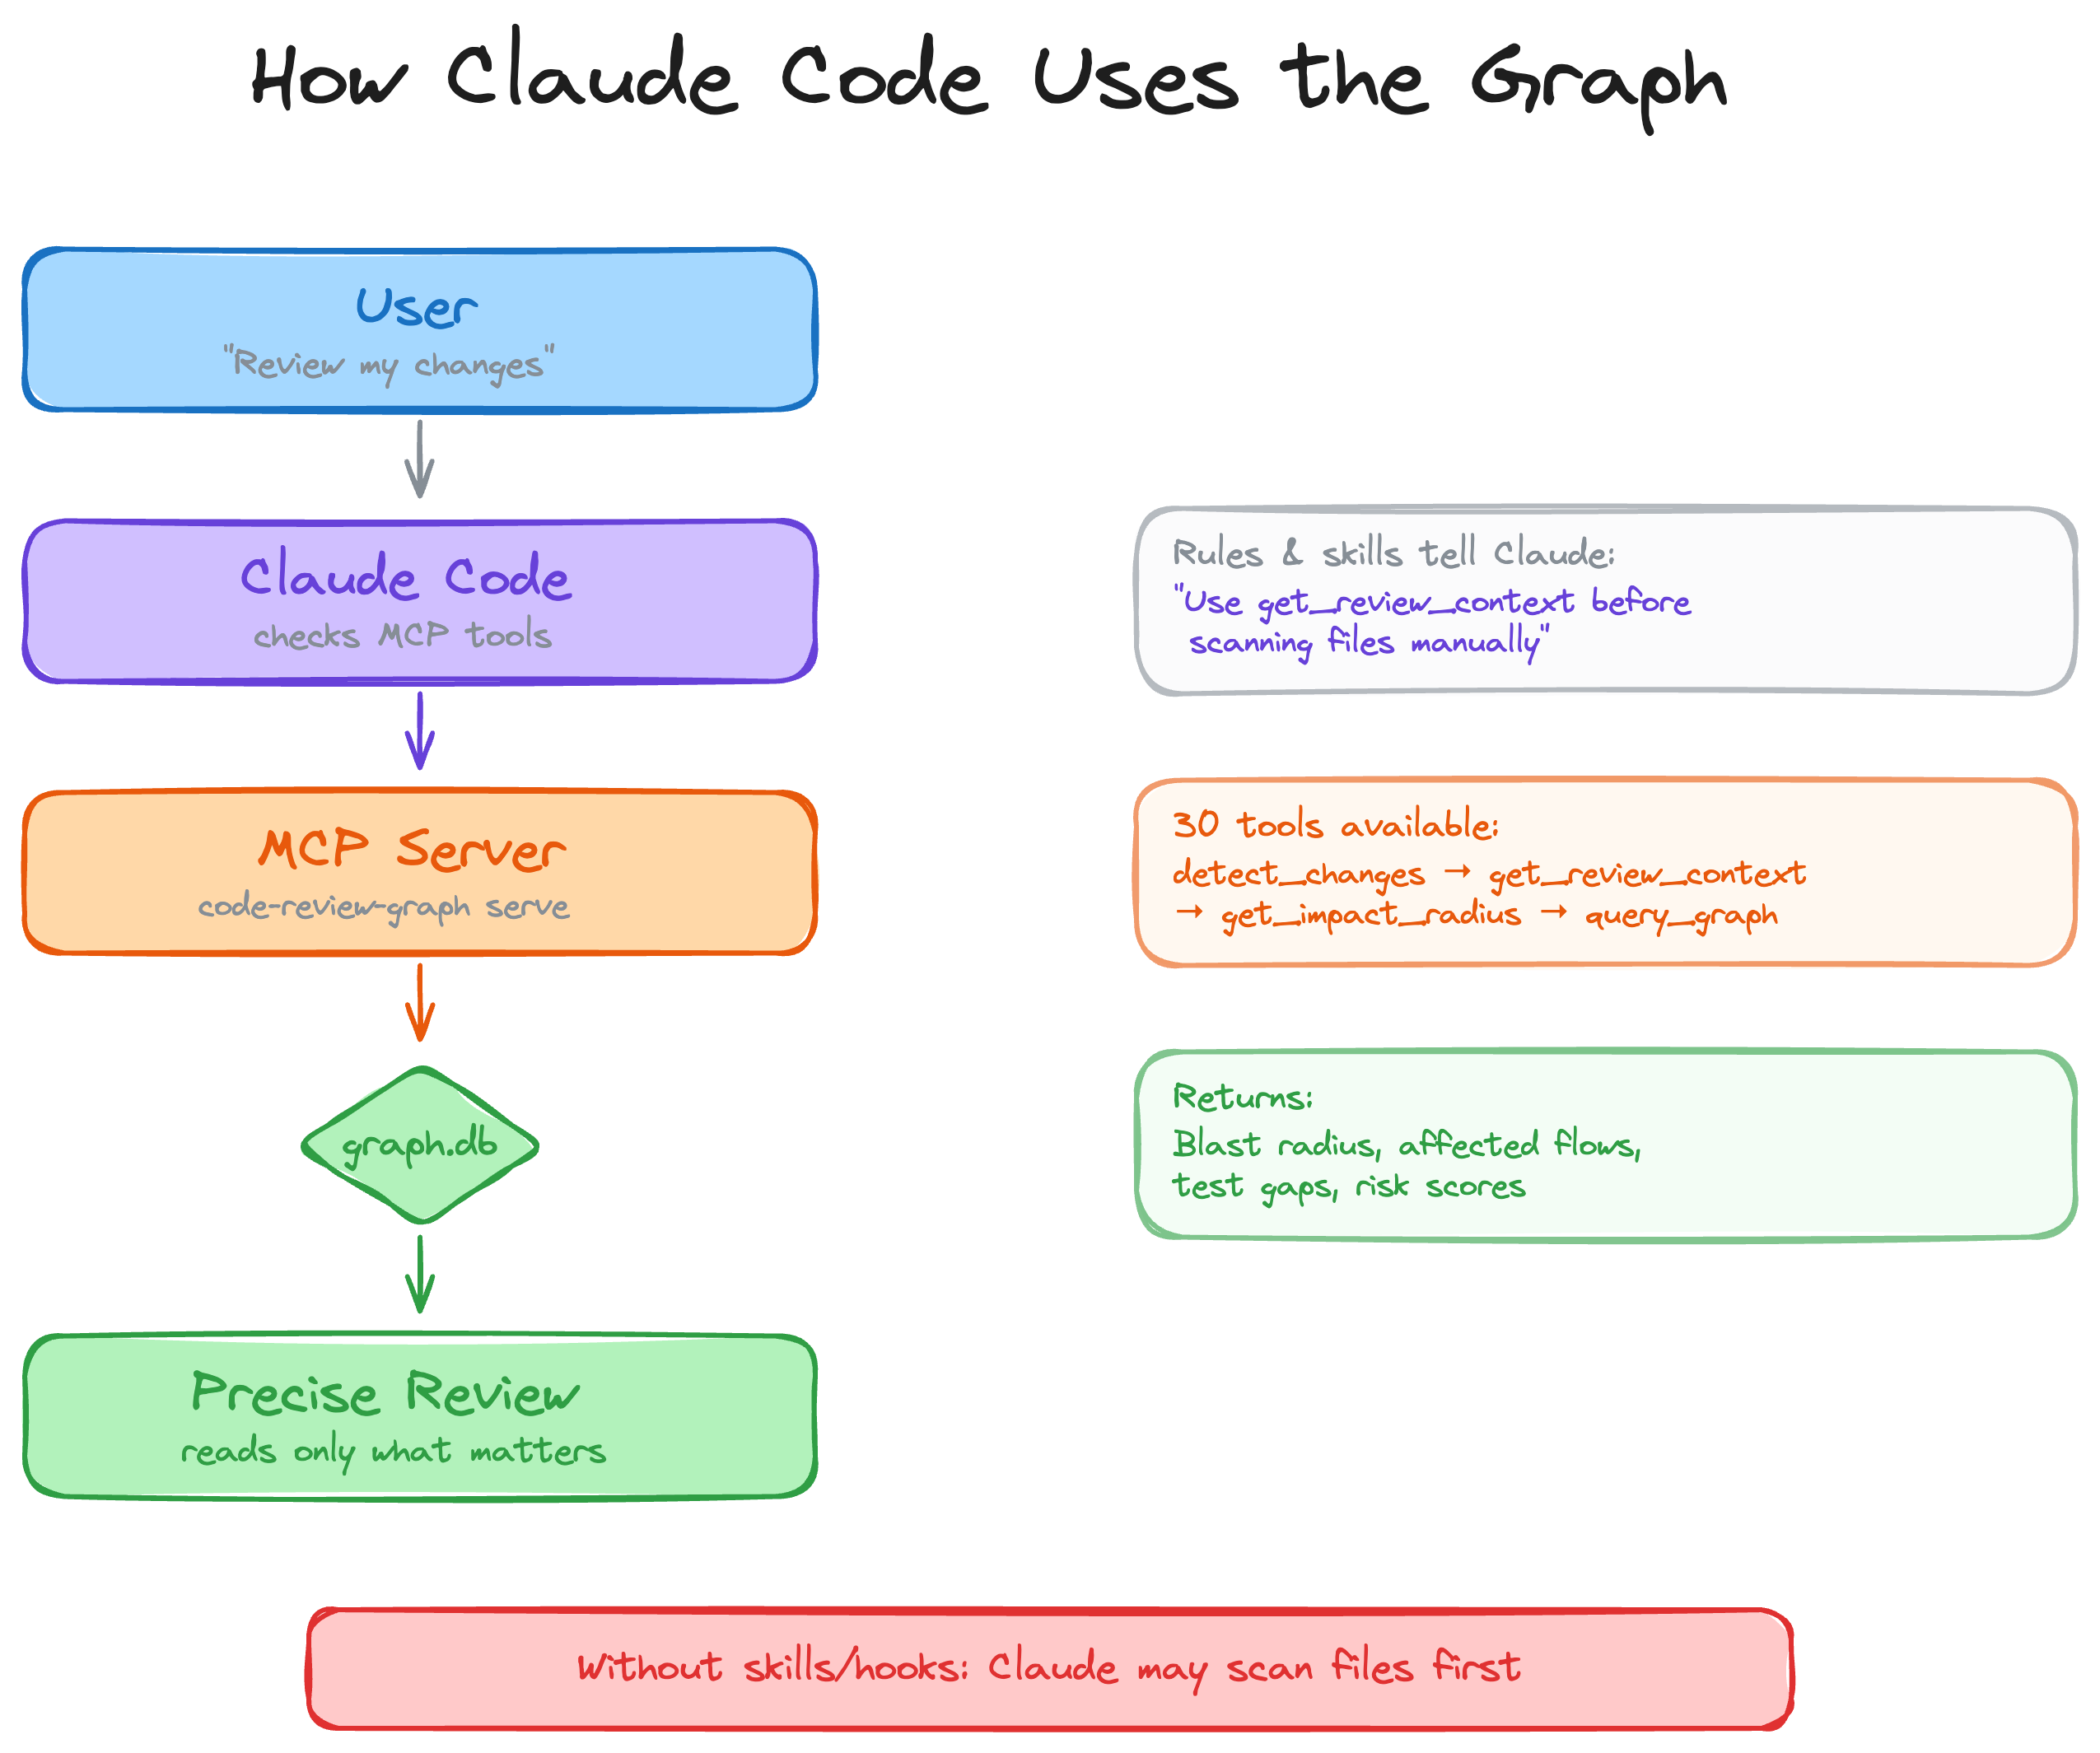
AI coding tools often re-read large parts of a codebase to review a change. code-review-graph builds a structural map of the code with Tree-sitter, keeps it updated incrementally, and serves compact context over MCP, so the assistant reads only the files a change touches.
Quick Start
pip install code-review-graph          # or: pipx install code-review-graph
code-review-graph install              # detect installed AI coding tools and configure each one
code-review-graph build                # parse the codebase
install detects which AI coding tools you have, writes an MCP server entry for each, installs hooks and skills where the platform supports them, and adds graph instructions to the platform's rules file. The MCP entry uses poetry run or uv run inside a Poetry or uv project environment, uvx code-review-graph serve when uvx is on PATH, and otherwise the current Python interpreter. Restart the editor or tool afterwards.
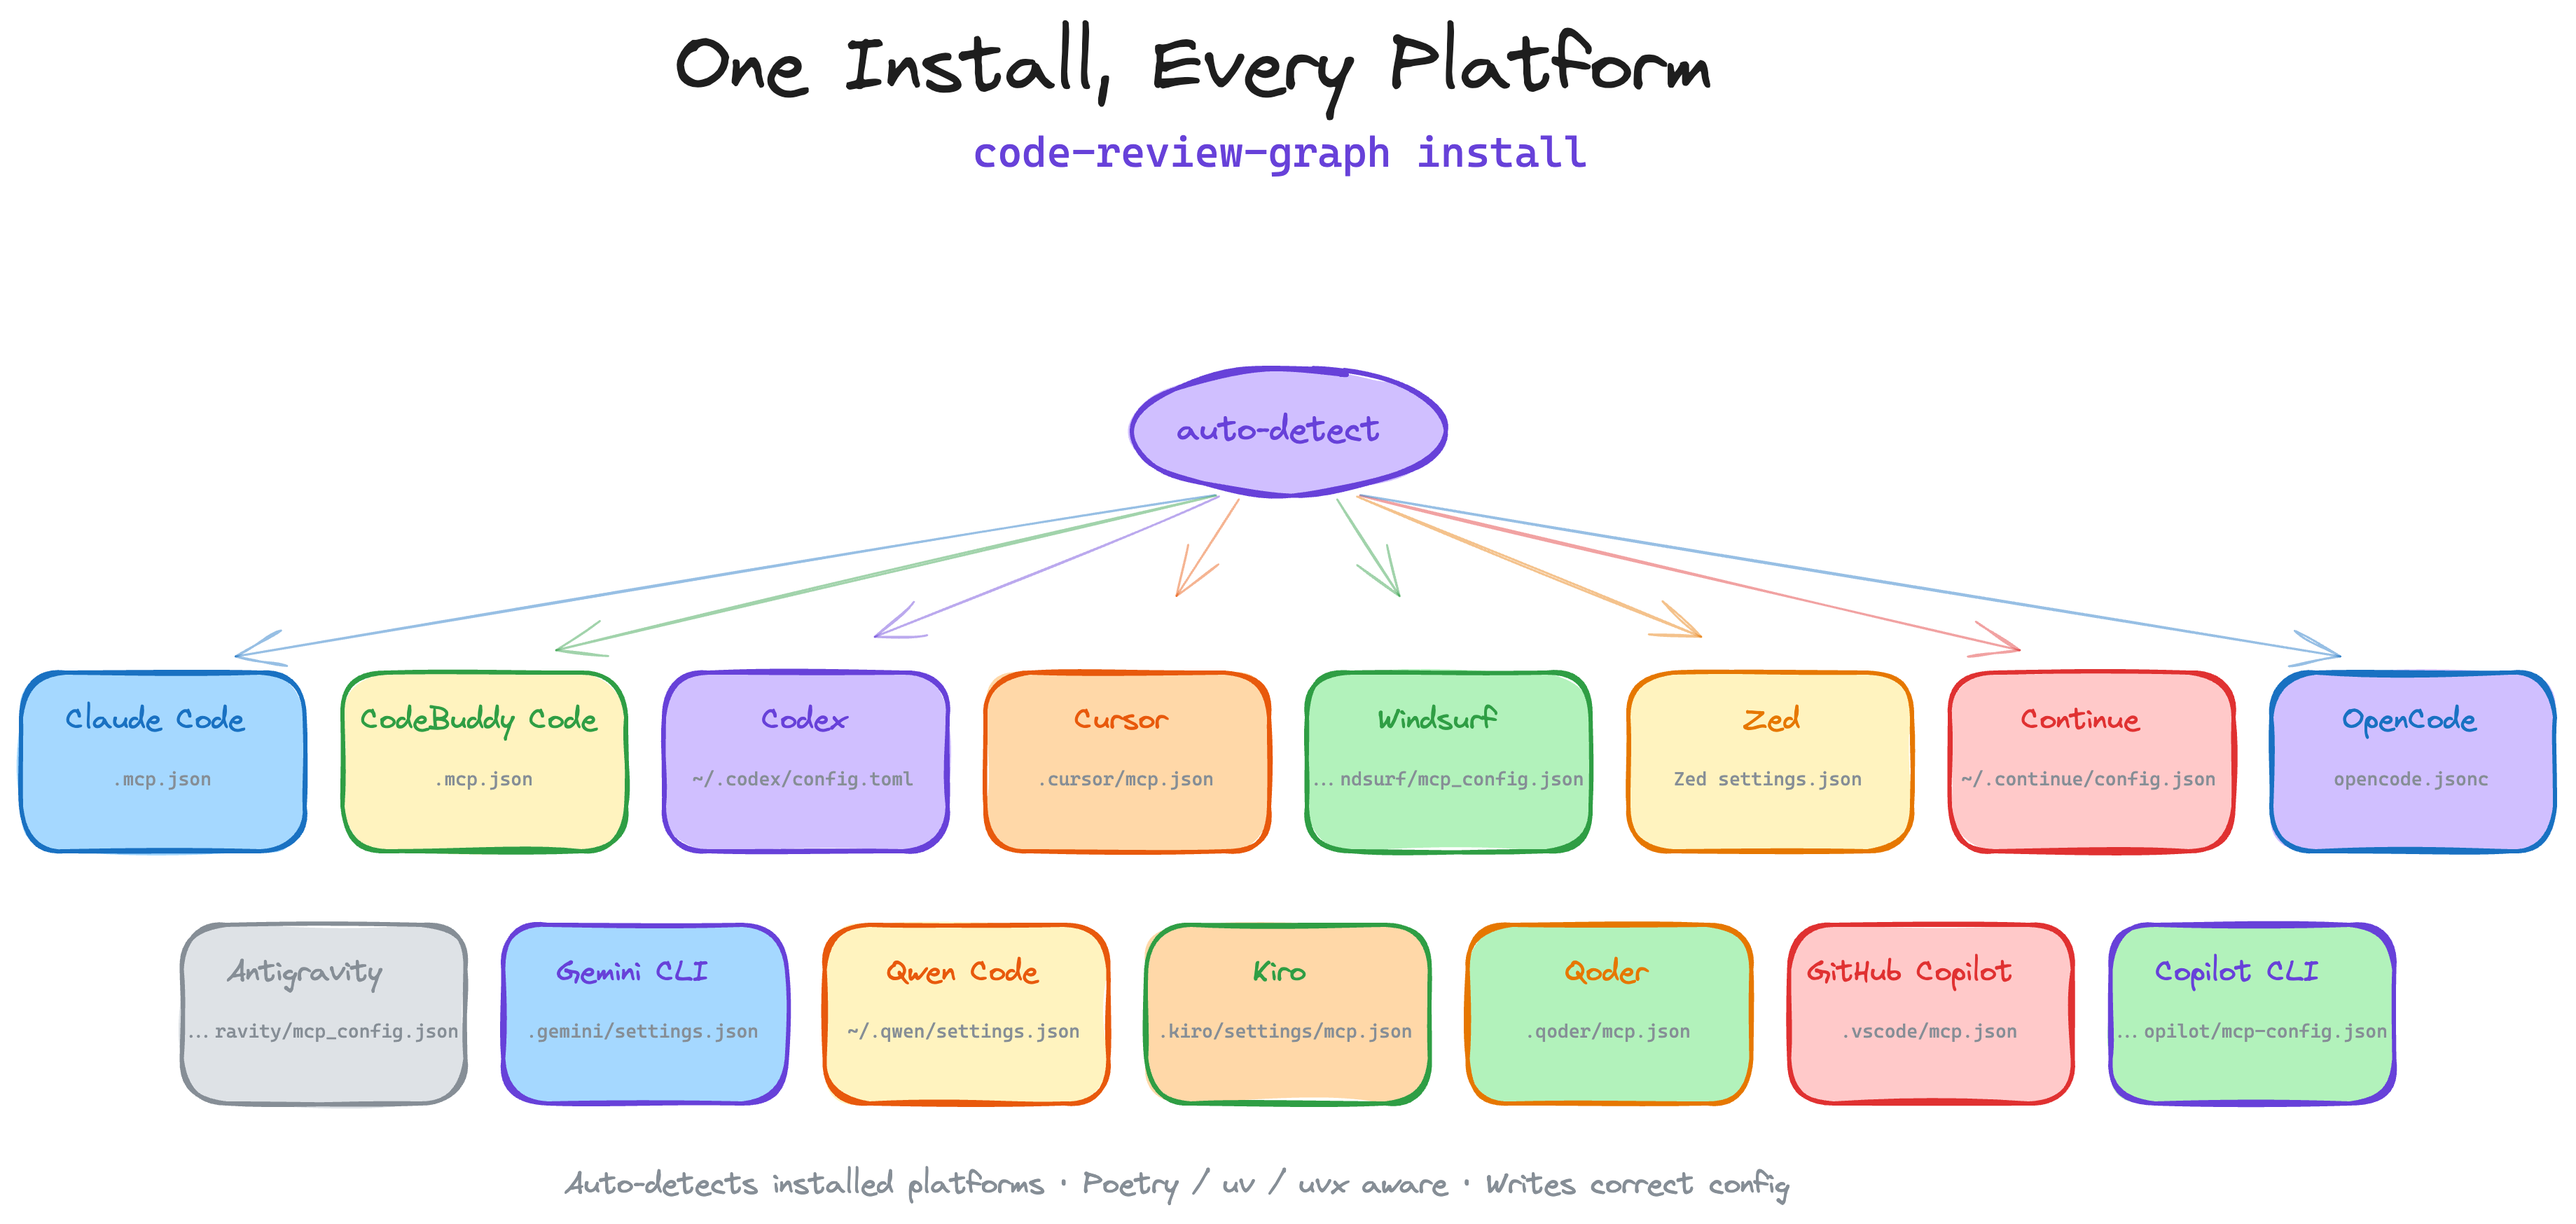
To configure one platform, pass --platform with one of codex, claude-code, cursor, windsurf, zed, continue, opencode, antigravity, gemini-cli, qwen, kiro, qoder, copilot, copilot-cli, codebuddy, or hermes:
code-review-graph install --platform cursor
code-review-graph install --platform codebuddy
Config file locations are listed in docs/USAGE.md. Requires Python 3.10+.
For Codex, the installer also places a global code-review-graph Skill under
$CODEX_HOME/skills/code-review-graph/ (default:
~/.codex/skills/code-review-graph/). It prefers CRG MCP tools and falls back
to the bundled read-only CLI when MCP is unavailable; a missing, empty, or
stale graph never triggers an implicit build or update. WSL and Windows Codex
runtimes have separate CODEX_HOME directories and tool inventories, so
install and refresh the runtime that will execute the task.
uninstall removes CRG-owned files and entries from a Git or SVN working tree and leaves other MCP servers, hooks, skills and JSONC comments alone. Run it from anywhere inside the tree. Shared config files are replaced atomically, so a failed write leaves the original intact.
code-review-graph uninstall --dry-run    # preview only
code-review-graph uninstall              # preview, confirm, apply
code-review-graph uninstall --yes        # apply without prompting
code-review-graph uninstall --all-repos  # also clean every registered repository
code-review-graph uninstall --keep-data  # remove integrations, keep graph databases
code-review-graph uninstall --keep-user-configs --repo .  # this project only
Then open the project and ask the assistant:
Build the code review graph for this project
Build time scales with repository size; a cold build of a ~3,000-file repository took about 40 seconds (measured). After that, hooks and watch mode keep the graph updated. If some files fail to parse, the result has status partial and names them in its summary; the CLI also prints a Warning: line on stderr, and those files keep their previous graph rows.
How It Works
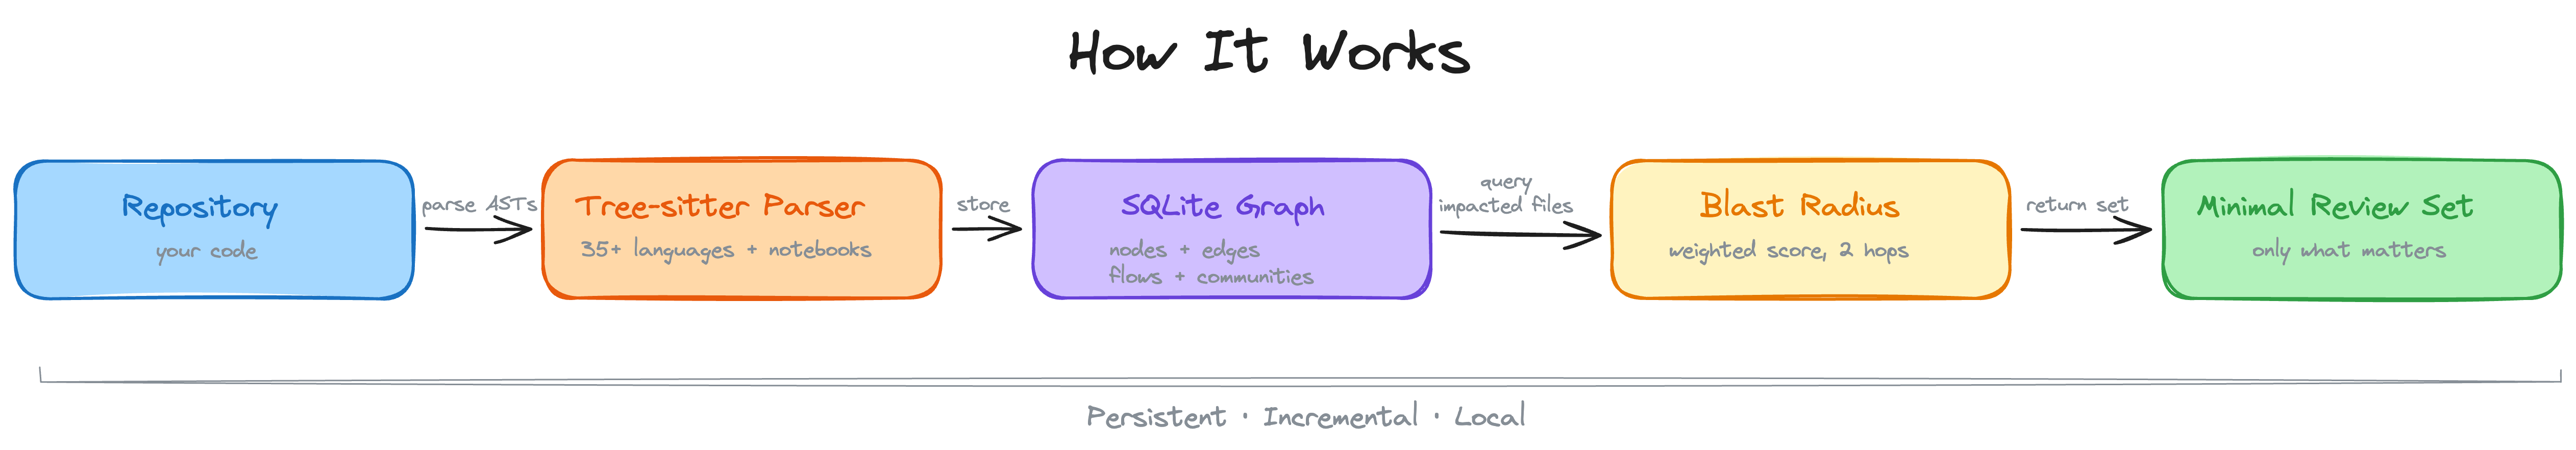
The repository is parsed into ASTs with Tree-sitter and stored as a graph of nodes (functions, classes, imports) and edges (calls, inheritance, test coverage). At review time the graph is queried for the smallest set of files the assistant needs to read.
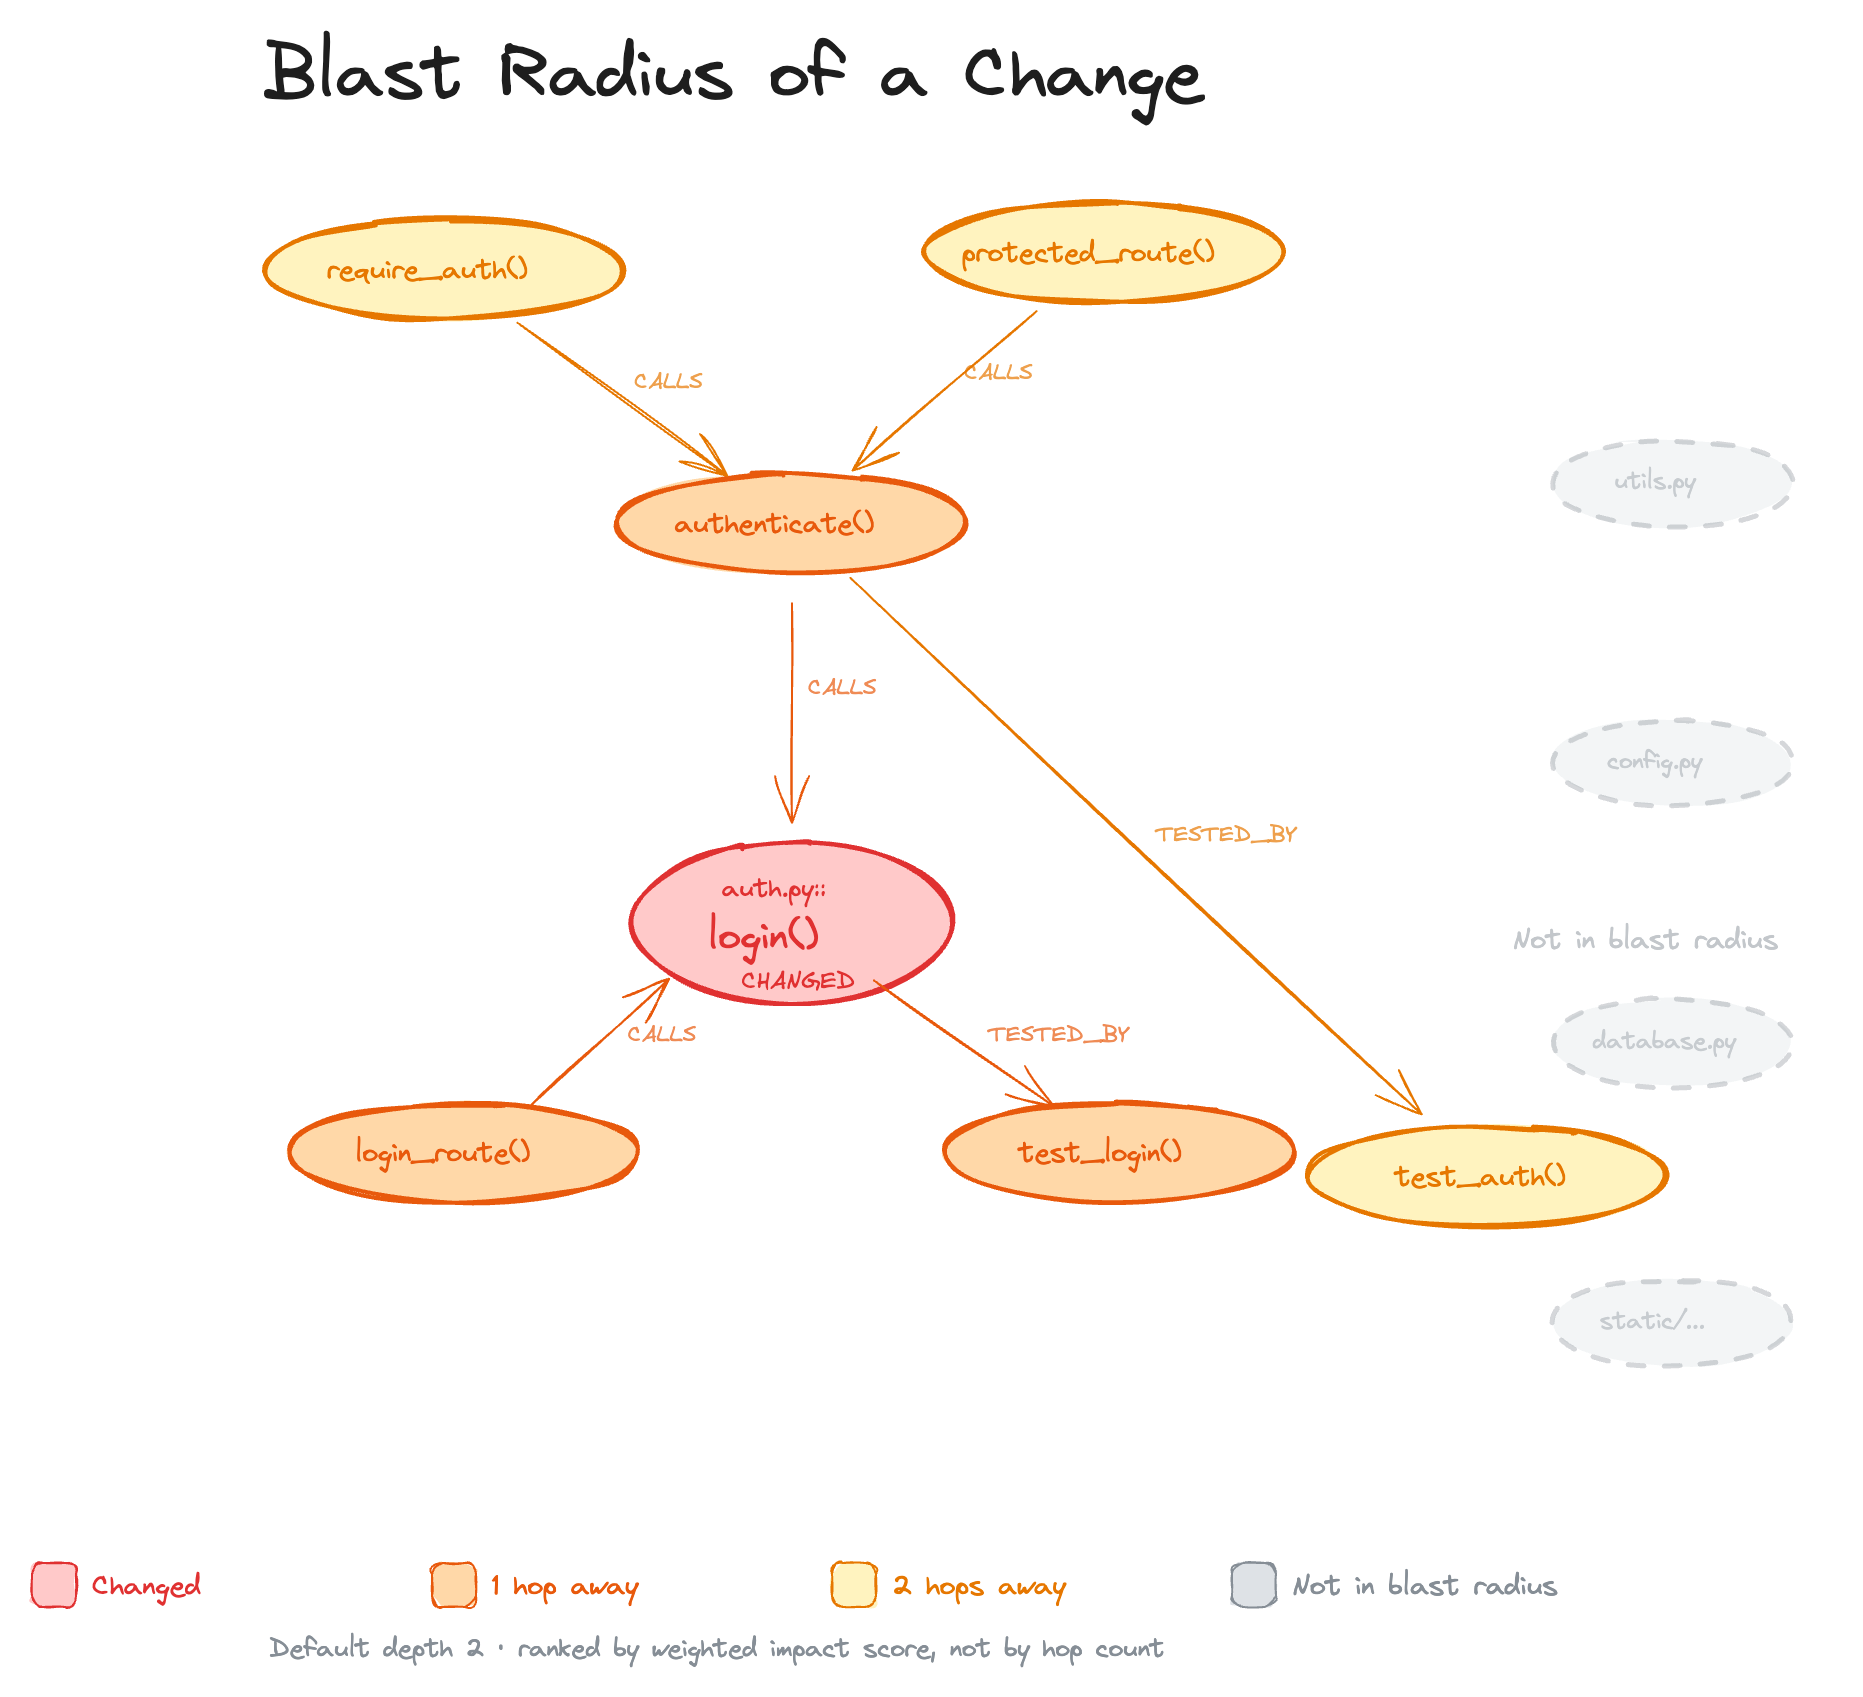
Blast-radius analysis
When a file changes, the graph traces every caller, dependent and test that could be affected. The assistant reads those files instead of scanning the whole project.
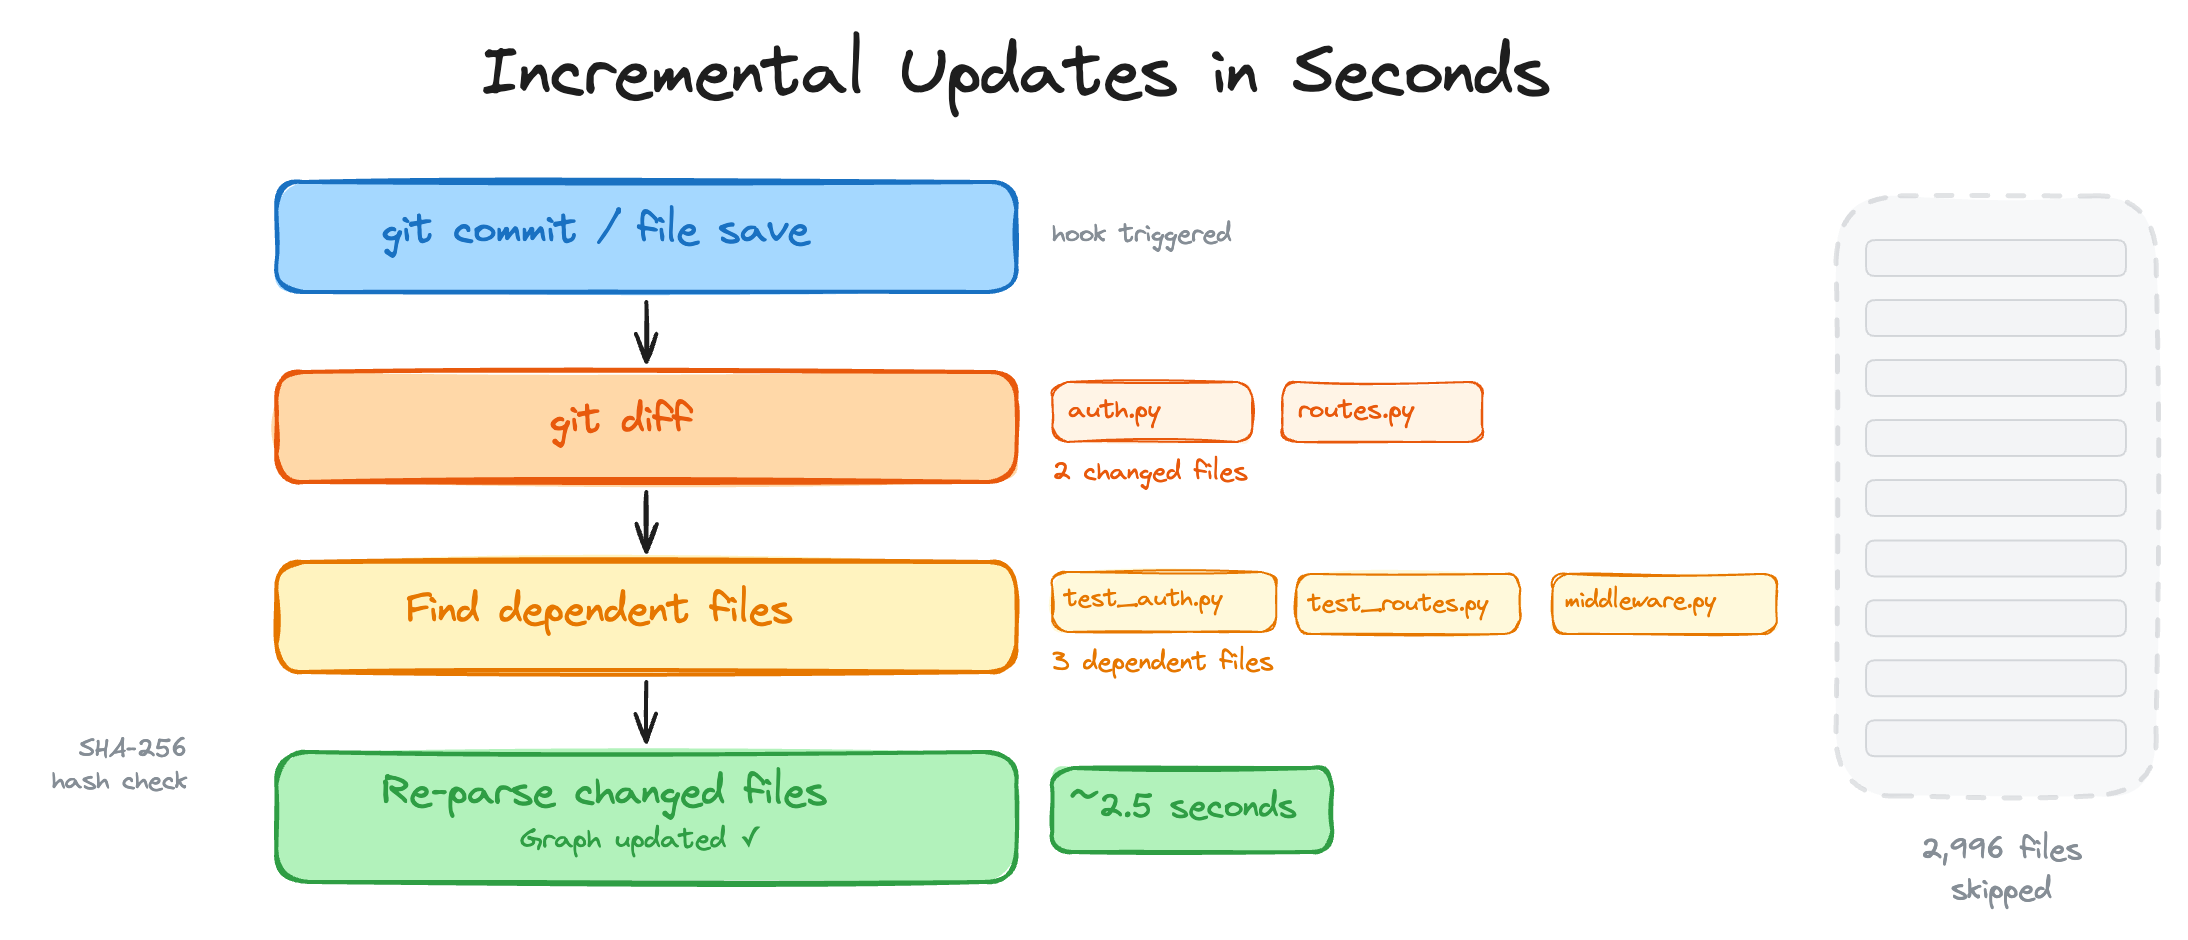
Incremental updates
Hooks, the git hooks (pre-commit, post-checkout, post-merge, post-rewrite) and watch mode trigger incremental updates. The update diffs changed files, finds their dependents through the graph's import and call edges, and re-parses only the files whose SHA-256 hash changed. On a ~3,000-file project (django) a two-file edit re-indexes in about 2.5 seconds on the path the hooks use, of which ~1.4 s is process start-up; a no-op update costs only that start-up. See Incremental update latency.
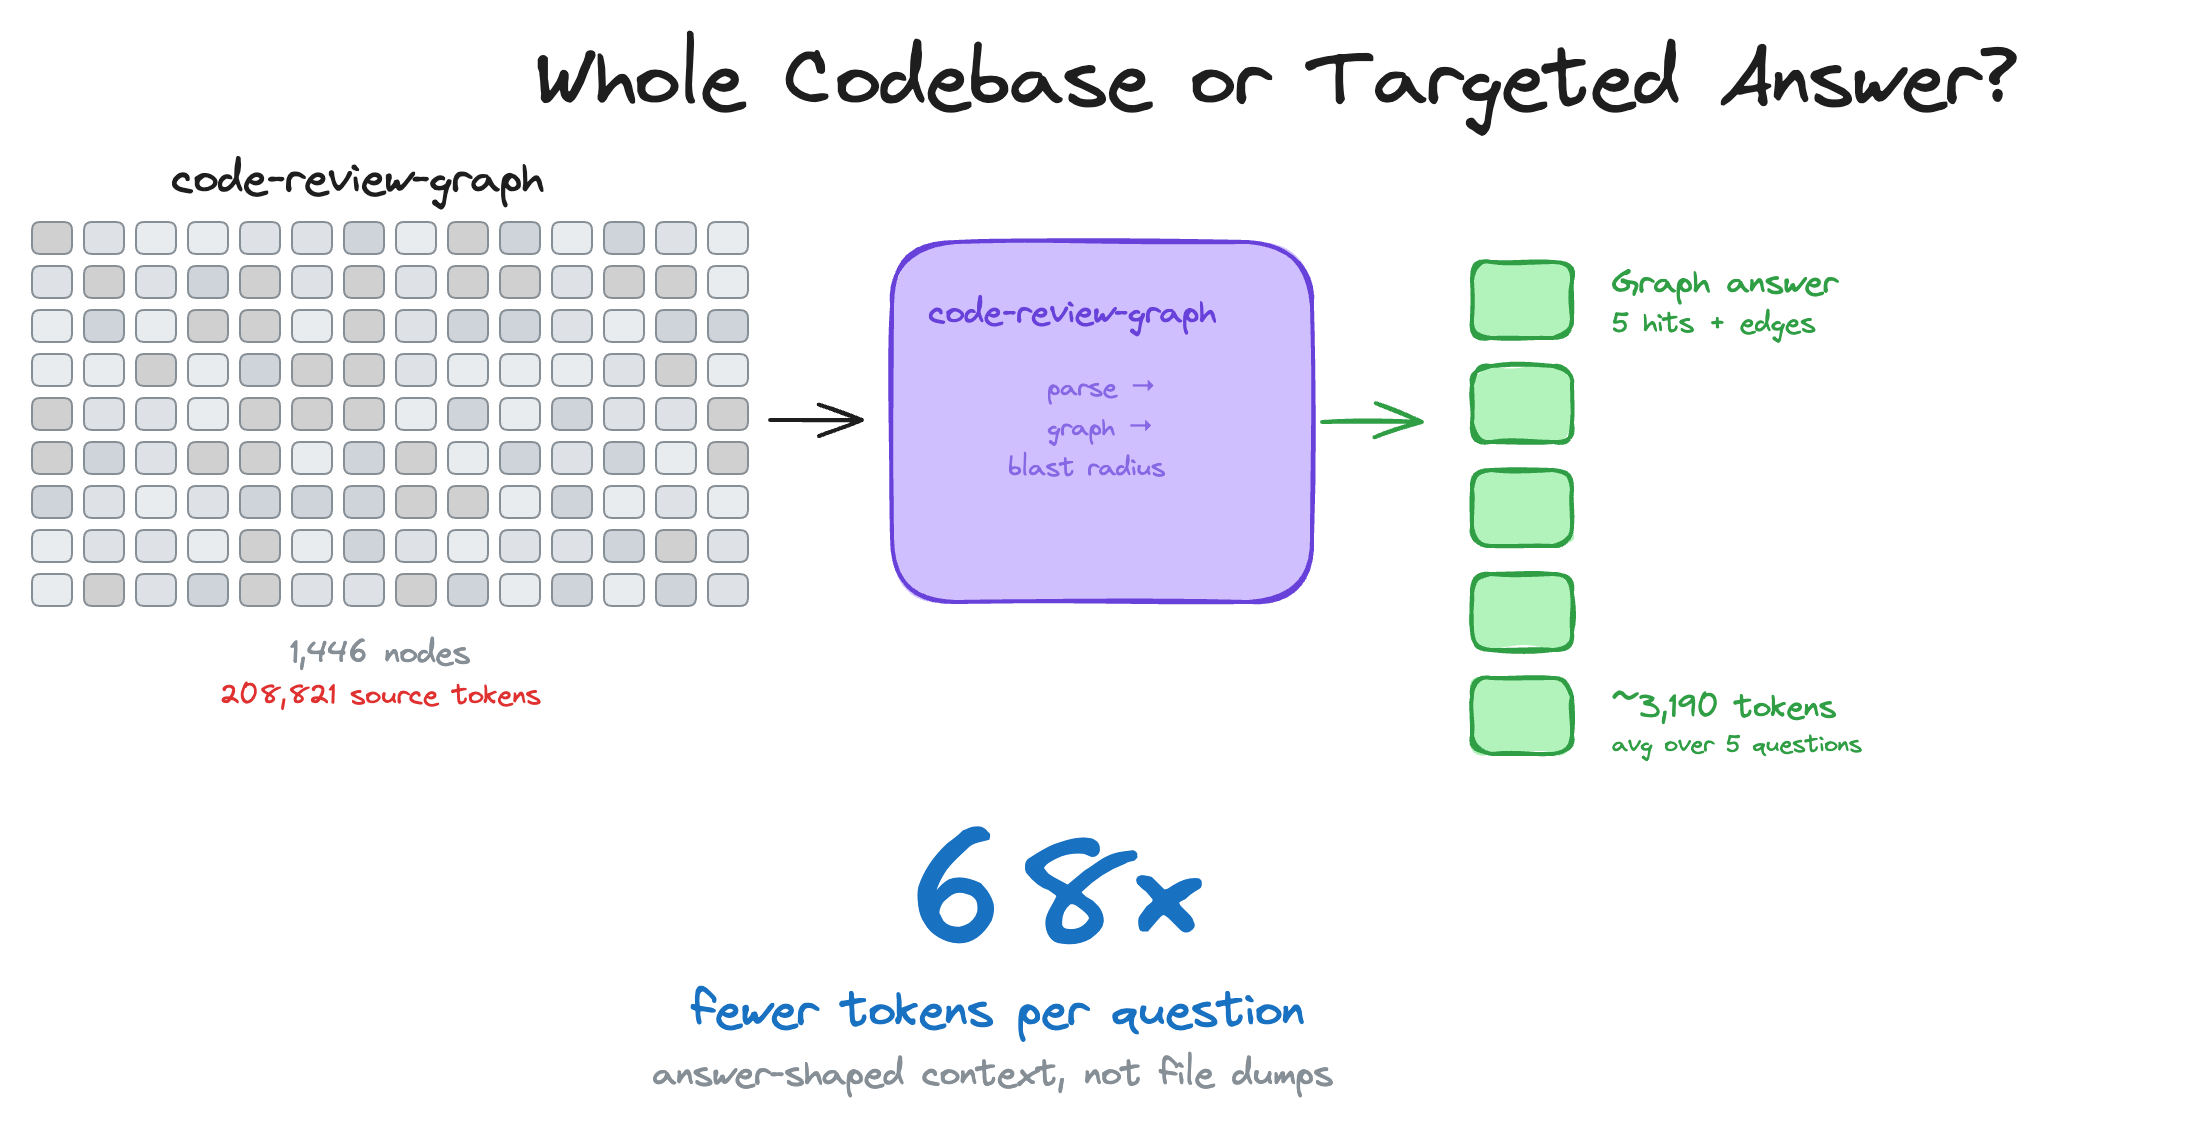
Whole codebase or targeted answer?
Instead of feeding a whole corpus to the model, the graph returns a slice shaped to the question. In the 2026-08-02 capture of this repository at 84bde354, 208,821 source tokens became ~3,190 tokens per question. The repository has grown a lot since that snapshot, so both numbers are larger today.
Language coverage and notebooks
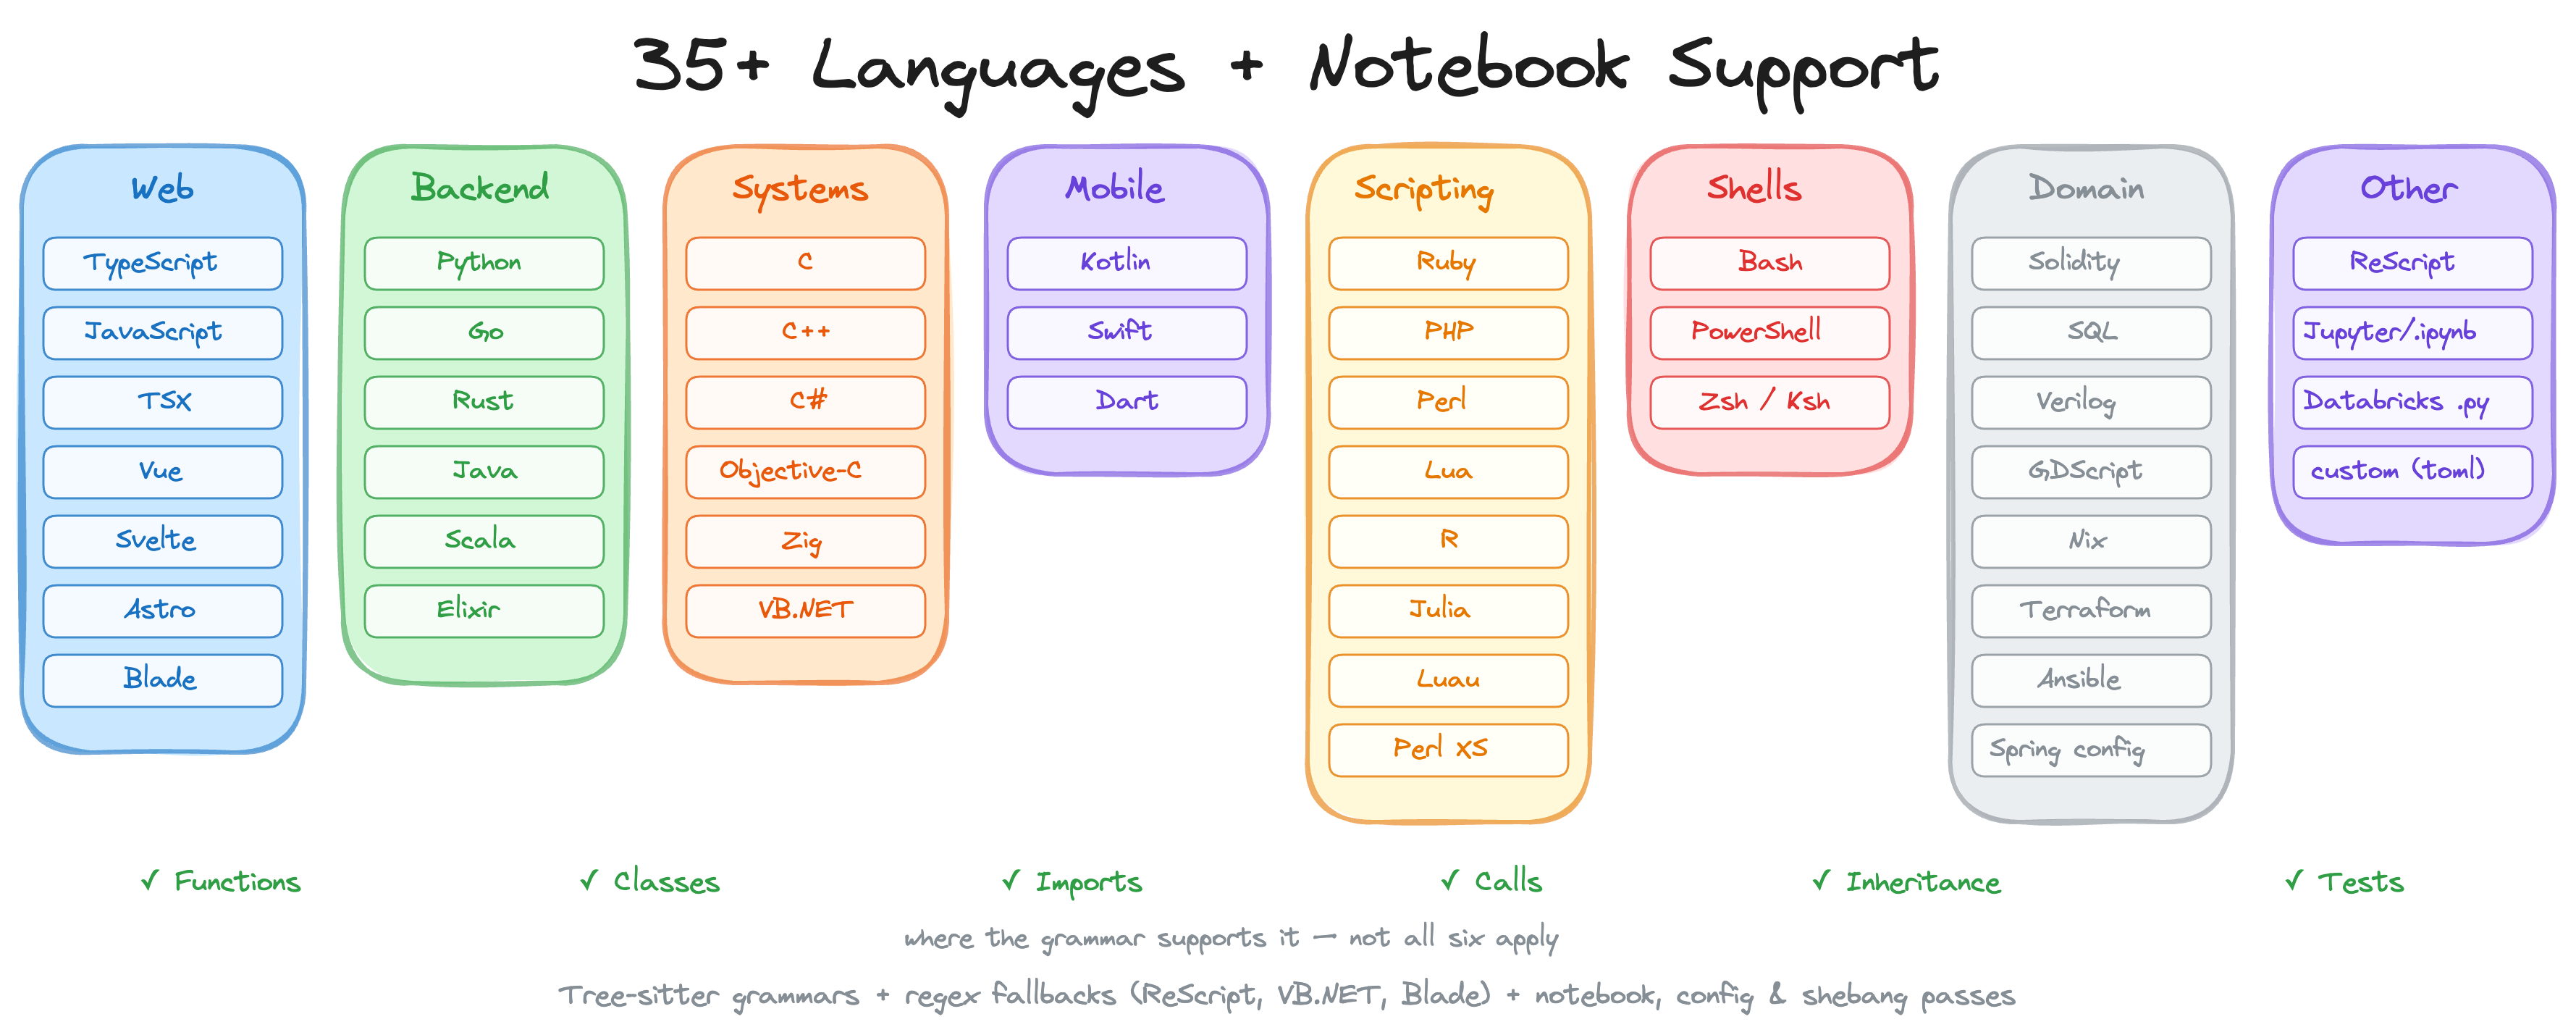
The parser extracts functions, classes, imports, call sites, inheritance and tests, using Tree-sitter where a grammar exists and targeted fallbacks elsewhere. Supported: Python, JavaScript/TypeScript/TSX, Go, Rust, Java, C/C++, C#, VB.NET, Ruby, Kotlin, Swift, PHP, Scala, Solidity, Dart, R, Perl, Lua/Luau, Objective-C, shell scripts, Elixir, Zig, PowerShell, Julia, ReScript, GDScript, Nix, Verilog/SystemVerilog, SQL/PL/SQL (Oracle), Terraform/OpenTofu (.tf; other .hcl files become file nodes only), Ansible YAML (playbooks, roles, tasks), Spring Boot application config (application.properties, application.yml, application.yaml and their application-<profile> variants; key names and value types only, never values), value-free generic YAML structure, Vue/Svelte SFCs, Astro files (parsed with the TypeScript grammar), Jupyter and Databricks notebooks (.ipynb), Perl XS files (.xs), and Robot Framework files (.robot, .resource). Other .properties files are not treated as source code.
PHP projects also get repository-bounded Composer PSR-4 resolution, Blade template references,
and Laravel Route and Eloquent edges when the source shows explicit framework imports, model
inheritance and receiver evidence. Static Laravel routes in routes/*.php emit Endpoint nodes
and controller HANDLES edges, including literal group prefixes.
Java projects get Spring dependency-injection call resolution, request endpoints and WebFlux routes, scheduled triggers, application-event publisher-to-listener edges, and Temporal workflow and activity edges. Each resolver runs after the parse and needs the injected field, published event or workflow stub to be visible in the repository.
Add your own language
If your repository uses a language the parser does not cover, add a languages.toml to .code-review-graph/ that maps file extensions to any grammar bundled in tree_sitter_language_pack, plus the node types for functions, classes, imports and calls:
[languages.erlang]
extensions = [".erl"]
grammar = "erlang"
function_node_types = ["function_clause"]
class_node_types = ["record_decl"]
import_node_types = ["import_attribute"]
call_node_types = ["call"]
The generic tree-sitter walker does the extraction. Built-in languages cannot be overridden. See docs/CUSTOM_LANGUAGES.md for the schema, validation rules and a worked example.
Risk-scored PR reviews in CI (GitHub Action)
The same analysis runs as a composite GitHub Action. The graph is built and queried on your CI runner; no source code is sent to an external service. On each pull request the action posts one sticky comment with risk-scored functions, affected execution flows and test gaps, updated in place on every push. The optional fail-on-risk input turns it into a merge gate.
# .github/workflows/code-review-graph.yml
on:
  pull_request:

permissions:
  contents: read
  pull-requests: write

jobs:
  review:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v7
      - uses: tirth8205/code-review-graph@v2.3.9
        with:
          github-token: ${{ secrets.GITHUB_TOKEN }}
See docs/GITHUB_ACTION.md for inputs, risk levels and caching, or the workflow this repository runs on itself in .github/workflows/pr-review.yml.
Benchmarks
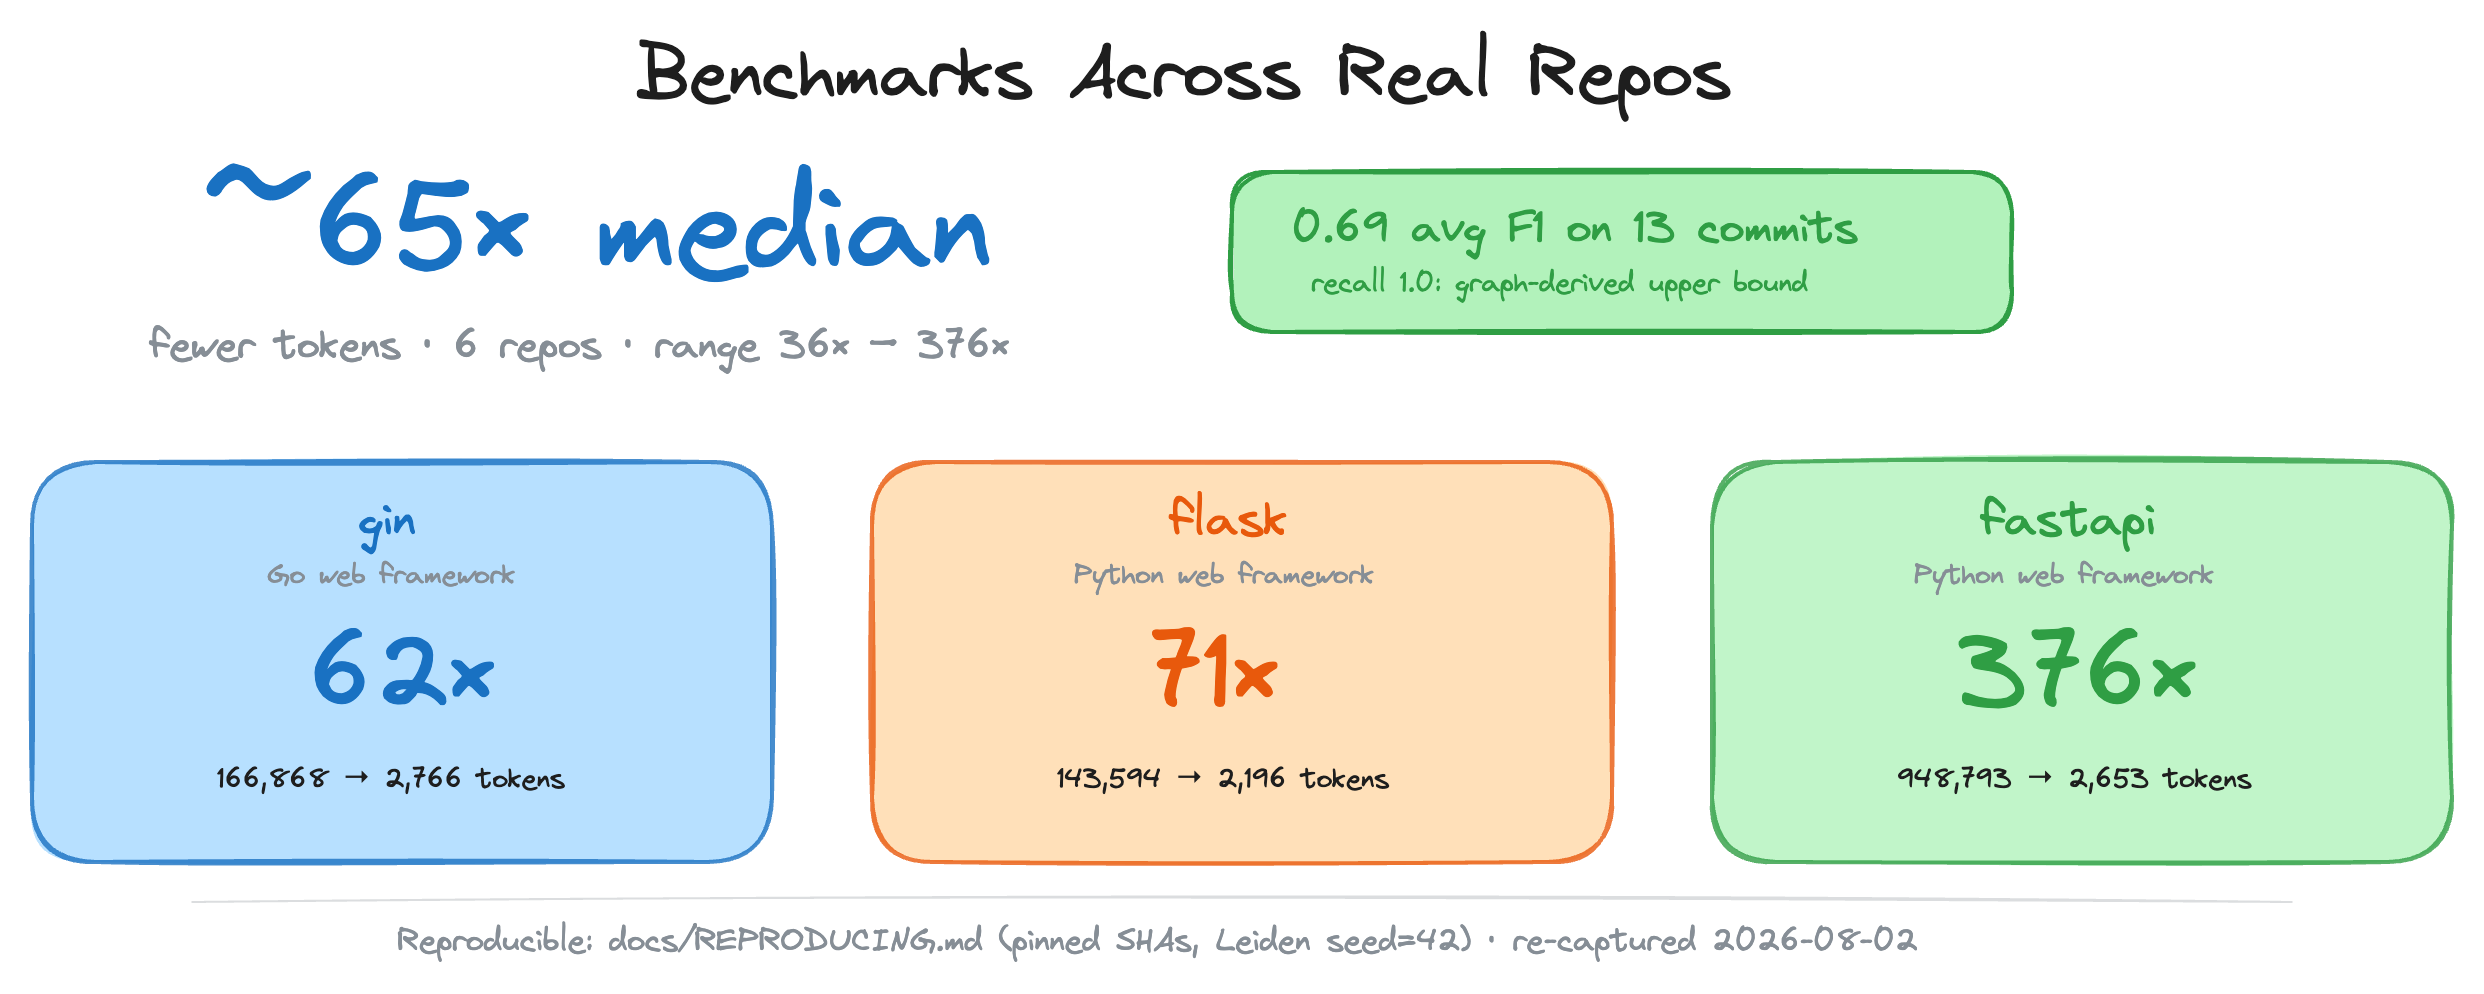
The median per-question token reduction across the 6 repositories is about 63x (whole-corpus baseline vs graph query). The 358x maximum is one repository (fastapi, the largest corpus), not the typical result.
All numbers come from the evaluation runner against 6 open-source repositories (13 commits). Every config pins an upstream SHA, Leiden runs with a fixed seed, and embeddings are deterministic on CPU, so two runs on different machines produce the same numbers. The reproduction recipe is in docs/REPRODUCING.md. A weekly report-only run on the two smallest configs lives in .github/workflows/eval.yml.
Token efficiency: ~63x median per-question reduction (range 35x to 358x; whole-corpus vs graph query)
For a typical agent question ("how does authentication work", "what is the main entry point", and so on), the graph returns ~2,200 to 3,900 tokens of search hits plus neighbour edges instead of every source file. The table averages the 5 sample questions defined in code_review_graph/token_benchmark.py.
| Repo | Snapshot SHA | naive_corpus_tokens | avg graph_tokens | Reduction |
|---|---|---|---|---|
| fastapi | 22381558 |
948,793 | 2,653 | 357.6x |
| flask | a29f88ce |
143,594 | 2,196 | 65.4x |
| code-review-graph | 84bde354 |
208,821 | 3,190 | 65.5x |
| gin | 5c00df8a |
166,868 | 2,766 | 60.3x |
| httpx | b55d4635 |
142,356 | 2,661 | 53.5x |
| express | b4ab7d65 |
136,052 | 3,936 | 34.6x |
Captured 2026-08-02 from clean clones at the pinned SHAs (crg 2.3.7, local
all-MiniLM-L6-v2embeddings). These numbers are lower than the 2026-05-25 capture they replace: node embedding text became richer, soavg graph_tokensrose in every repo. fastapi is measured at its current pin22381558rather than the retired0227991a.The Reduction column is
naive_corpus_tokens / avg graph_tokens, so it divides out from the two columns beside it. The benchmark's ownaverage_reduction_ratioaverages the five per-question ratios instead, which always reads higher; those per-question figures are indocs/REPRODUCING.md.The
code-review-graphrow is a snapshot, not a current measurement. The repository has grown since84bde354, so its corpus and graph are both much larger today.
The whole-corpus baseline is an upper bound no real agent pays; an agent greps for identifiers and reads the best-matching files. The agent_baseline eval benchmark measures that case (a pure-Python grep over the corpus, top-3 files by match count, token-counted against the graph query cost). Against that realistic baseline the median across 18 questions on 6 repositories is 6.65x (mean 14.8x, range 4.2x to 72.6x), captured 2026-09-22, before search and this baseline began ranking test files lower, so code-review-graph eval --benchmark agent_baseline --embed now gives different numbers until the capture is redone. The full table is in docs/REPRODUCING.md, under "Canonical capture, 2026-09-22".
The ratio tracks repository size, because the graph answer stays flat (2,432 to 4,021 tokens across every repo measured) while the grep baseline grows with the corpus: 4.5x on express, 52x on fastapi. Both figures measure retrieval cost, the tokens needed to locate an answer. An agent that then opens the files the graph named pays the graph on top of its usual reads rather than instead of them; semantic_search_nodes_tool(include_source=True) returns the code with the locations so it does not have to, and measuring that path end-to-end is open work.
The formal token_efficiency benchmark measures a different scenario, the full get_review_context() JSON against only the changed-file content of a commit, and reports ratios below 1 for small commits because the response carries impact-radius edges and source snippets. The two benchmarks answer different questions; see docs/REPRODUCING.md.
Review and impact tools attach a compact context_savings estimate to their responses. The CLI shows the same figures in the Token Savings panel (see Usage below) and --verify compares them with OpenAI's cl100k_base tokenizer. Calibration across 222 sample files puts the estimate within about 1% of real tokens in aggregate (data).
Impact accuracy: 0.69 average F1 against graph-derived ground truth (recall 1.0 is a circular upper bound)
Blast-radius analysis recovers every file in the ground truth on all 13 evaluation commits. Read that as an upper bound, not as "100% recall": the ground truth (changed files plus files with call or import edges into them) comes from the same graph the predictor traverses. The lower precision is deliberate; flagging an extra file costs less than missing a broken dependency.
| Repo | Commits | Avg F1 | Avg Precision | Recall (graph-derived upper bound) |
|---|---|---|---|---|
| httpx | 2 | 0.863 | 0.785 | 1.0 |
| code-review-graph | 2 | 0.734 | 0.584 | 1.0 |
| fastapi | 2 | 0.697 | 0.539 | 1.0 |
| express | 2 | 0.667 | 0.500 | 1.0 |
| flask | 2 | 0.633 | 0.485 | 1.0 |
| gin | 3 | 0.609 | 0.439 | 1.0 |
| Average | 13 | 0.693 | 0.546 | 1.000 |
The benchmark also runs a co-change mode: the predictor is seeded with one changed file and graded against the other files the author touched in the same commit, which is evidence from git history rather than from the graph. Both modes appear in the result CSVs (ground_truth_mode column). In the 2026-08-02 capture co-change mode returned predicted_files = 0 on every graded commit, so it is not yet a usable measurement and no co-change number is quoted.
Build stats
From the same 2026-08-02 clean-room build at the pinned SHAs above. Embedding counts are lower than node counts because File nodes are not embedded. The code-review-graph row is that snapshot, not the repository as it stands now.
| Repo | Nodes | Edges | Embeddings |
|---|---|---|---|
| fastapi | 6,287 | 32,036 | 5,159 |
| express | 1,990 | 19,492 | 1,849 |
| gin | 1,589 | 17,237 | 1,491 |
| code-review-graph | 1,446 | 9,094 | 1,354 |
| flask | 1,415 | 8,259 | 1,329 |
| httpx | 1,263 | 8,236 | 1,193 |
Limitations
- Impact "recall 1.0" is circular. The historical ground truth comes from the same graph edges the predictor walks, so it is an upper bound by construction. The co-change mode is not yet a usable measurement.
- Small single-file changes. Graph context can exceed a plain file read for trivial edits. The overhead is the structural metadata that makes multi-file analysis possible.
- Search ranking. Keyword search usually finds the right result near the top, but ranking needs work. Express queries can return no hits because of module-pattern naming.
- Flow detection. Entry-point detection is strongest for Python and PHP/Laravel. JavaScript and Go flow detection needs work.
- Precision vs recall. Impact analysis is conservative. It flags files that might be affected, which means false positives in large dependency graphs.
Features
| Feature | Details |
|---|---|
| Incremental updates | Re-parses only files whose hash changed. On a ~3,000-file repo a two-file edit takes ~2.5 s on the hook path (measured). |
| Language and notebook support | See Language coverage above. |
| Framework-aware PHP parsing | Repository-bounded Composer PSR-4 imports, Blade template references, evidence-gated Laravel Route-to-controller and Eloquent relationship edges |
| Framework-aware Java parsing | Spring dependency-injection call resolution, request endpoints and WebFlux routes, scheduled triggers, application-event publisher-to-listener edges, Temporal workflow and activity edges, and Spring Boot config keys indexed without their values |
| Blast-radius analysis | Which functions, classes and files are likely affected by a change |
| Auto-update hooks | Editor hooks, git hooks (before each commit, after checkout, merge and rebase) and watch mode update the graph as you work |
| Semantic search | Optional vector embeddings via sentence-transformers, Google Gemini, MiniMax, Voyage AI, or any OpenAI-compatible endpoint (OpenAI, Azure, new-api, LiteLLM, vLLM, LocalAI) |
| Interactive visualisation | D3.js force-directed graph with search, community legend toggles and degree-scaled nodes |
| Hub and bridge detection | Most-connected nodes and chokepoints (betweenness centrality) |
| Surprise scoring | Unexpected coupling: cross-community, cross-language, peripheral-to-hub edges |
| Knowledge gap analysis | Isolated nodes, untested hotspots, thin communities |
| Suggested questions | Review questions generated from bridges, hubs and surprises |
| Edge confidence | Two-tier confidence (EXTRACTED/INFERRED) with float scores on edges |
| Graph traversal | BFS/DFS from any node with configurable depth and token budget |
| Export formats | GraphML (Gephi/yEd), Neo4j Cypher, Obsidian vault, JSON, and SVG (SVG needs matplotlib from the eval extra) |
| Token benchmarking | code_review_graph/token_benchmark.py measures whole-corpus tokens against graph query tokens per question |
| Estimated context savings | context_savings metadata (estimated, saved_tokens, saved_percent) on review, impact, detect-changes and architecture responses |
| Community auto-split | Communities above 25% of the graph are split recursively with Leiden |
| Execution flows | Call chains from entry points, sorted by weighted criticality |
| Community detection | Leiden clustering with resolution scaled to graph size |
| Architecture overview | Community-based architecture map with coupling warnings |
| Risk-scored reviews | detect_changes maps diffs to affected functions, YAML paths, flows and test gaps |
| Custom languages | New languages via .code-review-graph/languages.toml, no fork needed |
| GitHub Action | Sticky risk-scored PR review comments in CI, with an optional fail-on-risk merge gate |
| Refactoring tools | Rename preview, framework-aware dead code detection, community-driven suggestions |
| Wiki generation | Markdown wiki from community structure |
| Multi-repo registry | Register several repos and search across them |
| Multi-repo daemon | crg-daemon watches several repos as child processes, with health checks and restart |
| MCP prompts | 5 workflow templates: review, architecture, debug, onboard, pre-merge |
| Full-text search | FTS5 hybrid search combining keyword and vector similarity |
| Local storage | One SQLite file in .code-review-graph/; no external database or cloud service |
Usage
Skills
install writes these four skills for the platforms that support them (Claude Code, Gemini CLI, CodeBuddy Code, Hermes Agent and Qoder). Ask for one by name.
| Skill | Description |
|---|---|
explore-codebase |
Navigate and understand codebase structure using the knowledge graph |
review-changes |
Perform a structured code review using change detection and impact |
debug-issue |
Systematically debug issues using graph-powered code navigation |
refactor-safely |
Plan and execute safe refactoring using dependency analysis |
Qoder also gets build-graph, review-delta and review-pr from the repository's skills/ directory.
CLI reference
code-review-graph install          # Detect and configure all platforms
code-review-graph install --platform <name>  # One platform
code-review-graph uninstall --dry-run  # Preview removal of installed artifacts
code-review-graph build            # Parse the whole codebase
code-review-graph update           # Incremental update (changed files only)
code-review-graph status           # Graph statistics
code-review-graph watch            # Update on file changes
code-review-graph forget <path>    # Drop already-parsed files from the graph
code-review-graph dead-code        # Functions and classes with no callers or tests
code-review-graph visualize        # Interactive HTML graph
code-review-graph visualize --format json      # Export graph data as JSON
code-review-graph visualize --format graphml   # Export as GraphML
code-review-graph visualize --format svg       # Export as SVG (needs matplotlib)
code-review-graph visualize --format obsidian  # Export as Obsidian vault
code-review-graph visualize --format cypher    # Export as Neo4j Cypher
code-review-graph wiki             # Markdown wiki from communities
code-review-graph detect-changes --brief         # Risk panel + token savings (read-only)
code-review-graph detect-changes --brief --base main  # Against the merge base of main and HEAD
code-review-graph update --brief                 # Refresh graph + same panel
code-review-graph detect-changes --brief --verify  # Cross-check against tiktoken
code-review-graph register <path>  # Register repo in the multi-repo registry
code-review-graph unregister <path|alias>  # Remove repo from the registry
code-review-graph repos            # List registered repositories
code-review-graph daemon start     # Start the multi-repo watch daemon
code-review-graph daemon stop      # Stop the daemon
code-review-graph daemon status    # Daemon status and repos
code-review-graph eval             # Run evaluation benchmarks
code-review-graph serve            # Start the MCP server (stdio)
code-review-graph serve --http     # MCP over Streamable HTTP on localhost:5555
This is a selection. code-review-graph --help lists every command, and docs/COMMANDS.md documents their flags.
When detect-changes --base names a branch, the diff runs against the merge base of that branch and HEAD. Commit hashes and other revisions are used as given.
visualize --format svg needs matplotlib, which ships in the eval extra (pip install "code-review-graph[eval]"). The other export formats need no extra install.
JSON exports are written inside the local graph data directory, which Git ignores by default. They can contain absolute paths and code-structure metadata, so inspect an export before publishing it.
Token Savings panel: detect-changes --brief vs update --brief
Both commands print the same panel showing how many tokens the graph saved compared with handing the changed files to an agent raw. They differ in one thing: whether the graph is refreshed first.
┌─────────────────────── Token Savings ────────────────────────┐
│ Full context would be:     12,921 tokens                     │
│ Graph context used:           762 tokens                     │
│ Saved:                     12,159 tokens (~94%)              │
│ Breakdown: Functions 244 · Tests 191 · Risk 244 · Other 83   │
└──────────────────────────────────────────────────────────────┘
| Command | What it does | When to use |
|---|---|---|
detect-changes --brief |
Read-only. Queries the existing graph for the current changes and prints the panel. | Most of the time; hooks or crg-daemon keep the graph fresh. |
update --brief |
Re-parses the changed files into the graph first, then prints the same panel. | After a rebase, a large change set, or whenever the graph may be stale. |
Add --verify to either command to compare the figures with OpenAI's cl100k_base tokenizer (needs pip install tiktoken). The estimate is within about 1% of real tokens in aggregate; see docs/REPRODUCING.md.
The same context_savings metadata is attached to the JSON responses of the get_impact_radius, get_review_context, detect_changes and get_architecture_overview MCP tools.
Multi-repo daemon
If your editor does not support hooks (for example Cursor or OpenCode), or you want the graph kept fresh without editor integration, the daemon watches your repositories and updates their graphs. It ships with code-review-graph; no separate install.
# 1. Register the repos to watch
crg-daemon add ~/project-a --alias proj-a
crg-daemon add ~/project-b

# 2. Start the daemon (runs in the background)
crg-daemon start

# 3. Check on it
crg-daemon status                 # daemon and per-repo watcher status
crg-daemon logs --repo proj-a -f  # tail logs for one repo
crg-daemon stop                   # stop the daemon and all watchers
Also available as code-review-graph daemon start|stop|status|....
crg-daemon add writes to ~/.code-review-graph/watch.toml, which you can also edit directly:
[[repos]]
path = "/home/user/project-a"
alias = "proj-a"

[[repos]]
path = "/home/user/project-b"
alias = "project-b"
The daemon watches this file and starts or stops watcher processes as repos are added or removed. A health check every 30 seconds restarts dead watchers.
See docs/COMMANDS.md for the full config reference.
30 MCP tools
The assistant uses these once the graph is built.
| Tool | Description |
|---|---|
build_or_update_graph_tool |
Build or incrementally update the graph |
run_postprocess_tool |
Re-run flow detection, community detection and FTS indexing |
get_minimal_context_tool |
Compact context (~100 tokens); call this first |
get_impact_radius_tool |
Blast radius of changed files |
get_review_context_tool |
Review context with structural summary |
query_graph_tool |
Callers, callees, tests, imports, inheritance queries |
traverse_graph_tool |
BFS/DFS traversal from any node with a token budget |
semantic_search_nodes_tool |
Search code entities by name or meaning |
embed_graph_tool |
Compute vector embeddings for semantic search |
list_graph_stats_tool |
Graph size and health |
get_docs_section_tool |
Retrieve documentation sections |
find_large_functions_tool |
Functions, classes or files above a line-count threshold |
list_flows_tool |
Execution flows sorted by criticality |
get_flow_tool |
One execution flow |
get_affected_flows_tool |
Flows affected by changed files |
list_communities_tool |
Detected code communities |
get_community_tool |
One community |
get_architecture_overview_tool |
…
Releases