
Skill · #290 trending skills repo
Data Master
MAGA2010/data-master
Auditable data analysis from raw files to reproducible PDF reports. Codex skill and cross-platform CLI.
- Stars
- 104
- This week
- —
- Forks
- 1
- Open issues
- 0
- Skills inside
- 11
Get started
Install the skills
npx skills add MAGA2010/data-masterInstalls into Claude Code, Codex, Cursor, OpenCode and the other agents it finds on your machine.
git clone --depth 1 https://github.com/MAGA2010/data-master.git /tmp/data-master
cp -r /tmp/data-master ~/.claude/skills/data-masterClaude Code reads ~/.claude/skills/ (or .claude/skills/ in a project). Other agents read the same SKILL.md format from their own skills folder.
Inside this repo
11 skills
/data-cleanerTurn profile.json into a deterministic cleaning plan, execute only the planned operations, and prove byte-for-byte reproducibility. Additive-only.skills/data-cleanerdata-explorerDescriptive analysis and EDA on cleaned data: distributions, missingness mechanism screen, correlations, categorical structure. No p-values for group comparisons.skills/data-explorerdata-profilerProfile a dataset without changing it: shape, dtypes, missingness, duplicates, distributions, anomalies, candidate group/target/time columns. Emits profile.json.skills/data-profilerdata-routerClassify any input path into one of eight modalities and emit a route manifest. First stage of data-master; no statistics, no cleaning.skills/data-routerdata-transformerDerive analysis variables from cleaned data under an explicit, reversible transformation ledger. No silent recoding, no leakage.skills/data-transformerdata-validatorRun the 8 Nature statistical gates and the journal checklist against the finished artifacts. Writes audit/final_audit.md and refuses the label submission-ready on a mandatory FAIL.skills/data-validatordeep-analyzerOptional modelling stage: regression, mixed effects, clustering, dimensionality reduction, forecasting. Only runs when the design supports it; every model carries diagnostics.skills/deep-analyzerreport-generatorAssemble report.md, executive_summary.md and report.pdf from the artifacts. Every number is registered against its source; the PDF is the primary deliverable and the Markdown is the citable source.skills/report-generatorstatistical-analyzerChoose and run the inferential test from the data structure, with effect sizes, CIs, multiplicity correction and explicit rejected alternatives. Refuses to report a p-value it cannot estimate.skills/statistical-analyzervisualizerDecide and render one figure per argument: chart type chosen against alternatives, title states the finding, caption defines the encoding, body gives fact -> interpretation -> implication.skills/visualizerDocumentation
README
data-master
Turn a messy dataset into an auditable PDF report from one command.




中文 · Examples · Evaluation · Roadmap · Launch kit
data-master preserves the raw input, makes every cleaning decision explicit,
runs statistics only at the level the data supports, tests sensitivity, and
delivers Markdown, PDF and machine-readable evidence. It is a Codex skill and a
standalone cross-platform CLI.
Try it
Requires Node.js 20+ and Python 3.11+.
npm install -g github:MAGA2010/data-master#v0.3.0
data-master setup
data-master skill install
data-master demo --out outputs/first-demo
For an additional format parser, install it only into the managed environment:
data-master setup --extra h5py
Optional format parsers are never installed automatically. This option accepts a package name only; use a parser named in its official format documentation.
Open outputs/first-demo/report.pdf, then inspect the verdict in
outputs/first-demo/audit/final_audit.md.
If the verified demo is useful, star the repository so other researchers and analysts can find it.
The npm package has no install hooks and no JavaScript dependencies. setup is
the only command that downloads Python dependencies; it creates an isolated
environment. skill install atomically installs the bundled skill and refuses
to overwrite an existing copy.
Why use it
| A plausible analysis can fail when… | data-master records or prevents it by… |
|---|---|
02134 silently becomes 2134 |
Reading delimited cells as text until an explicit conversion is approved |
| Repeated rows inflate the sample size | Declaring the independent unit and moving the primary analysis to that level |
| Cleaning alters an unrelated column | Comparing untouched columns with the raw input in text space |
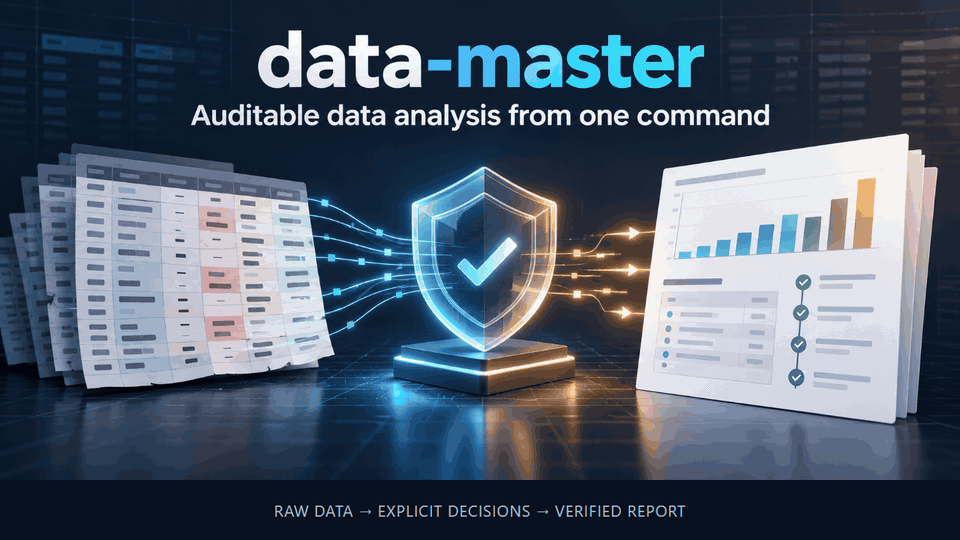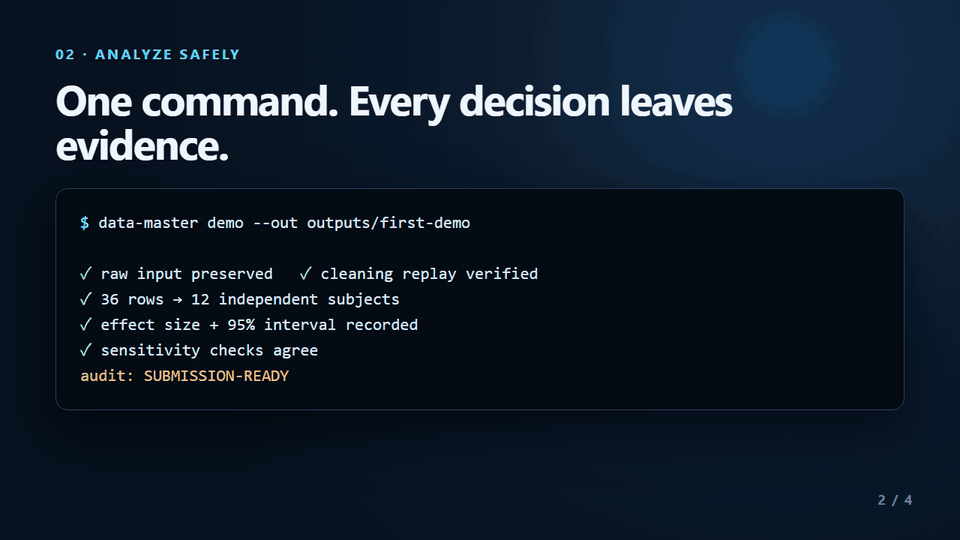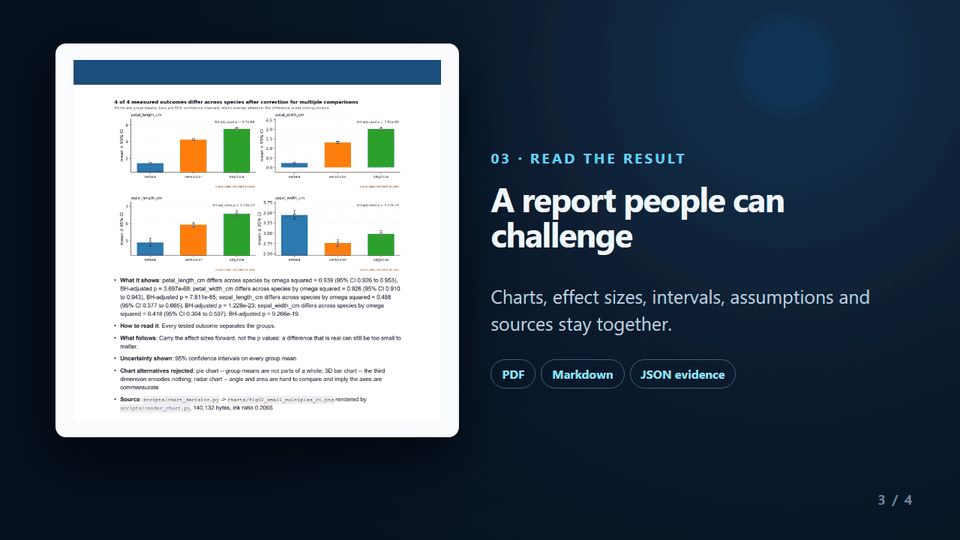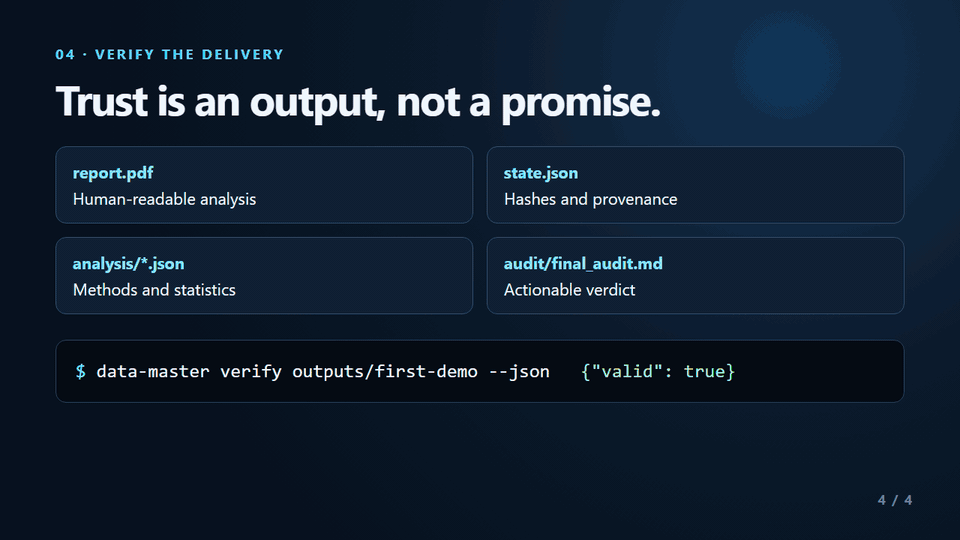
| A p-value appears without context | Saving the test, n, df, effect size, interval and correction family |
| “Robust” means one convenient re-fit | Running saved leave-one-group-out, jackknife, fence and complete-case perturbations |
| A polished report hides an unresolved decision | Producing the report and a separate audit that can still refuse submission |
| A resumed run reuses changed evidence | Hashing stage artifacts, code, references, dependencies and run options |
The audit enforces reporting discipline. It does not replace statistical judgment, collection context, peer review or a study protocol.
What you receive
outputs/
|-- report.pdf                     primary human-readable report
|-- report.md                      citable report source
|-- report.html                    self-contained shareable export of report.md
|-- executive_summary.md
|-- state.json                     stage ledger and provenance
|-- answers.template.json          decisions that require a human
|-- analysis/
|   |-- profile.json
|   |-- descriptive.json
|   |-- inferential.json
|   `-- sensitivity.json
|-- cleaned/
|   |-- cleaned.csv
|   |-- clean_<dataset>.py         replayable cleaning program
|   `-- validation.json
|-- charts/
`-- audit/
    |-- final_audit.md
    `-- final_audit.json
Verify a delivered run without modifying it:
data-master verify outputs/first-demo --json
Analyze your data
data-master analyze measurements.csv \
  --out outputs/study \
  --group treatment \
  --unit-key participant_id \
  --outcomes response_time,accuracy
Resume interrupted work:
data-master resume outputs/study/state.json
If a conversion or study decision is unsafe to infer, the run writes
answers.template.json. Fill its stable decision IDs and resume with:
data-master resume outputs/study/state.json --answers outputs/study/answers.json
Comparisons are labelled exploratory unless the run explicitly declares
--unit-key, --group, and --outcomes. The report and answers.template.json
show which declarations are missing. Supply all three to treat the comparison as
confirmatory.
Use data-master analyze --help for all pipeline options, including declared
covariates, journal/checklist routing, input-size limits, lockfile export and PDF
backend selection.
Unknown binary formats are profiled locally. File bytes, headers, metadata and records
are never sent to web search. Pickle-based files (.pkl, .pickle, .joblib, .dill,
.pck, .pckl, .pt, .pth) are refused by default because loading them can execute
code.
Reproducible case studies
| Case | Failure being tested | Evidence |
|---|---|---|
| Identifier traps | Leading zeros, dates, currency and mixed values are silently retyped | Plan, replay and untouched-column validation |
| Date or number? | 20240115 is an integer and a date; the file does not say which |
coerce_numeric_or_date hold with evidence and an answers-file resolution |
| Synthetic survey | Survey labels, -999 missing codes and zero-padded ids are silently retyped or imputed | Three evidenced holds; labels and codes survive cleaning |
| Repeated rows | Technical or repeated observations are counted as independent samples | Unit-level primary analysis and labelled row-level secondary |
| Audit refusal | A complete-looking report is treated as submission-ready without a defined unit | Report delivered; audit gate remains failed |
Every case links its raw synthetic input, command and inspectable artifacts.
Supported inputs
| Input | Current behavior |
|---|---|
CSV, TSV, Excel, JSON, JSONL, Parquet, single-table SQLite (.sqlite, .sqlite3, .db) |
Full profile, cleaning, unit-aware analysis, sensitivity, charts, report and audit |
| Timestamped tabular data | Audited descriptive trend, slope interval, autocorrelation, decomposition and changepoint screen |
| Text, image, audio or geospatial data | Explicitly labelled integrity profile and profile-only report |
| Mixed folders | Per-modality profiles and a combined profile-only report |
Full inferential analysis currently applies to one tabular file. Time-series mode is descriptive and does not forecast. Unsupported methods remain marked as unsupported instead of being replaced with a weaker claim.
Other installation paths
Install the Python package from a clone:
git clone https://github.com/MAGA2010/data-master.git
cd data-master
python -m venv .venv
# Windows: .venv\Scripts\python.exe -m pip install .
# macOS/Linux: .venv/bin/python -m pip install .
# Windows: .venv\Scripts\data-master.exe doctor
# macOS/Linux: .venv/bin/data-master doctor
# Windows: .venv\Scripts\data-master.exe skill install
# macOS/Linux: .venv/bin/data-master skill install
The Python package path uses the activated project virtual environment. The
data-master setup --extra <package> helper is provided by the npm launcher; when it
is unavailable, an unknown-format branch stays profile-only instead of installing a
parser into another interpreter.
Run directly from a checkout:
python scripts/run_pipeline.py \
  --in examples/iris/iris_dirty.csv \
  --out outputs/iris-demo \
  --title "Iris morphometrics" \
  --journal nature
Use a release tag or commit SHA in GitHub npm specifications when reproducible installation matters. The project is not currently published to the npm or PyPI registries.
Evidence and methodology
- Evaluation dashboard
- Validation and release checks
- Architecture and design decisions
- Workflow contract
- Cleaning rules
- Statistical reporting gates
- Journal and EQUATOR routing
- Current roadmap
CI exercises Windows and Linux with Python 3.11, 3.12 and 3.13, and runs the distribution suite on Windows, Linux and macOS with Python 3.13. Numerical tests compare key methods with independent equations or reference implementations. Distribution tests build and install the actual wheel and npm tarball outside the checkout before running the demo and verifying its evidence. The skill has also been installed and driven end to end in ZCode 3.14.4 on Windows (see Evaluation).
Scope boundaries
- Missingness mechanisms remain undetermined without collection context.
- Covariates are declared by the user; the pipeline does not select them from outcomes.
- Failed mixed models remain unresolved rather than falling back to an invalid independent-row test.
- Forecasting, causal identification and arbitrary row deletion are outside the current contract.
- Artifact verification detects changes against the saved ledger; it cannot establish authenticity if both artifacts and ledger are rewritten.
See the open roadmap for planned compatibility and evaluation work.
Contributing
External datasets, failure reports and small focused pull requests are welcome. Start with CONTRIBUTING.md and the contribution-sized roadmap tasks.
A statistical decision change needs a regression or numerical-reference test that would have failed before the change. Remove personal and confidential data before opening an issue.
Citation and license
Citation metadata is available in CITATION.cff. Every run records the package version or repository commit that produced it.
Released under the MIT License.
Releases