
SDK / infra · #243 trending MCP repo
Knowledge Rag
lyonzin/knowledge-rag
Local RAG server for Claude Code, Cursor and other MCP clients: hybrid BM25 + vector search with cross-encoder reranking on by default, 13 MCP tools, 33 file types including code, re-indexing on file changes. One Python process with embedded ChromaDB and FastEmbed ONNX: no Docker, database server or API key; offline after the first model download.
- Stars
- 302
- This week
- —
- Forks
- 50
- Open issues
- 1
- Skills inside
- 10
Inside this repo
10 skills
skills/domain/rag-security-firstrag-check-firstBefore answering any technical question, code request, architecture decision, or factual claim, call search_knowledge to check the local corpus. Trigger on any query that could be answered with prior work, indexed docs, ADRs, runbooks, or team context. Prevents hallucination and forces reliance on tskills/foundation/rag-check-firstrag-cite-sourcesEvery technical claim drawn from the local corpus must ship with a source citation — the file path from the result's source field, plus a section, or a line once it was checked in get_document. Trigger whenever the response quotes, paraphrases, or acts on knowledge that came from a search_knowledge skills/foundation/rag-cite-sourcesrag-onboard-contextAt the start of every new session or when the topic shifts significantly, probe the knowledge base to learn what is indexed. Calls get_index_stats (counts, categories, model) plus a couple of exploratory search_knowledge queries. Prevents the agent from operating blind or making wrong assumptions abskills/foundation/rag-onboard-contextrag-evaluate-qualityMeasure retrieval quality using evaluate_retrieval (MRR@5 and Recall@5) and get_index_stats. Use after ingestion, a model or configuration change, or a reported search regression. Compare representative questions against a recorded baseline.skills/maintenance/rag-evaluate-qualityrag-index-decisionsAfter making a non-obvious architectural decision, solving a novel bug, agreeing on a coding standard, or reaching a conclusion worth remembering, index it back into the knowledge base so the next occurrence is one search away. Uses add_document or add_from_url. Closes the feedback loop that makes askills/maintenance/rag-index-decisionsrag-code-reviewWhen performing code review on a PR, diff, snippet, or "look at this change" request, first consult the corpus for related ADRs, coding standards, prior patterns, and similar files. Grounds review comments in the team's actual decisions instead of generic best practices. Trigger on any review-style skills/workflow/rag-code-reviewrag-deep-diveThree-step multi-tool workflow — search the corpus, fetch the most relevant document in full, then find similar documents. Use when a single search_knowledge hit is not enough because the user asked a "how does X work end to end" or "explain the pattern" or "give me the full picture" question. Preveskills/workflow/rag-deep-diverag-troubleshootWhen the user reports a bug, error message, stack trace, unexpected behavior, or "why is this broken" question, search the corpus first for prior occurrences, known fixes, or related runbooks. Prevents re-solving problems the team already solved. Trigger on any error signature, exception name, stackskills/workflow/rag-troubleshootrag-web-fallbackOnly reach for external web search when the local corpus comes back empty or clearly insufficient. Forces the agent to try knowledge-rag first, then explicitly document why it needed to escalate. Prevents wasted API cost, latency, and (in air-gapped deployments) accidental network calls.skills/workflow/rag-web-fallbackDocumentation
README
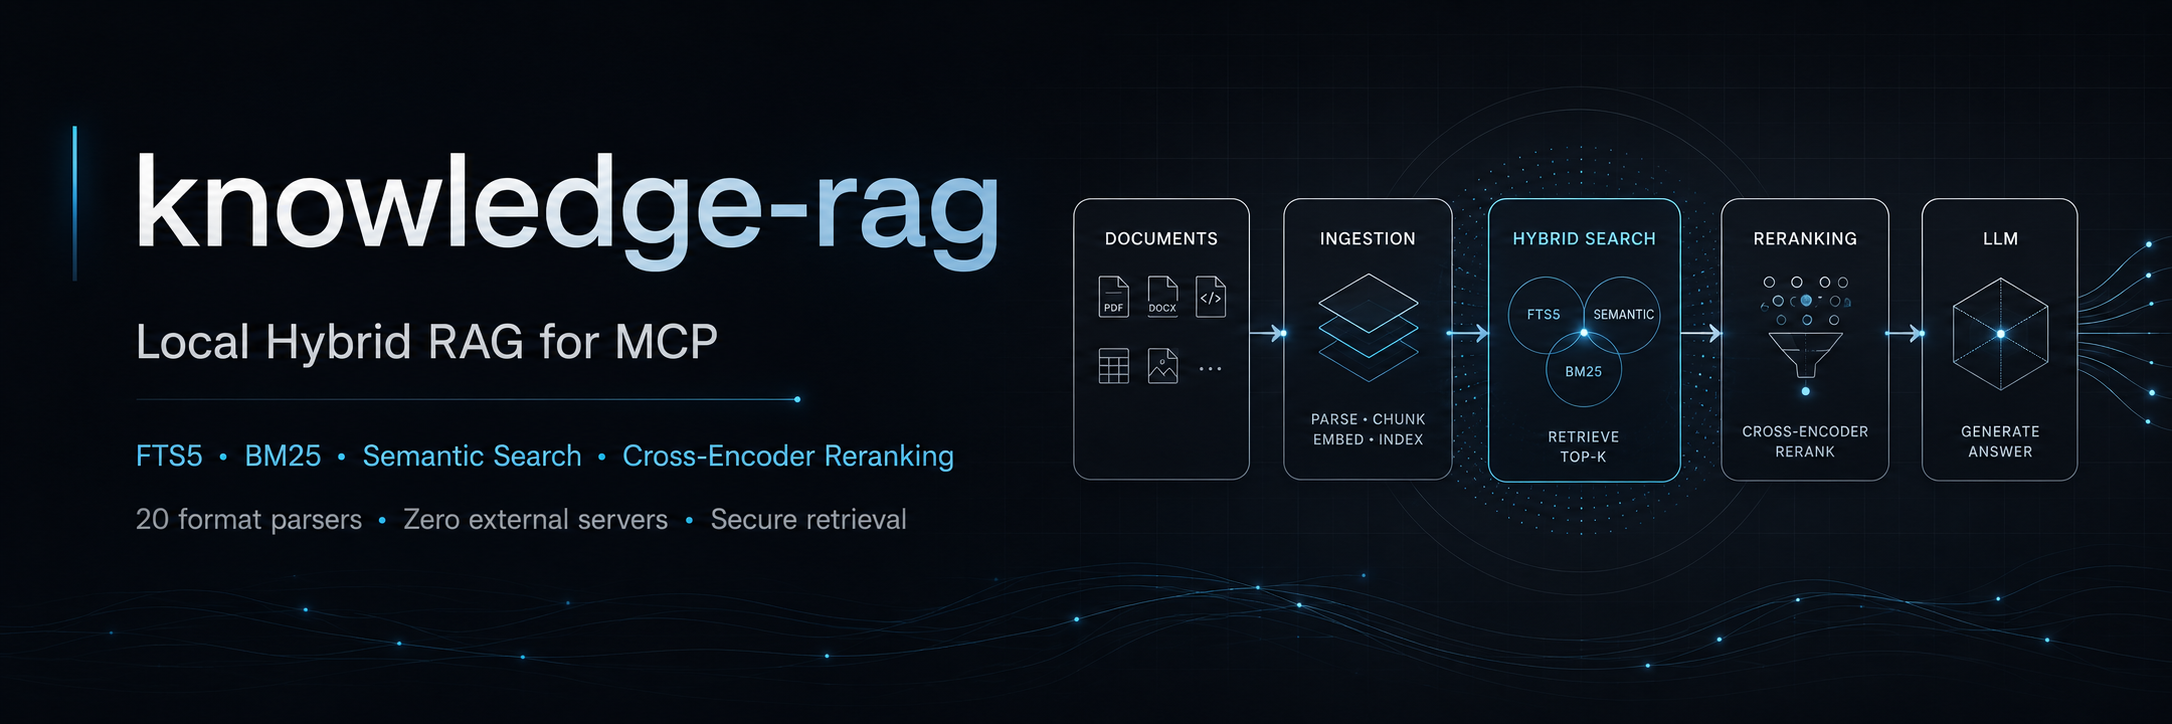
knowledge-rag: local RAG server for Claude Code, Cursor and other MCP clients
knowledge-rag is a local retrieval-augmented generation (RAG) server for the Model Context Protocol (MCP). It indexes the documents and code on your machine and gives Claude Code, Cursor, VS Code and other MCP clients 13 tools to search them, using hybrid search (BM25 keywords plus vector similarity) with cross-encoder reranking on by default. Everything runs in one Python process with embedded ChromaDB and FastEmbed ONNX models: no Docker, no database server, no API key. Indexing and search work offline once the models are cached.


- 11.1 ms median uncached hybrid query on CPU, 6.1 ms on CUDA: 36 queries over 149 chunks on one Windows host, reranker off (audit)
- 0.03 ms median for a repeated query served from the cache, same workload (audit)
- 75,016 chunks from 5,889 documents: full rebuild completed in a production reproduction (v4.8.3)
- 1,500+ tests collected on each of 9 OS × Python CI cells (platform-specific ones skip), 84% line coverage against an 80% floor (CI run, 2026-11-06)
Install and register with Claude Code (needs Python 3.11+ and Node.js 16+):
npx -y knowledge-rag --install-only
claude mcp add knowledge-rag -s user --env KNOWLEDGE_RAG_DIR=~/knowledge-rag -- npx -y knowledge-rag
Put files in ~/knowledge-rag/documents/ and ask your agent to search them. The folder is created on first start, new and changed files are indexed automatically, and the models (about 150 MB) download the first time they are needed.
Install · Results · How it works · Tools · Skills · Comparison · FAQ · Docs
Star history

Updated daily by the star-history workflow.
Measured results
Measurements from the project's own audits. They come from one host and small corpora, so treat them as orders of magnitude for your planning, not as guarantees.
| Measurement | CPU | NVIDIA CUDA |
|---|---|---|
| Hybrid query, uncached, median | 11.13 ms | 6.10 ms |
| Hybrid query, uncached, p95 | 13.91 ms | 7.44 ms |
| Repeated query (cache hit), median | 0.033 ms | 0.028 ms |
| Initial indexing, including first model load | 13.655 s | 0.832 s |
| Sampled peak process memory (RSS) | 1,416 MB | 990 MB |
Workload: scripts/audit_retrieval.py indexing 7 public repository documents (149 chunks) into a temporary ChromaDB and FTS5 index; 36 uncached queries; cross-encoder disabled to isolate retrieval; Windows 11, RTX 3080 Ti, Python 3.12.7, FastEmbed 0.8.1, ChromaDB 1.5.9, model BAAI/bge-small-en-v1.5, Hugging Face offline mode. Source: audit 2026-10-03.
| Retrieval check | Result | Workload and source |
|---|---|---|
| Expected source in the top 5 | 12 of 12 questions; MRR@5 0.875 (English), 0.792 (Portuguese) | 6 English and 6 Portuguese questions over the same 149 chunks, default English model; a small smoke test, not a general quality claim (audit) |
| Cross-encoder rerank of 8 candidates | 141.9 ms first call including model load, 19.7 ms next call (CPU) | One English and one Portuguese query, network blocked (audit) |
| Large corpus | Full rebuild completed and filled 75,016 FTS5 rows on the first attempt | 5,889 documents / 75,016 chunks, v4.8.3 reproduction (CHANGELOG) |
More measurements: memory, model comparison, historical baseline
- BM25 memory: retained Python memory fell from 120.7 MB to 26.9 MB (−77.75%) for 10,000 documents / 1.99 million tokens after the token pool was added in v4.10.0 (audit).
- Metrics memory: 100,001 metric observations retained 328 bytes instead of 3,201,024 (audit).
- Multilingual model: on a 60-question diagnostic set over a private ~70,000-chunk corpus,
intfloat/multilingual-e5-largefound the expected source for 36 questions against 37 for the defaultBAAI/bge-small-en-v1.5; re-embedding 70,083 chunks on CUDA took 1,186.58 s (audit 2026-10-04). - Historical baseline: v4.7.1 microbenchmarks and a 100-document rebuild on CPU (perf-baseline-v4.7.1). The ratios apply to those workloads only.
- Live dashboard: the benchmark dashboard tracks CI microbenchmarks. They use mocked storage and models, so they answer a different question than the real-model numbers above.
How it works
- Ingest. Files under
documents/are parsed by format: code files get their function, class and import names as metadata, notebooks keep only Markdown and code cells, PDFs contribute their text. Markdown is split at##/###sections; every other format is cut into 1,000-character chunks with 200 characters of overlap. Chunks are de-duplicated by SHA-256, embedded with FastEmbed (defaultBAAI/bge-small-en-v1.5, 384 dimensions) and stored in an embedded ChromaDB. - Watch. While the server runs, a watcher re-indexes changed files after 10 seconds without new changes. Full rebuilds fill a staging collection and swap it in after validation, so searches keep using the current index.
- Search.
search_knowledgechecks a query cache (100 entries, 5-minute TTL), runs BM25 over an inverted index and vector search, fuses both rankings with weighted reciprocal rank fusion (hybrid_alpha, default 0.3, leaning towards keywords) and reranks the top candidates with theXenova/ms-marco-MiniLM-L-6-v2cross-encoder. With the opt-in FTS5 fast path, identifier-like queries such as CVE IDs, ticket keys and hashes go to SQLite FTS5 first. - Answer. Results go back to the MCP client with the file path, chunk index, snippet and scores. The client's model writes the answer; knowledge-rag never calls an LLM.
- Serve. Over stdio for one client, or as one Streamable HTTP or SSE server for many. HTTP mode answers health probes first, then checks the bearer token. Every tool call passes through the optional rate limiter and metrics.
config.yamland five presets configure all of it.
flowchart TB
    subgraph CLIENTS["MCP clients"]
        direction LR
        C1[Claude Code]
        C2[Claude Desktop]
        C3[Cursor]
        C4[Windsurf]
        C5[VS Code · other stdio or HTTP clients]
    end

    subgraph TRANSPORT["Transport"]
        T1[stdio<br/>1 process per client]
        T2[Streamable HTTP / SSE<br/>1 server for N clients]
    end

    subgraph MIDDLEWARE["ASGI middleware (HTTP transports)"]
        M1[HealthMiddleware<br/>/health · /healthz]
        M2[BearerAuthMiddleware<br/>constant-time compare]
    end

    subgraph MCP["13 MCP tools (contract checked in CI)"]
        W[Tool wrappers<br/>optional rate limit · metrics]
        MT1[search_knowledge]
        MT2[get_document · search_similar]
        MT3[add_document · add_from_url · update · remove]
        MT4[reindex_documents · get_reindex_status]
        MT5[list_documents · list_categories · get_index_stats · evaluate_retrieval]
    end

    subgraph SEARCH["Retrieval pipeline"]
        QC[Query cache<br/>LRU 100 · 5-min TTL]
        R[Query router<br/>regex, FTS5 fast path only]
        F[FTS5 fast path<br/>opt-in lexical retrieval]
        H[Hybrid search]
        BM[BM25<br/>inverted index]
        SE[Vector search<br/>FastEmbed ONNX, lazy-loaded]
        RRF[Weighted reciprocal rank fusion]
        CE[Cross-encoder rerank<br/>MiniLM-L-6-v2]
    end

    subgraph STORAGE["Local storage (data_dir)"]
        CH[ChromaDB<br/>vectors + metadata<br/>WAL with HTTP transports]
        FT[SQLite FTS5<br/>lexical index<br/>WAL + busy timeout]
        MD[index_metadata.json<br/>durable state]
    end

    subgraph INGEST["Document ingestion"]
        FS[documents/ folder]
        WD[Watcher<br/>10 s debounce]
        PA[Format parsers<br/>MD · PDF · DOCX · code · IaC · IPYNB]
        CK[Chunker<br/>Markdown sections · 1,000-char windows]
        EM[FastEmbed ONNX<br/>default bge-small-en-v1.5, 384-d]
        DD[SHA-256 dedup]
        SW[Staging rebuild<br/>rollback on handled publication failure]
    end

    subgraph OBS["Observability (opt-in)"]
        PM[Prometheus /metrics<br/>separate port, HTTP transports]
        LG[Structured JSON logs]
        HC[Health payload<br/>version · uptime · cache stats]
    end

    subgraph CFG["Configuration"]
        YM[config.yaml<br/>+ 5 presets]
    end

    CLIENTS -->|MCP over stdio| T1
    CLIENTS -.->|MCP over HTTP| T2
    T1 --> W
    T2 --> M1 --> M2 --> W
    W --> MT1 & MT2 & MT3 & MT4 & MT5

    MT1 --> QC
    QC -->|cache miss| R
    R -->|identifier-like| F
    R -->|everything else| H
    H --> BM
    H --> SE
    F --> FT
    BM --> CH
    SE --> CH
    BM --> RRF
    SE --> RRF
    RRF --> CE
    CE --> QC

    MT2 --> CH
    MT3 --> INGEST
    MT4 --> SW
    MT5 --> CH

    FS --> WD --> PA
    PA --> CK --> DD --> EM --> CH
    SW -.->|validated swap| CH
    SW -.-> FT
    CH -.-> MD

    W -.->|instrumented| PM
    W -.->|logs| LG
    M1 --> HC

    YM -.-> SEARCH
    YM -.-> STORAGE
    YM -.-> OBS
    YM -.-> MIDDLEWARE

    classDef client fill:#3776AB,stroke:#1e5a8a,color:#fff
    classDef transport fill:#00A67E,stroke:#006e54,color:#fff
    classDef middleware fill:#6b46c1,stroke:#4c1d95,color:#fff
    classDef storage fill:#4b5563,stroke:#1f2937,color:#fff
    classDef obs fill:#dc2626,stroke:#7f1d1d,color:#fff
    classDef ingest fill:#b45309,stroke:#78350f,color:#fff

    class C1,C2,C3,C4,C5 client
    class T1,T2 transport
    class M1,M2 middleware
    class CH,FT,MD storage
    class PM,LG,HC obs
    class FS,WD,PA,CK,EM,DD,SW ingest
Component ownership, memory and concurrency boundaries and the hybrid_alpha weights: docs/ARCHITECTURE.md.
Install
Every path below runs the same server. Each claude mcp add sets KNOWLEDGE_RAG_DIR, the folder that holds config.yaml, documents/, data/ and models_cache/. Without it, the server picks a folder from its install location and the working directory the client starts it in, which can be a project you did not intend (config.py).
Claude Code with the npx launcher
npx -y knowledge-rag --install-only
claude mcp add knowledge-rag -s user --env KNOWLEDGE_RAG_DIR=~/knowledge-rag -- npx -y knowledge-rag
The npm package is a launcher. It finds Python 3.11+ (python3/python, or python/py -3 on Windows), creates a virtual environment in ~/.knowledge-rag/venv, installs the matching knowledge-rag version from PyPI and starts the server over stdio. --install-only does the installation once ahead of time, so the client's first start does not wait for pip. A new npm version reinstalls the package on the next start. If a client on native Windows fails to start npx, register cmd /c npx -y knowledge-rag instead.
pip in a virtual environment
python3 -m venv ~/knowledge-rag/venv
~/knowledge-rag/venv/bin/python -m pip install knowledge-rag
claude mcp add knowledge-rag -s user --env KNOWLEDGE_RAG_DIR=~/knowledge-rag \
  -- ~/knowledge-rag/venv/bin/python -m mcp_server.server
On Windows (PowerShell), use python and $HOME\knowledge-rag\venv\Scripts\python.exe in place of python3 and ~/knowledge-rag/venv/bin/python.
Optional: knowledge-rag init, run inside ~/knowledge-rag with the virtual environment active, copies config.example.yaml and the five presets and creates documents/. It does not create config.yaml or register the server: copy the template or a preset to config.yaml yourself. Without a config.yaml, the defaults apply, including all 33 default file types.
Docker
The image is published for linux/amd64 and linux/arm64. For stdio, the client starts one container per session:
claude mcp add knowledge-rag -s user -- docker run -i --rm \
  -v ~/knowledge-rag/documents:/app/documents \
  -v ~/knowledge-rag/data:/app/data \
  -v knowledge-rag-models:/app/models_cache \
  ghcr.io/lyonzin/knowledge-rag:latest
The image runs python -m mcp_server.server, which reads /app/config.yaml and defaults to stdio on 127.0.0.1. To serve HTTP from a container, mount a config that listens on all container interfaces and pass --transport:
mkdir -p ~/knowledge-rag
cat > ~/knowledge-rag/config.yaml <<'EOF'
server:
  host: "0.0.0.0"
  auth:
    bearer_token: "replace-with-a-long-random-token"
EOF
docker run -d --name knowledge-rag -p 127.0.0.1:8179:8179 \
  -v ~/knowledge-rag/config.yaml:/app/config.yaml:ro \
  -v ~/knowledge-rag/documents:/app/documents \
  -v ~/knowledge-rag/data:/app/data \
  -v knowledge-rag-models:/app/models_cache \
  ghcr.io/lyonzin/knowledge-rag:latest --transport streamable-http
curl http://127.0.0.1:8179/health
claude mcp add --transport http knowledge-rag http://127.0.0.1:8179/mcp \
  # if server.auth.bearer_token is set, add the token as a Bearer auth header
The image builds its model copies into FastEmbed's default cache, but the server reads /app/models_cache, so the models download again the first time they are needed. The knowledge-rag-models volume keeps them across containers.
Shared HTTP server for several clients
stdio fits one client that owns one process. For several clients on one index (Claude Code, Cursor, LM Studio, more terminals), run one Streamable HTTP server and point every client at it (#217, #223):
# ~/knowledge-rag/config.yaml
server:
  transport: "streamable-http"      # "sse" for clients that only speak SSE
  host: "127.0.0.1"
  port: 8179
  auth:
    bearer_token: "replace-with-a-long-random-token"
  rate_limit:
    enabled: true
    requests_per_minute: 60
    burst: 10
  metrics:
    enabled: true
    port: 9179                      # binds 0.0.0.0 with no auth: firewall it
  logging:
    format: "json"
KNOWLEDGE_RAG_DIR=~/knowledge-rag knowledge-rag     # run from the venv where you installed it
curl http://127.0.0.1:8179/health                  # {"status":"ok","version":"5.0.0",...}
claude mcp add --transport http knowledge-rag http://127.0.0.1:8179/mcp \
  # if server.auth.bearer_token is set, add the token as a Bearer auth header
| Transport | Clients per server process | Who runs the process | Use it for |
|---|---|---|---|
stdio (default) |
1 | The MCP client, per session | One client; models load in each process on first use |
streamable-http |
Many | You, one background server | Several clients sharing one index and one model load (preferred) |
sse |
Many | You, one background server | HTTP clients that only support SSE |
HTTP transports switch on the single-instance lock (KNOWLEDGE_RAG_SINGLE_INSTANCE=1), so a second server cannot open the same data directory. The default host is 127.0.0.1. If you bind to 0.0.0.0 or serve a network, set server.auth.bearer_token and put TLS in front with a reverse proxy such as Caddy or Nginx; without a token, the server prints a warning that the endpoint is unauthenticated.
Claude custom connectors (remote MCP)
- Network requirement: custom connector requests come from Anthropic's cloud on web, desktop and mobile, so they cannot reach
127.0.0.1. Expose the server through a secure public HTTPS endpoint (for example Cloudflare Tunnel, ngrok or a reverse proxy) athttps://your-public-domain/mcp. Configure the proxy to send an upstreamHostthat the HTTP app accepts forserver.host(with the default loopback configuration,127.0.0.1:8179); forwarding the public hostname unchanged can produce421 Invalid Host header. Keep bearer authentication and HTTPS on. A localclaude_desktop_config.jsonusescommand/argsfor local stdio processes and does not support remote HTTP endpoints. - Setup and auth: in Claude (Pro/Max: Customize > Connectors > + Add > Add custom connector; Team/Enterprise owners: Organization settings > Connectors), enter the public endpoint. Under Request headers, set
AuthorizationtoBearer <your-token>, matchingserver.auth.bearer_tokeninconfig.yaml. See Anthropic's custom connectors guide.
Other MCP clients
Any client that starts a stdio MCP server from a command, or connects to a Streamable HTTP endpoint, can use knowledge-rag. The installation guide has the exact JSON for each of these:
| Client | Where the server entry goes |
|---|---|
| Claude Desktop | claude_desktop_config.json, under mcpServers (Settings → Developer → Edit Config) |
| Cursor | ~/.cursor/mcp.json or .cursor/mcp.json, under mcpServers |
| Windsurf | ~/.codeium/windsurf/mcp_config.json, under mcpServers |
| Antigravity | ~/.gemini/antigravity/mcp_config.json, under mcpServers |
| VS Code (Copilot) | .vscode/mcp.json, under servers, with "type": "stdio" |
| opencode | opencode.json, under mcp, with command as an array |
{
  "mcpServers": {
    "knowledge-rag": {
      "command": "npx",
      "args": ["-y", "knowledge-rag"],
      "env": { "KNOWLEDGE_RAG_DIR": "~/knowledge-rag" }
    }
  }
}
[!WARNING] One writer per data directory. Over stdio, each MCP client starts and owns its own knowledge-rag process. Do not run a second writer against the same
data_dirwhile that client is open: on Windows, two writers corrupted the ChromaDB HNSW segment (#216). Add"KNOWLEDGE_RAG_SINGLE_INSTANCE": "1"to the client'senvblock as a safety net, or share one HTTP server. Running CLI commands safely: docs/single-instance.md.
[!WARNING] Keep
data_dirout of cloud-sync folders. OneDrive (includingOneDrive - <tenant>), iCloud Drive, Dropbox, Google Drive, Box, pCloud, MEGAsync, Nextcloud/ownCloud and Sync hold handles on the live index while they upload it. That races with ChromaDB's HNSW memory maps and SQLite WAL writes and can crash the process (0xC0000005on Windows,SIGBUSelsewhere); startup auto-repair then moves the index todata/backups/auto-repair-*and you reindex from scratch. Since v4.11.0, startup stops with exit code 78 (EX_CONFIG) whendata_dirresolves under one of these providers. Use a local path such as%LOCALAPPDATA%\knowledge-rag\dataon Windows or~/.local/share/knowledge-rag/dataon Linux and macOS, or setpaths.allow_cloud_sync: trueto accept the risk.
All install methods, GPU setup and troubleshooting for each client: docs/INSTALLATION.md.
The 13 MCP tools
| Tool | What it does |
|---|---|
search_knowledge |
Hybrid BM25 + vector search with cross-encoder reranking; filters by category, folders (include_folders, exclude_folders) and min_score |
get_document |
Returns the full content of one indexed file |
search_similar |
Finds documents similar to an indexed file |
evaluate_retrieval |
Reports MRR@5 and Recall@5 for your own query → expected file pairs |
list_documents |
Lists indexed documents, 100 per page by default (up to 200 with limit), paged with offset |
list_categories |
Lists categories, derived from folder paths, with document counts |
get_index_stats |
Document and chunk counts, embedding model, BM25 status, cache hit rate, watcher status, HNSW self-recall probe |
add_document |
Saves text as a file under documents/ and indexes it |
update_document |
Replaces a document's content and re-indexes it |
remove_document |
Removes a document's chunks from the index, and optionally the file |
add_from_url |
Fetches an http(s) page, strips the HTML, saves it as Markdown with a provenance marker and indexes it |
reindex_documents |
Incremental by default; force re-embeds every file, full_rebuild builds and swaps a staging collection; runs in the background |
get_reindex_status |
Reports the progress of a background reindex |
Each result carries source (the file path), chunk_index and, in snippet mode, match_offset (a character offset into the content), so citations point to a file and chunk, not a line number. score is normalized per query, so the top result is always 1.0 and min_score filters relative to the other results; compare reranker_score, the raw cross-encoder score, across queries. Parameters, return shapes and examples: docs/API.md.
Agent skills
The 13 tools tell an agent what it can do; they do not tell it when to search. The skills/ folder adds ten MIT-licensed skills for Claude Code that make the agent check your index first, cite what it used and keep the index current. Other agents can use the same instructions as rules or system prompts (skills/README.md).
| Skill | Kind | What it changes |
|---|---|---|
rag-check-first |
Foundation | Searches the corpus before answering technical questions |
rag-cite-sources |
Foundation | Cites the source file and chunk for every claim taken from the corpus |
rag-onboard-context |
Foundation | Probes what is indexed at the start of a session |
rag-deep-dive |
Workflow | Search, read the best document in full, then find similar ones |
rag-web-fallback |
Workflow | Goes to the web only when the local corpus comes back empty or insufficient |
rag-troubleshoot |
Workflow | Looks up prior fixes and runbooks before debugging an error |
rag-code-review |
Workflow | Checks ADRs, standards and similar files before commenting on a change |
rag-index-decisions |
Maintenance | Indexes decisions and fixes back into the corpus |
rag-evaluate-quality |
Maintenance | Measures MRR@5 and Recall@5 after ingestion or configuration changes |
rag-security-first |
Domain | Consults MITRE ATT&CK, CVE and runbook notes first on security tasks |
Each skill installs as ~/.claude/skills/<skill-name>/SKILL.md (or .claude/skills/<skill-name>/SKILL.md for one project):
# Node.js 22.20+: choose the skills and agents interactively; -g installs for all projects
npx skills add lyonzin/knowledge-rag -g

# Without Node (Linux, macOS, WSL, Git Bash): all ten skills into ~/.claude/skills
curl -fsSL https://raw.githubusercontent.com/lyonzin/knowledge-rag/master/skills/install.sh | bash
install.sh also takes --project, --target <path>, --only rag-check-first,rag-cite-sources, --dry-run, --list and --help. Restart Claude Code after installing. Skill chains and per-client setup: skills/CATALOG.md, skills/README.md.
How knowledge-rag compares to other RAG projects
As of 2026-11-06. 🗸 default: built in and on by default. 🗸 opt-in: built in, off until you enable it. 🗸: available, default state not compared. component: a library piece you assemble yourself. ✗: not built in, meaning absent from the code, needing an external provider (local embeddings column), or not found in code or docs; ✗ manual: you start it yourself. Words in parentheses name the mechanism.
| Project (stars, license) | MCP server | MCP client | Hybrid | Rerank | Auto re-index | Local emb. |
|---|---|---|---|---|---|---|
| knowledge-rag (301, MIT) | 🗸 13 tools | ✗ | 🗸 default (+FTS5 opt-in) | 🗸 default | 🗸 default | 🗸 |
| Dify (160.5k, Dify license) | 🗸 | 🗸 | 🗸 | 🗸 opt-in | ✗ manual sync | ✗ |
| Open WebUI (157.9k, Open WebUI license) | ✗ | 🗸 | 🗸 opt-in | 🗸 opt-in | ✗ manual (add-on) | 🗸 |
| Langflow (156.4k, MIT) | 🗸 | 🗸 | component | component | component (Schedule Trigger) | component |
| LangChain (149.1k, MIT) | ✗ | 🗸 | component | component | component (indexing API) | component |
| RAGFlow (93.7k, Apache-2.0) | 🗸 | 🗸 | 🗸 default | 🗸 opt-in | 🗸 connectors | ✗ |
| AnythingLLM (68.0k, MIT) | ✗ | 🗸 | ✗ | 🗸 opt-in | 🗸 opt-in (beta, per file, hourly) | 🗸 |
| Serviette, ex pathwaycom/llm-app (58.7k, MIT) | ✗ | ✗ | 🗸 opt-in | 🗸 opt-in | 🗸 default | 🗸 |
| PrivateGPT (57.6k, Apache-2.0) | ✗ | 🗸 | 🗸 opt-in (Qdrant) | ✗ | 🗸 opt-in (CLI --watch) | ✗ |
| LlamaIndex (52.8k, MIT) | ✗ | 🗸 | component | component | component (refresh_ref_docs) | ✗ |
| LightRAG (40.6k, MIT) | ✗ | ✗ | ✗ | 🗸 opt-in (API) | ✗ manual scan | ✗ |
| Quivr 2 (39.6k, MIT) | 🗸 | ✗ | 🗸 | 🗸 opt-in (paid service) | 🗸 scheduled feeds | 🗸 |
| Khoj (38.0k, AGPL-3.0) | ✗ | 🗸 | ✗ | 🗸 opt-in | 🗸 via clients, every 10 min | 🗸 |
| GraphRAG (36.6k, MIT) | ✗ | ✗ | ✗ | ✗ | ✗ manual (graphrag update) | ✗ |
| Onyx (33.3k, MIT CE + EE) | 🗸 | 🗸 | 🗸 default | ✗ removed in 2026 | 🗸 connectors | 🗸 |
| FastGPT (30,000, FastGPT license) | 🗸 | 🗸 | 🗸 | 🗸 with a rerank model | 🗸 opt-in (daily sync) | ✗ |
| Project | Type | Needs for first answer | Formats |
|---|---|---|---|
| knowledge-rag | MCP server | pip + MCP client | 33 (+2 opt-in), code/IaC; no OCR |
| Dify | platform | Docker (Postgres, Redis, Weaviate…) + model | PDF, Office, CSV, MD, HTML, EML, EPUB |
| Open WebUI | chat app | pip/Docker + Ollama/API | PDF, Office, EPUB, CSV, HTML, MD |
| Langflow | builder | pip/Docker + provider key | TXT, MD, CSV, JSON, HTML, PDF, DOCX… |
| LangChain | library | code + provider | loaders |
| RAGFlow | engine + UI | Docker (Elasticsearch, MySQL, MinIO, Kvrocks, NATS), 16 GB + model | Office, PDF, scans, web |
| AnythingLLM | desktop/Docker app | installer (built-in LLM) | PDF, TXT, DOCX… |
| Serviette | RAG server | pip + Pathway licence key | text, Office, PDF, scans |
| PrivateGPT | API server | LLM + embedding servers | PDF, DOCX, PPT/X, EPUB, IPYNB, images, audio |
| LlamaIndex | library | code + OPENAI_API_KEY | ~20 incl. images, MP3/4 |
| LightRAG | graph lib + server | LLM + embedding providers | TXT, MD, PDF, DOCX |
| Quivr 2 | HTTP engine | Docker (Postgres, object store) | PDF plugin, RSS, mail |
| Khoj | app | Docker (pgvector, SearxNG…) + LLM | PDF, MD, Org, Word, Notion |
| GraphRAG | library/CLI | OpenAI/Azure key | TXT, CSV, JSON |
| Onyx | enterprise app | Docker (~12 containers: OpenSearch, Postgres, Redis…) + LLM | PDF, DOCX, PPTX, XLSX, EML, EPUB, HTML, TXT, MD, JSON, YAML, XML, CSV, SQL, PNG, JPG, WebP |
| FastGPT | platform | Docker (MongoDB, PgVector, AI Proxy) + LLM + embedding | TXT, MD, HTML, PDF, Office, CSV |
Notes: Serviette was renamed from pathwaycom/llm-app and inherited its stars. The LlamaIndex README says its focus moved to LlamaParse. Quivr was repurposed as a content-stream search engine. The GraphRAG README says it is in maintenance mode. PrivateGPT's changelog lists a SentenceTransformer reranker (#1810) that the current code no longer contains.
Where knowledge-rag differs. It is the only row with hybrid search and cross-encoder reranking both on by default, and the only MCP server in the table that answers without Docker, a database server or a model key. Auto re-index is on by default only in knowledge-rag and Serviette, and Serviette ships no MCP server; everywhere else it takes a connector, a client, a setting, assembly or a manual run. It is code-first: 23 of its 33 default file types are code or infrastructure files. The license is plain MIT.
Where others are stronger. Multi-user scale: Postgres, OpenSearch and Elasticsearch stacks against one writer on an embedded ChromaDB. Web UIs and visual builders: knowledge-rag has no UI and does not generate answers; the MCP client's LLM does. Connectors, OCR, images and audio, and graph RAG. Evidence and reach: knowledge-rag's published quality check is a 12-question smoke test (Recall@5 1.0) and it has 301 stars. This table compares features, not retrieval quality.
Checklist for your own evaluation
Feature checklists are not benchmarks. Before you choose, measure what your deployment needs on comparable hardware:
| Decision | What to verify |
|---|---|
| Local or remote processing | Where models run, which client receives content, which features need network access |
| Retrieval quality | Expected-source queries on your corpus, including its languages and identifiers |
| Performance | Cold start, indexing, uncached queries, memory peaks and concurrent use |
| Operations |
…
Releases
Recent versions
v5.0.1v5.0.1 — Skills installer, npx forwarding and the CUDA memory fixv5.0.0v5.0.0 — Paged list_documents, index safety and merge-blocking CI gatesv4.11.1v4.11.1 — Fresh-install startup fix and Windows-safe state writesv4.11.0v4.11.0 — Cloud-sync data_dir guardv4.10.0v4.10.0 - Indexing reliability, bounded memory and scoped retrievalv4.9.2v4.9.2 — Post-review hotfix: rollback atomicity + operating-model docs