
Server · #26 trending MCP repo
Open Science
aipoch/open-science
The open-source AI research workbench for scientific research and agent workflows. Local-first, model-agnostic desktop app with extensible skills, MCP tools and connectors, Python/R execution and traceable artifacts for reproducible research on macOS, Windows and Linux.
- Stars
- 5.5k
- This week
- —
- Forks
- 552
- Open issues
- 42
- Skills inside
- 27
Inside this repo
27 skills
packages/research-film/resources/authoringalphafold2Predict protein structure for monomers and multimers with AlphaFold2 via the ColabFold runner (Mirdita et al. 2022, github.com/sokrypton/ColabFold; AlphaFold2 Jumper et al. 2021). Reach for this skill to fold a sequence or complex with the AF2/AF2-Multimer evoformer, to validate designed sequences bresources/skills/alphafold2boltzStructure prediction for protein, nucleic-acid, and small-molecule complexes with Boltz-2 (Passaro & Wohlwend et al. 2025, github.com/jwohlwend/boltz). Reach for this skill to validate designed binders against a target, to co-fold a protein with a SMILES or CCD ligand, or to get an open-source Alpharesources/skills/boltzborzoiPredict genome-wide functional tracks (RNA-seq, CAGE, DNase, ChIP) from DNA sequence with Borzoi. Use this skill when: (1) Scoring the regulatory effect of a variant on expression/accessibility, (2) Generating predicted coverage tracks for a locus, (3) Prioritising non-coding variants by predicted tresources/skills/borzoichai1Structure prediction for protein, nucleic-acid, and small-molecule complexes with the Chai-1 foundation model (Chai Discovery 2024, github.com/chaidiscovery/chai-lab). Reach for this skill to predict an antibody-antigen or protein-ligand complex from a single FASTA, to re-fold designed binders as anresources/skills/chai1compute-env-setupPrepare reproducible setup instructions and validate a user-managed named software environment on an Open-Science SSH Compute Host, including direct SSH and Slurm hosts. Use when a remote job needs packages, modules, cache variables, or a repeatable activation that the host does not already provide.resources/skills/compute-env-setupcustomizeUse when the user wants to create or manage a Specialist agent or create, revise, publish, or delete a Skill through the conversational `/Customize` entry. Routes Skill work to the internal skill-creator and handles Specialist work through the JavaScript host.agents SDK.resources/skills/customizediffdockPredict small-molecule binding poses with DiffDock-L (Corso et al. 2023/2024, github.com/gcorso/DiffDock) — blind diffusion docking that places a ligand into a protein pocket without a predefined search box and ranks the samples with a learned confidence model. Reach for this skill to dock a SMILES resources/skills/diffdockdocx-generationUse when creating a Word DOCX report from Markdown, converting Markdown tables and lists to DOCX, or choosing a workflow for editing an existing DOCX while preserving its structure and styles. Use this workflow before running Markdown-to-DOCX shell commands. Includes report typography, table layout,resources/skills/docx-generationenv-managementUse when a notebook run fails on a missing package (ImportError, ModuleNotFoundError, "there is no package called"), when you need to inspect an installed package version, or when you need to install, add, or manage Python or R packages for the notebook runtime. Covers inspect_packages, routing Pythresources/skills/env-managementesmfold2Biohub ESMFold2 / ESMFold2-Fast all-atom co-folding (Candido et al. 2026, github.com/Biohub/esm). Single-sequence and MSA modes; protein, DNA, RNA, ligand (CCD/SMILES), modified residues. FoldBench Ab-Ag 50-55%, PPI 70-77% DockQ-pass. Also covers the ESMC-{300M,600M,6B} protein language models from resources/skills/esmfold2evo2Score, embed, and generate DNA sequences with Evo 2, a long-context genomic foundation model. Use this skill when: (1) Computing per-nucleotide or per-sequence likelihoods for variant effect scoring, (2) Embedding genomic windows for downstream classification, (3) Generating DNA conditioned on a preresources/skills/evo2fair-esm2Embed proteins with Meta AI's ESM-2 (`fair-esm` package). Use this skill when: (1) Extracting per-residue or per-sequence embeddings for downstream ML, (2) Masked-LM likelihood / mutation effect scoring, (3) Contact prediction from a sequence.resources/skills/fair-esm2figure-composerCompose one publication-grade multi-panel figure. Start from a one-line claim plus immutable data Artifact Version references, or inspect an existing figure and draft its outline directly. Plan a 12-column panel outline, delegate one worker per panel, compose and inspect the result, then run at mostresources/skills/figure-composerfigure-stylePublication-grade correctness and legibility rules for final-deliverable scientific figures, not exploratory plots. Use for a figure that will ship in a report, paper, export, or kept artifact. Covers data fidelity, label economy, color threading, chart choice, layout, and render-then-verify QA withresources/skills/figure-styleindication-dossierGenerate a therapeutic indication dossier. Covers the patient population, epidemiology, disease biology, standard of care, regulatory precedent, and landmark clinical trials.resources/skills/indication-dossierligandmpnnInverse-fold a backbone with ligand, nucleic-acid, and metal context using LigandMPNN (Dauparas et al. 2023, github.com/dauparas/LigandMPNN). Reach for this skill to redesign the residues lining a binding pocket around a bound small molecule or cofactor, to design metal-coordinating sites where the resources/skills/ligandmpnnliterature-reviewFind, verify, and synthesize scientific literature — from "what's the seminal paper for X" through full multi-source reviews. Covers grounding claims in real retrieved sources, avoiding fabricated citations, handling retractions, and calibrating confidence to evidence strength.resources/skills/literature-reviewopenfold3Structure prediction using OpenFold3, an open-weights PyTorch reproduction of AlphaFold3 from the AlQuraishi Lab. Use this skill when predicting protein/nucleic-acid/ligand complex structures with an Apache-2.0-licensed AF3 reimplementation.resources/skills/openfold3paper-narrativeJudge and reshape the story told by an entire paper figure deck. Use when writing or revising a paper to derive a grounded brief from the manuscript and captions, review the full deck as a handling editor, and hand an ordered figure arc to `figure-composer`.resources/skills/paper-narrativeproteinmpnnInverse-fold a protein backbone (PDB structure) into amino-acid sequence with ProteinMPNN (Dauparas et al. 2022, github.com/dauparas/ProteinMPNN). Reach for this skill to run sequence design on RFdiffusion backbones, to redesign one chain of a PDB while holding interface residues fixed, or to generaresources/skills/proteinmpnnremote-compute-sshEvaluate and use SSH Remote Compute before choosing where to run GPU, high-memory, parallel, batch, model-inference, bioinformatics, or other long-running scientific work; supports short remote commands and asynchronous jobs with automatic harvest and analysis.resources/skills/remote-compute-sshscgptEmbed and annotate single-cell expression data with scGPT, a foundation model for single-cell biology. Use this skill when: (1) Producing cell embeddings from an AnnData for clustering/integration, (2) Zero-shot or fine-tuned cell-type annotation, (3) Gene-level representation for perturbation/GRN tresources/skills/scgptscvi-toolsProbabilistic single-cell RNA-seq with scvi-tools — scVI for a batch-corrected latent space, scANVI for semi-supervised label transfer, and Bayesian differential expression. Reach for this skill to integrate scRNA-seq batches, embed cells for clustering, transfer annotations from a reference onto a resources/skills/scvi-toolsself-awarenessInspect Open-Science's JavaScript control REPL, discover managed Project files, Sessions, and Agent Frames, and safely feature-gate host.* calls with host.capabilities(). Use when an Agent needs to discover available host APIs, locate an Artifact or Upload Version, diagnose a Session, or read a Framresources/skills/self-awarenessskill-creatorCreate, revise, evaluate, publish, and improve Open-Science Skills through the native JavaScript host.skills composer. Use when the user wants a reusable workflow, an existing Skill changed, test cases or benchmarks for a Skill, or better Skill triggering.resources/skills/skill-creatorsolublempnnInverse-fold a backbone with SolubleMPNN — ProteinMPNN retrained on a soluble-PDB subset (Dauparas et al. 2022) — for sequences biased toward cytosolic expression and reduced aggregation. Reach for this skill when designs from vanilla ProteinMPNN are aggregating or going to inclusion bodies, when reresources/skills/solublempnnDocumentation
README
AIPOCH Open-Science
AI research workbench for reproducible science — open-source, local-first, and model-agnostic.




AIPOCH Open-Science is an open-source AI research workbench. Start with a question, a paper, or a data file. Describe what you want to find out in your own words, and work with an AI agent to explore the evidence, analyze data, or create a chart.
When you want to see how a result was produced, inspect the available inputs, code, and execution history. To share the work, export a .science package with the conversation branches, file versions, Notebook records, and verification evidence you choose.
💡 AIPOCH Open-Science v1.1.0 updates
November 6, 2026
- Research films: Export completed sessions as portable narrated films with terminal playback. Voice narration requires a locally installed voice model.
- Mobile pairing: Scan a QR code to open the current workspace on a phone or tablet over local WiFi or a Pinggy tunnel; internet traffic passes through Pinggy’s servers.
- Literature in CLI and MCP: Search and manage references from the command line and MCP clients, with read-only browsing plus write tools.
- Resumable overviews: Batch paper overviews resume after interruptions without regenerating completed results.
- Resource center: A renamed resource center with an adapted case library layout, more compact external links, and compute settings under connections.
- Diagnostics: Exports preserve Notebook execution evidence, allow selecting historical backend logs, and can include opt-in resource recordings (Windows).
- Reliability fixes: Recover conversations after interruptions, restore PDF figures and tables from searchable scans, and improve startup, Windows update checks, and memory use.
View the full v1.1.0 release notes

Table of Contents
- Quick Start
- AIPOCH Open-Science
.scienceResearch Packages - AIPOCH Open-Science Paper and Citation
- Benchmark Results
- Core Capabilities
- Model Providers
- Data, Permissions, and Trust
- Development & Packaging
- Frequently Asked Questions
- Contributors
- Get Involved
- License
- Star History
🚀 Quick Start
1. Download the app
Open the official download page and choose the installer for your computer:
| Your computer | Choose |
|---|---|
| macOS 12+ — Apple Silicon (M1 or newer) | The macOS DMG for Apple Silicon / ARM64 |
| macOS 12+ — Intel | The macOS DMG for Intel / x64 |
| Windows 10/11 x64 | The Windows x64 installer (code-signed) |
| Linux x64 | The Linux x64 AppImage or Debian package |
| Linux ARM64 | The Linux ARM64 AppImage or Debian package |
See download verification for checks before installation.
On macOS, you can also install with Homebrew:
brew install --cask open-science
The release assets include standalone CLI archives for macOS, Linux, and Windows. They bundle Node.js, so you can run the CLI without installing Node.js, npm, or Homebrew.
For the standalone CLI on macOS or Linux, use the separate AIPOCH tap:
brew install aipoch/tap/open-science
This Formula includes Node and runs without the desktop app; its release may differ from the desktop Cask. See the standalone runtime guide for prerequisites and upgrades.
For the standalone CLI and Web UI, install the published npm package with Node.js 22.13.0 or later:
npm install --global @aipoch/open-science
open-science start --no-open
open-science url
Open the printed URL to complete setup, or follow the terminal setup guide. npm supports macOS ARM64/x64, glibc Linux ARM64/x64 and Windows x64; the desktop app is not required. Keep npm optional dependencies enabled and review the Linux prerequisites and upgrade instructions. The URL contains an authentication token; keep it private.
Windows reinstalls preserve research data. For a full cleanup, see the data reset tool, which permanently deletes local data after confirmation.
2. Complete first-time setup
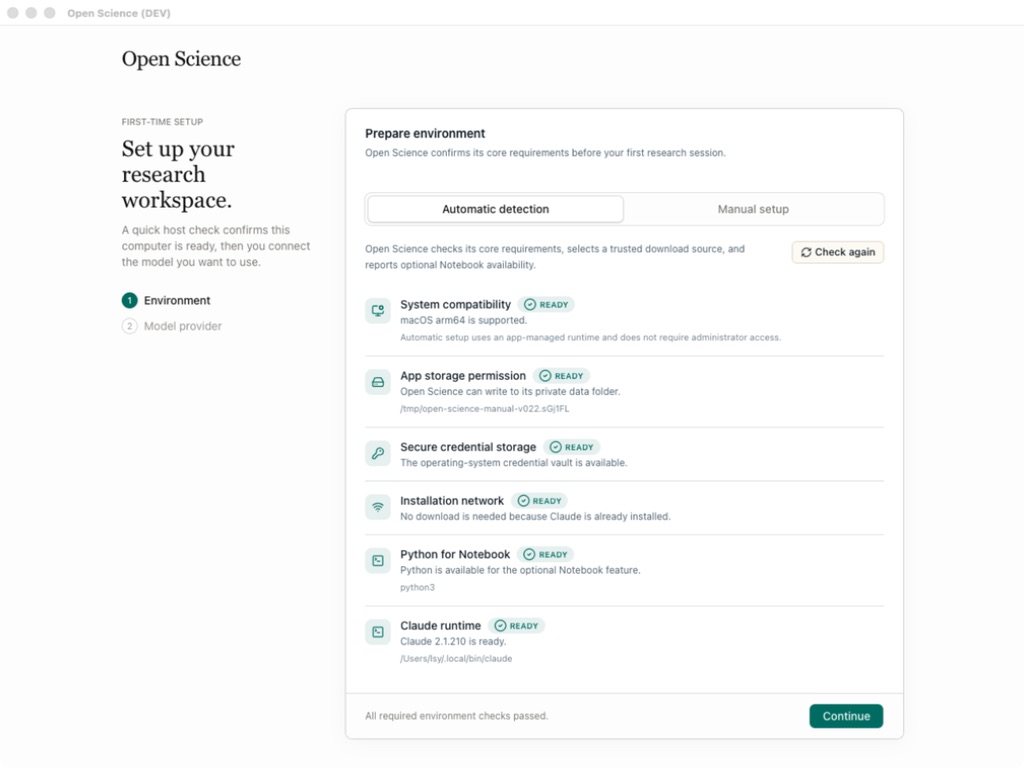
Follow the setup wizard: Environment → Data location → Agent runtime → Model provider → Notebook runtime.
Complete the required environment and agent-runtime checks and test your model connection. Python/R Notebook setup is optional; Notebook and data-location settings can be changed later.
After setup, open System settings to change appearance or notifications. In General, you can find diagnostics, command-line tools, and the guide to manual installation and updates.
 |
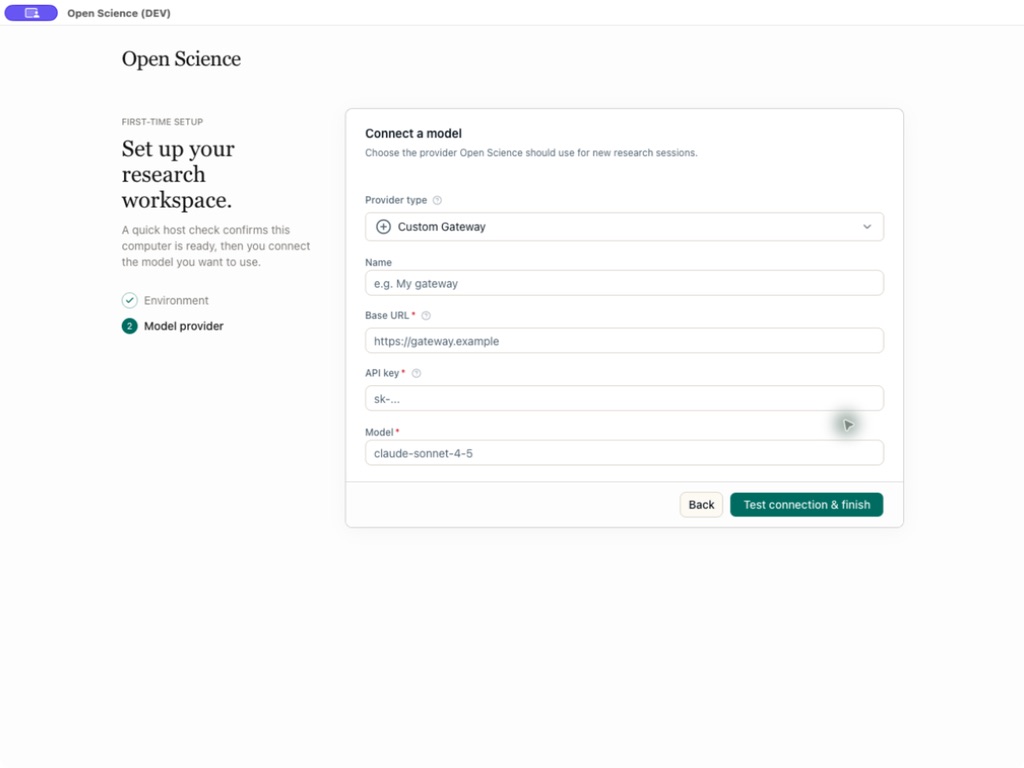 |
| Host compatibility, storage, and network checks | Provider, API Key, endpoint, and model validation |
3. Start a research project
- Click New project, open a session, and describe your research goal, inputs, and expected outputs.
- Attach files, select a model and approval mode, then send the task. Use
@to reference project files or/to choose a skill. - Review tool activity and any approval requests, preview the results, and check their available evidence in Provenance.
Screenshots in this README illustrate the workflow. Labels, catalogs, and other interface details may differ from the version you install.
AIPOCH Open-Science .science Research Packages
Export a completed research session as a portable .science package for review, handoff, and archiving. Choose the conversation branches, file versions, Notebook records, and verification evidence to include, then import the package into another project or computer.
Export and import are available in the desktop app, local Web sessions, and the headless CLI. Remote Web sessions cannot read or write arbitrary local package paths.
Export → transfer → inspect
- Export a completed session and choose the contents to include.
- Move the
.sciencefile to a collaborator or another computer. - Import it into a project. The right-hand Research replay shows the recorded process; the left-hand conversation lets you ask about it and follow fixed step references.
Imported records remain read-only. Watching a replay does not execute code, call a model, or restore credentials. Your first question creates an associated writable discussion. Choose Fork to continue to create a writable copy for follow-up work. Re-executing a result still requires a complete recipe, required inputs, and an available runtime.
Side Chat conversations, private reading bookmarks, and credentials are excluded; included files depend on export selection. Received verification records describe the sender’s checks, not a rerun on this computer. See the .science package guide.
AIPOCH Open-Science Paper and Citation
AIPOCH Open-Science: An Open-Source AI Research Workbench with Reproducible .science Packages
arXiv preprint · v1 · Submitted October 12, 2026.
Our preprint introduces AIPOCH Open-Science, an open-source AI research workbench with portable .science packages for sharing research context, artifact versions, and verification records. Read the paper for the package exchange design and controlled evaluation.
If you use AIPOCH Open-Science in your research, you can cite the preprint:
BibTeX citation
@misc{ouyang2026aipochopenscienceopensourceai,
      title={AIPOCH Open-Science: An Open-Source AI Research Workbench with Reproducible .science Packages},
      author={Wen Ouyang and Bocheng Huang and Qianyu Yao and Fei Sun and Minying Deng and Haoyue Cheng and Wenwen Zhou and Lei Mou and Yusi Wei and Jiang Li and Kun Zhu and Lei Wang and Yi Feng and Jiaheng Dai and Ke Qian and Dan Wang and Yahui Wang and Chenyi Wang and Mingsheng Lyu and Yaqiang Zhang and Ping Zheng and Chunhua Tang and Xinge Ma and Xu Zhang and Youjia Fan and Can Lu and Zhijun Dai and Man Hu and Qiqi Xie and Beinan Liu and Yuanning Guo and Yunze Liu and Jinhong Jiang and Xianjun Fu and Mingwei Zhang and Yuanji Xu and Shilin Xia and Bowen Yang and Mingjun Yu and Jingdun Xie and Xuwei Chen and Xia Zou and Yuzhou Xue and Jianguo Zhou and Chunhao Cao and Donghao Tian and Lei Huang and Jinxiao Li and Shengrong Long and Zefeng Song and Honglin Li and Jiang Luo and Wenying Jiang and Shanshan Li and Lei Dai and Ning Jiang and Ying Cai and Chaohui Li and Chunyan Peng and Hetong Zhao and Angqing Li and Chunyan Yang and Chongyang Sun and Yong Li and Xinyu Shi and Wei Dai and Ming Peng and Chen Sang and Yuanyuan Han and Desong Qiu and Haixin Miao and Jian Xu and Yi Chen and Xiaoliang Shi and Tian Shen and Teng Hu and Shuhao Wang and Yingyong Hou and Huimei Wang},
      year={2026},
      eprint={2610.17110},
      archivePrefix={arXiv},
      primaryClass={cs.SE},
      url={https://arxiv.org/abs/2610.17110},
}
Benchmark Results
AIPOCH evaluated AIPOCH Open-Science on tasks ranging from finding a paper to answering questions about its contents and carrying out a research plan. The results below come from AIPOCH's own runs. Each score describes a particular task and evaluation setup.
| Task | What AIPOCH Open-Science achieved |
|---|---|
| Find the target paper | For 68 of 75 test questions, the target paper appeared in the first 30 results on LitQA2-FullText-Search (90.67% Recall@30, gpt-6-astra). |
| Answer questions using the literature | In a separate run on LitQA2-FullText, Open-Science answered 70 of 75 test questions correctly (93.33% accuracy, deepseek-flash with Max reasoning). |
| Synthesize a cited answer | On 100 ScholarQA-CS2 validation questions, Open-Science earned a composite quality score of 0.9289/1 using deepseek-v4-flash. Official test references use different questions. |
| Carry out research workflows | In local ASI-Bench runs using the same model, Open-Science scored 59.46 on B4 and Codex scored 55.45. On B2 the scores were nearly identical (56.11 and 56.09). |
| Analyze biomedical data | On BiomniBench-DA Public 50, two judges scored the outputs 81.04 and 77.06. Their equal-weight mean was 79.05. |
AstaBench — Literature tasks
Paper retrieval — target paper found for 68 of 75 questions
AIPOCH ran the official 75-question LitQA2-FullText-Search Test split locally. Its result matched the highest Recall@30 in the October 26, 2026 comparison snapshot. This local run was not an official leaderboard submission or placement.
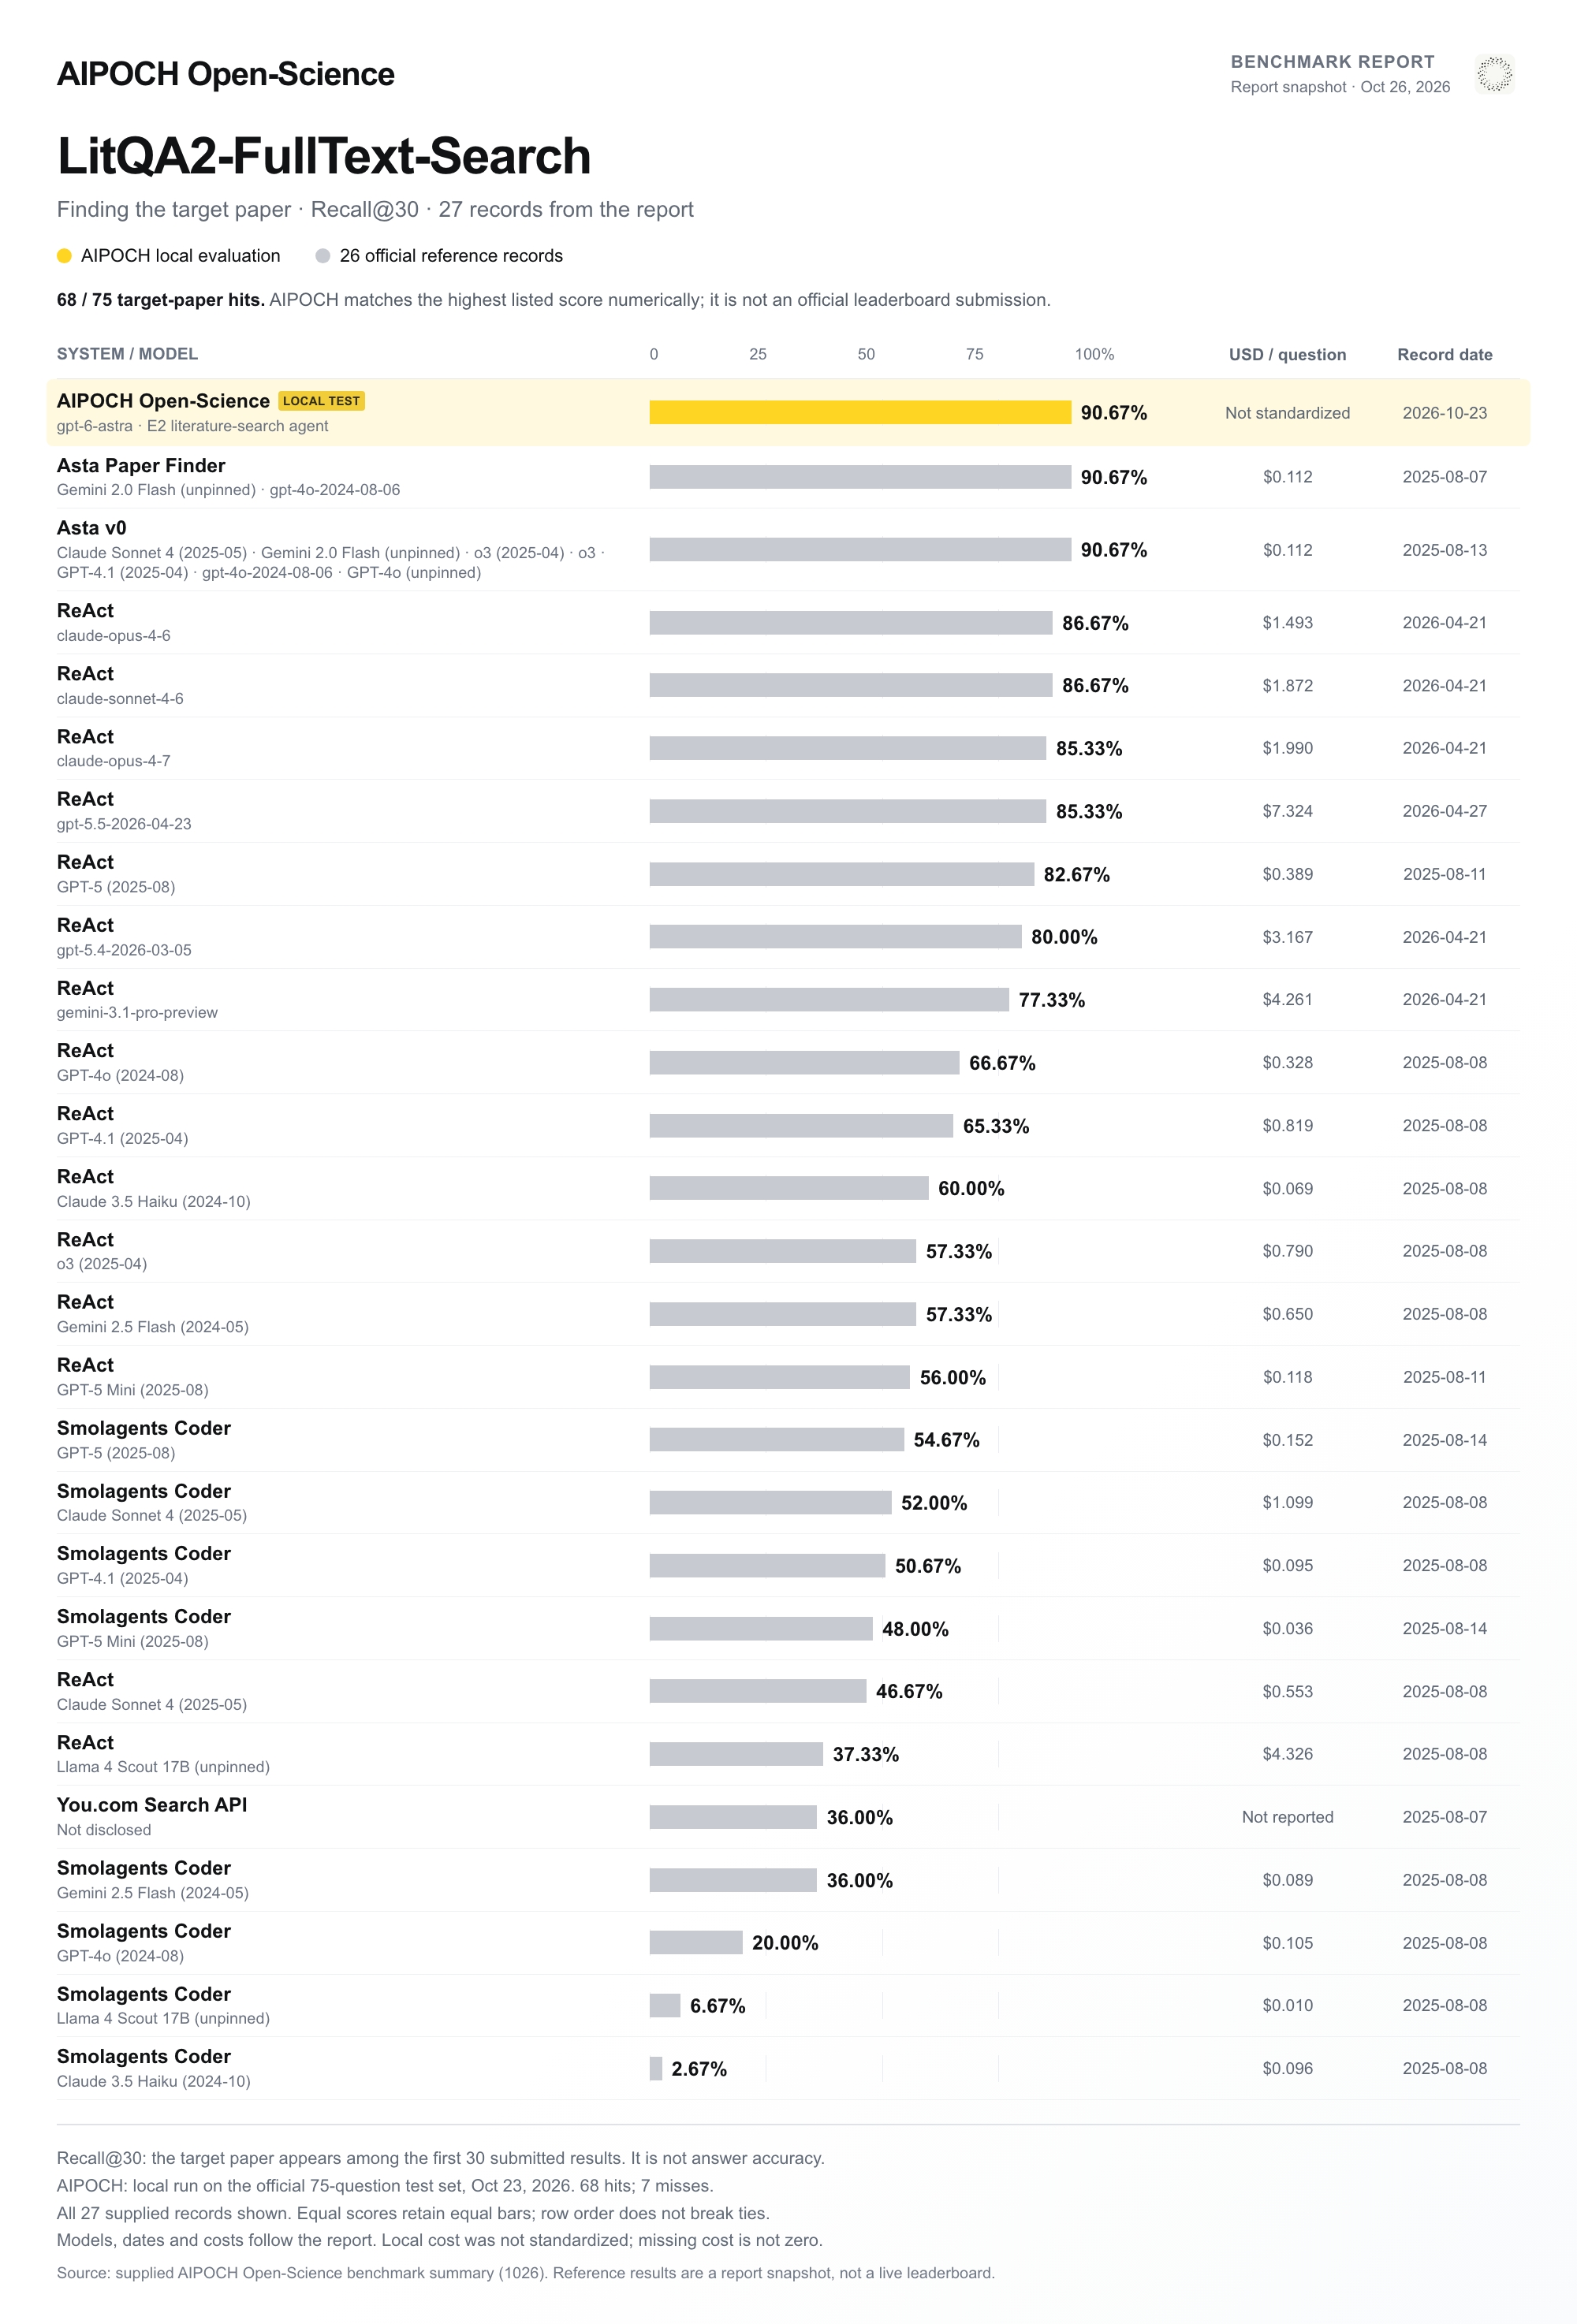
Recall@30 counts a hit when the target paper appears in the first 30 results; it does not measure answer accuracy. Costs were not standardized across the runs.
Full-text question answering — 70 of 75 answers correct
AIPOCH ran the 75-question LitQA2-FullText Test split in AstaBench v0.5.4. The chart orders the local result and historical reference records by score. Its “#1” refers to that comparison.
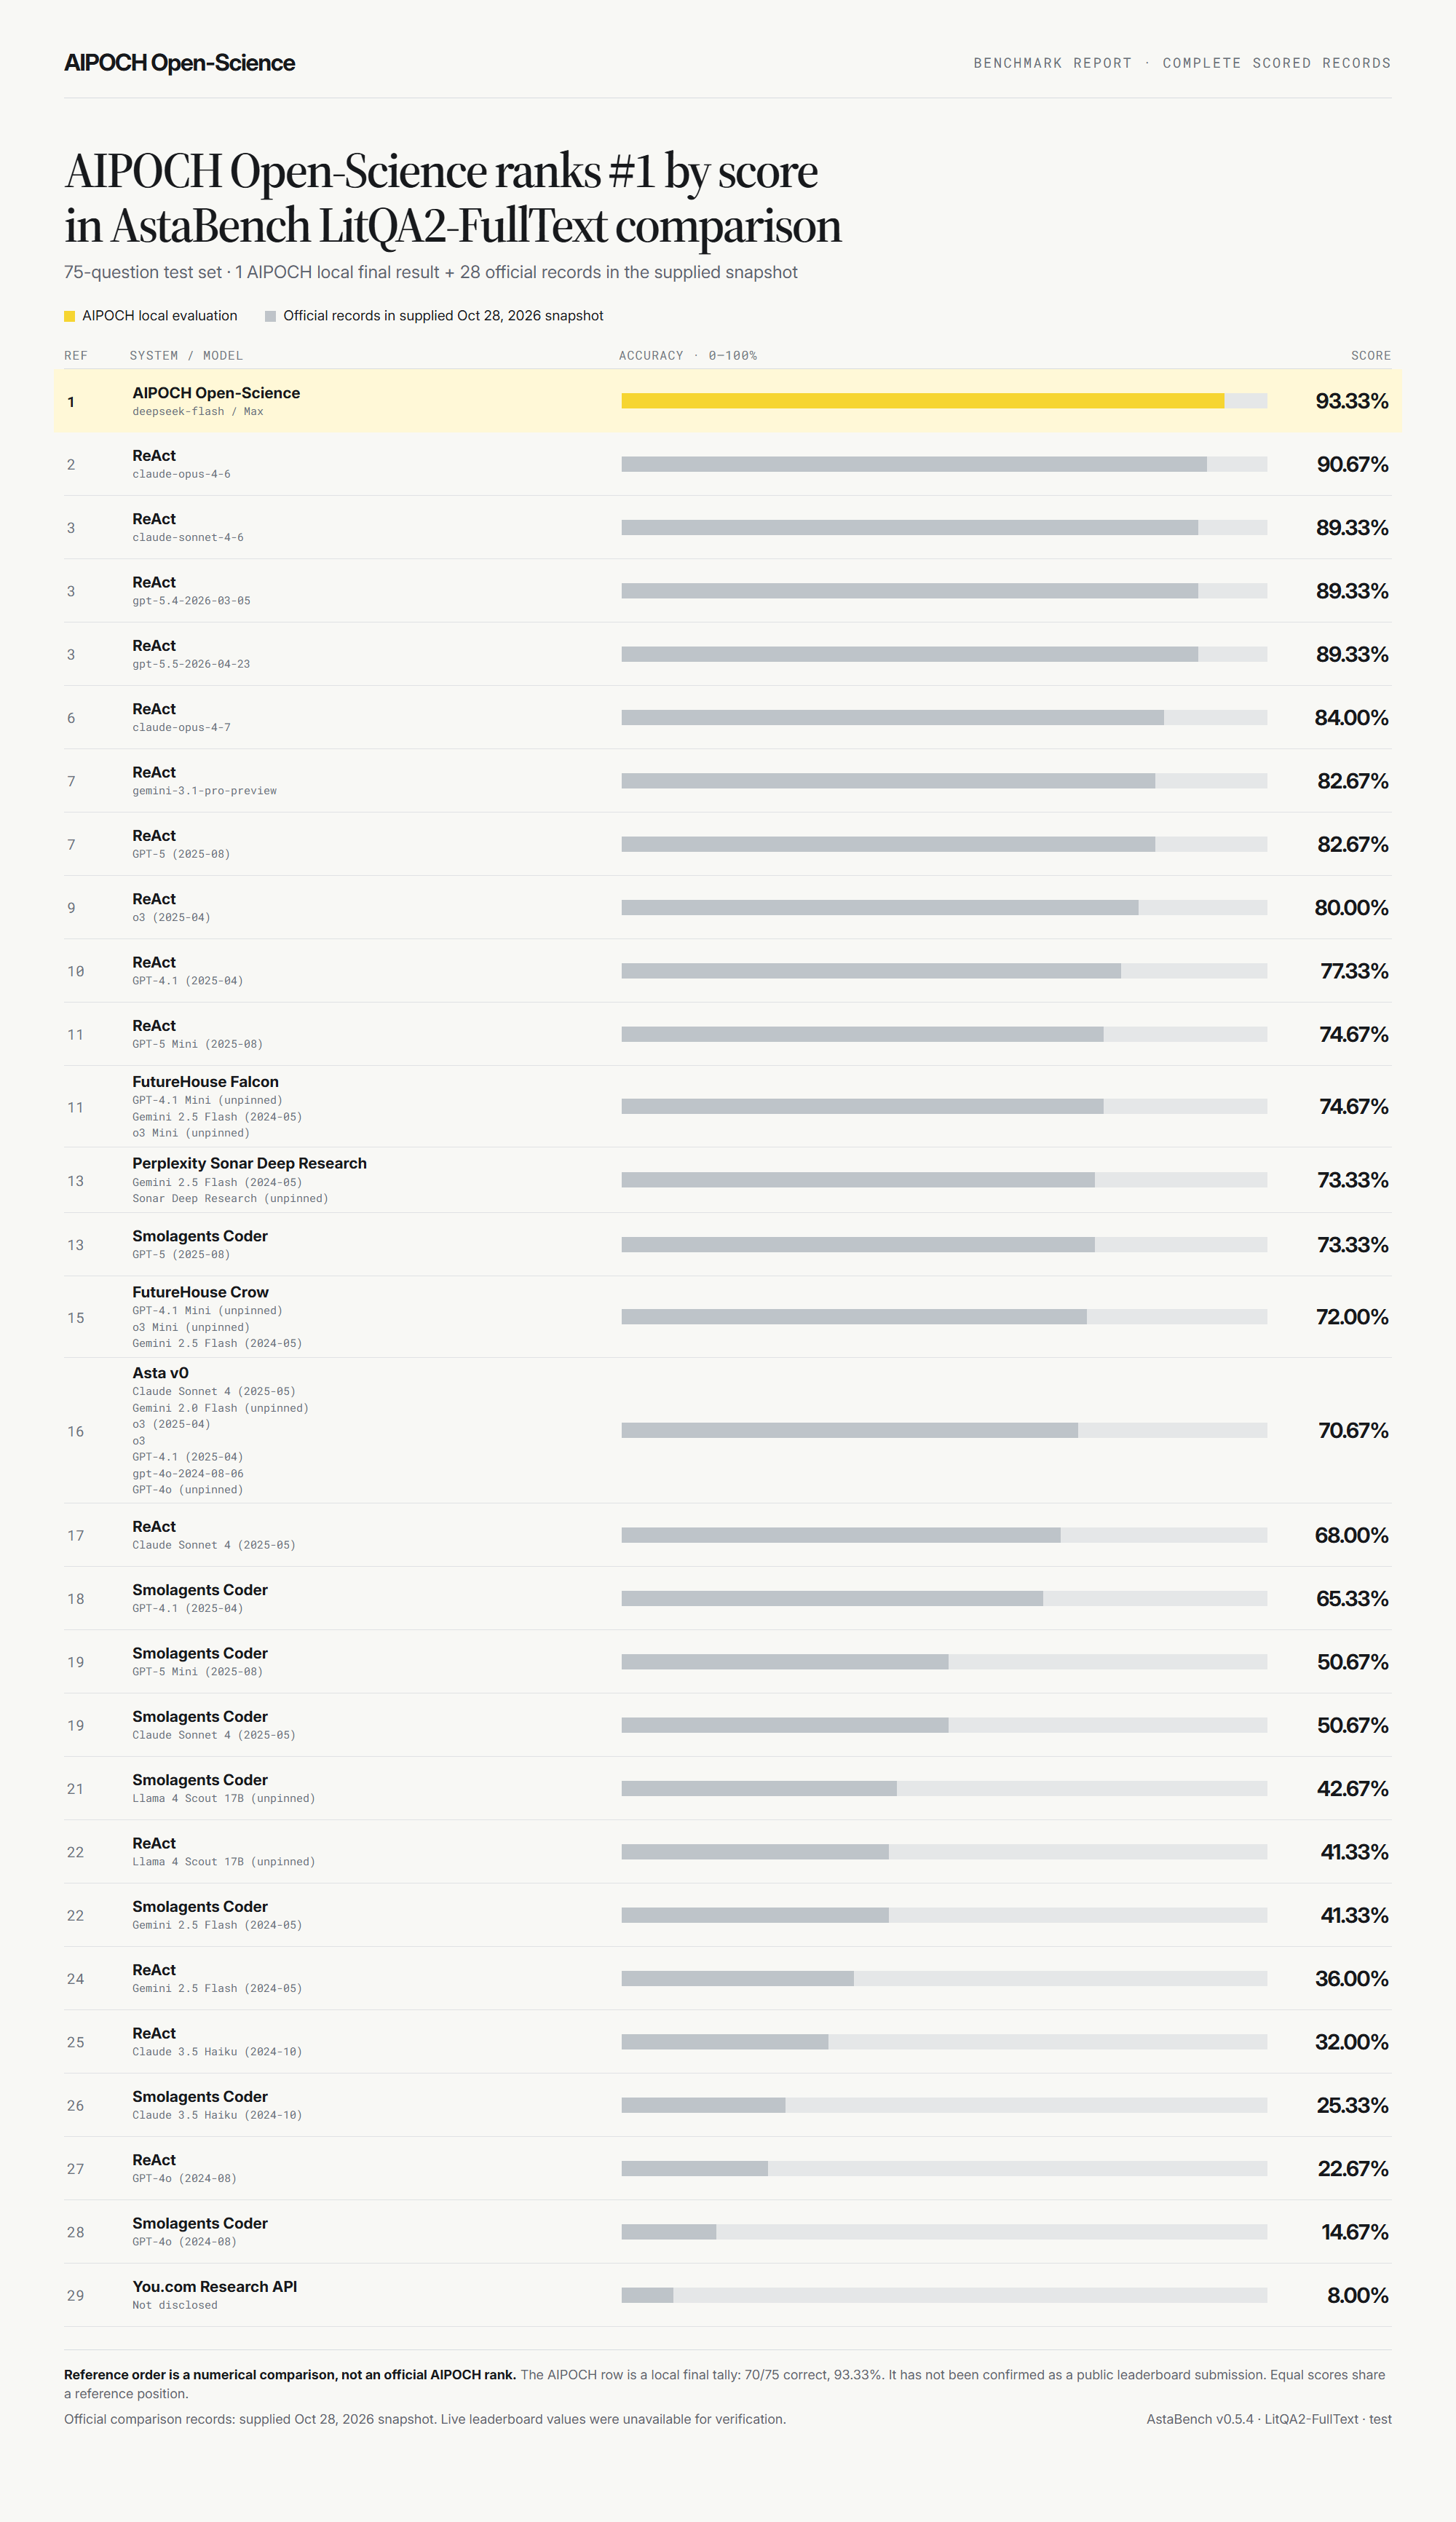
Accuracy measures correct answers. Here, 93.33% is the local answer accuracy and 90.67% is a historical reference answer accuracy. The retrieval chart above uses a different metric. Reference records were captured on October 28, 2026; the highest reference score was checked again on November 2.
Cited-answer quality — local validation result and official test references
The local ScholarQA-CS2 result measures the quality of cited answers on 100 Validation questions. Reference results are from the Test split, so the scores do not establish a head-to-head ranking.
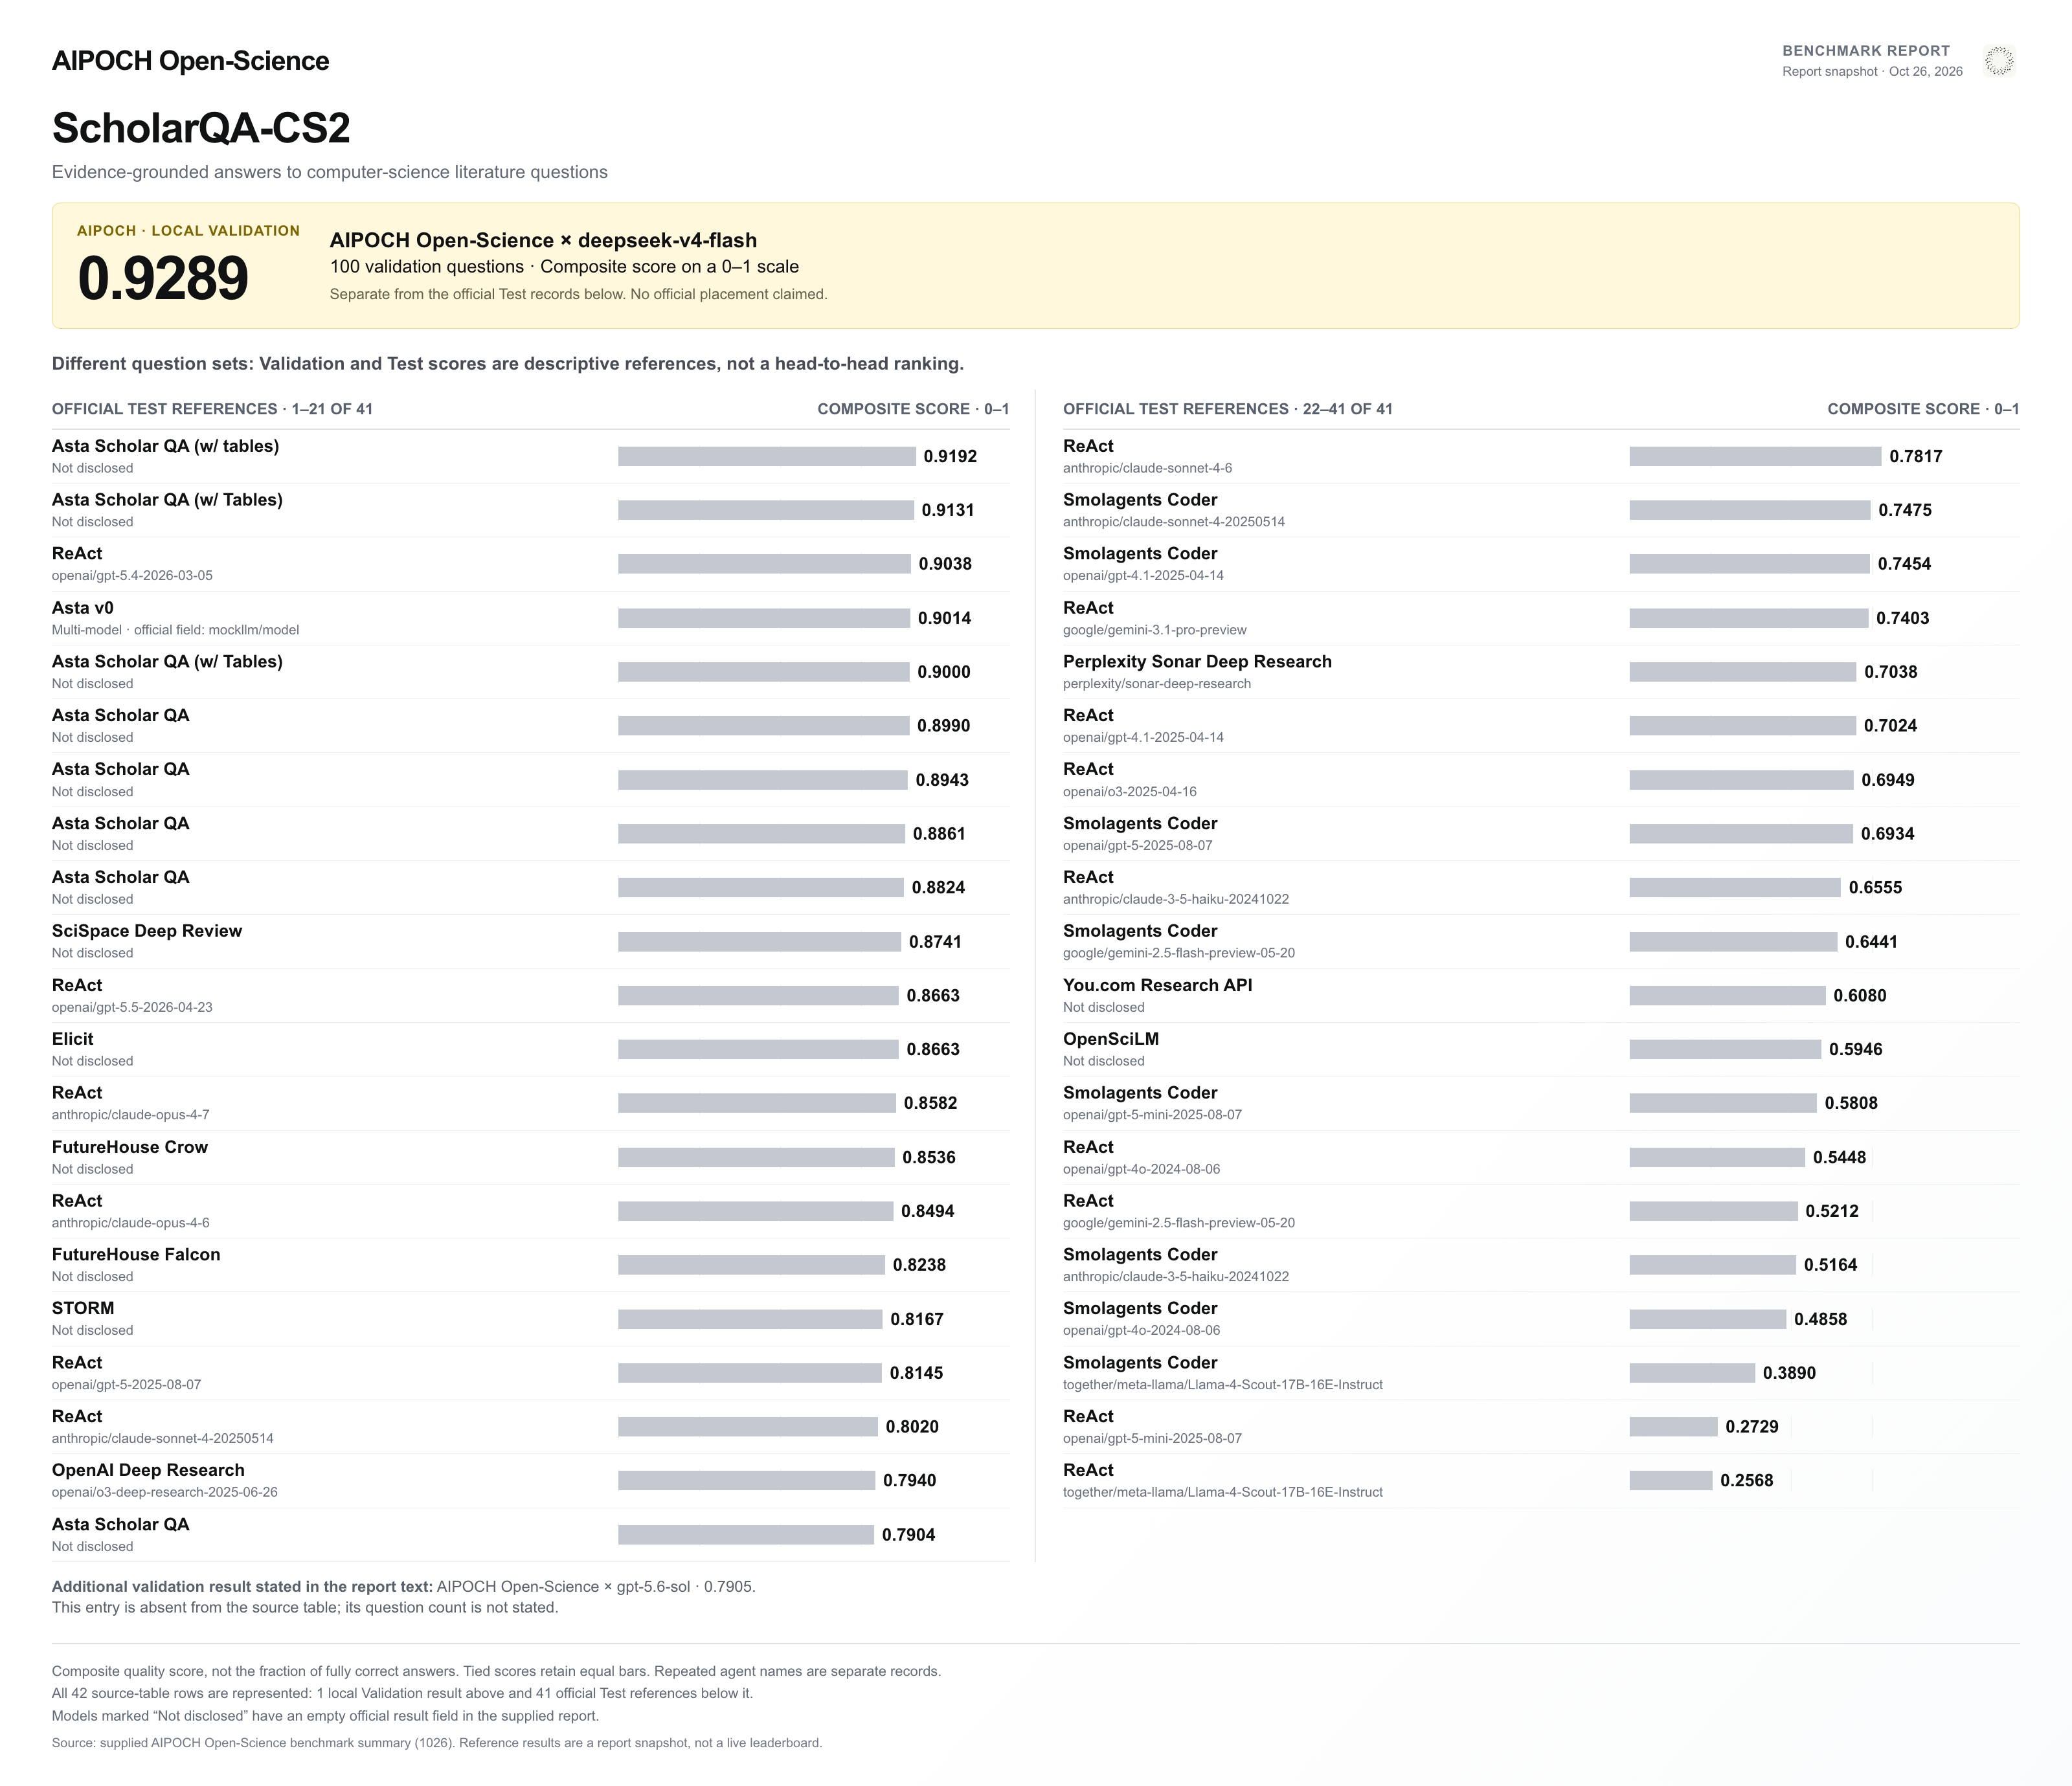
The composite score is reported on a 0–1 scale; it is not the percentage of questions answered completely correctly.
ASI-Bench — Following a plan and choosing methods
The four conditions ask the agent to execute a specified plan (B1), organize a workflow (B2), choose methods (B3), or work through distracting information (B4). The first two rows of the chart compare local runs using the same GPT-6 Astra model.
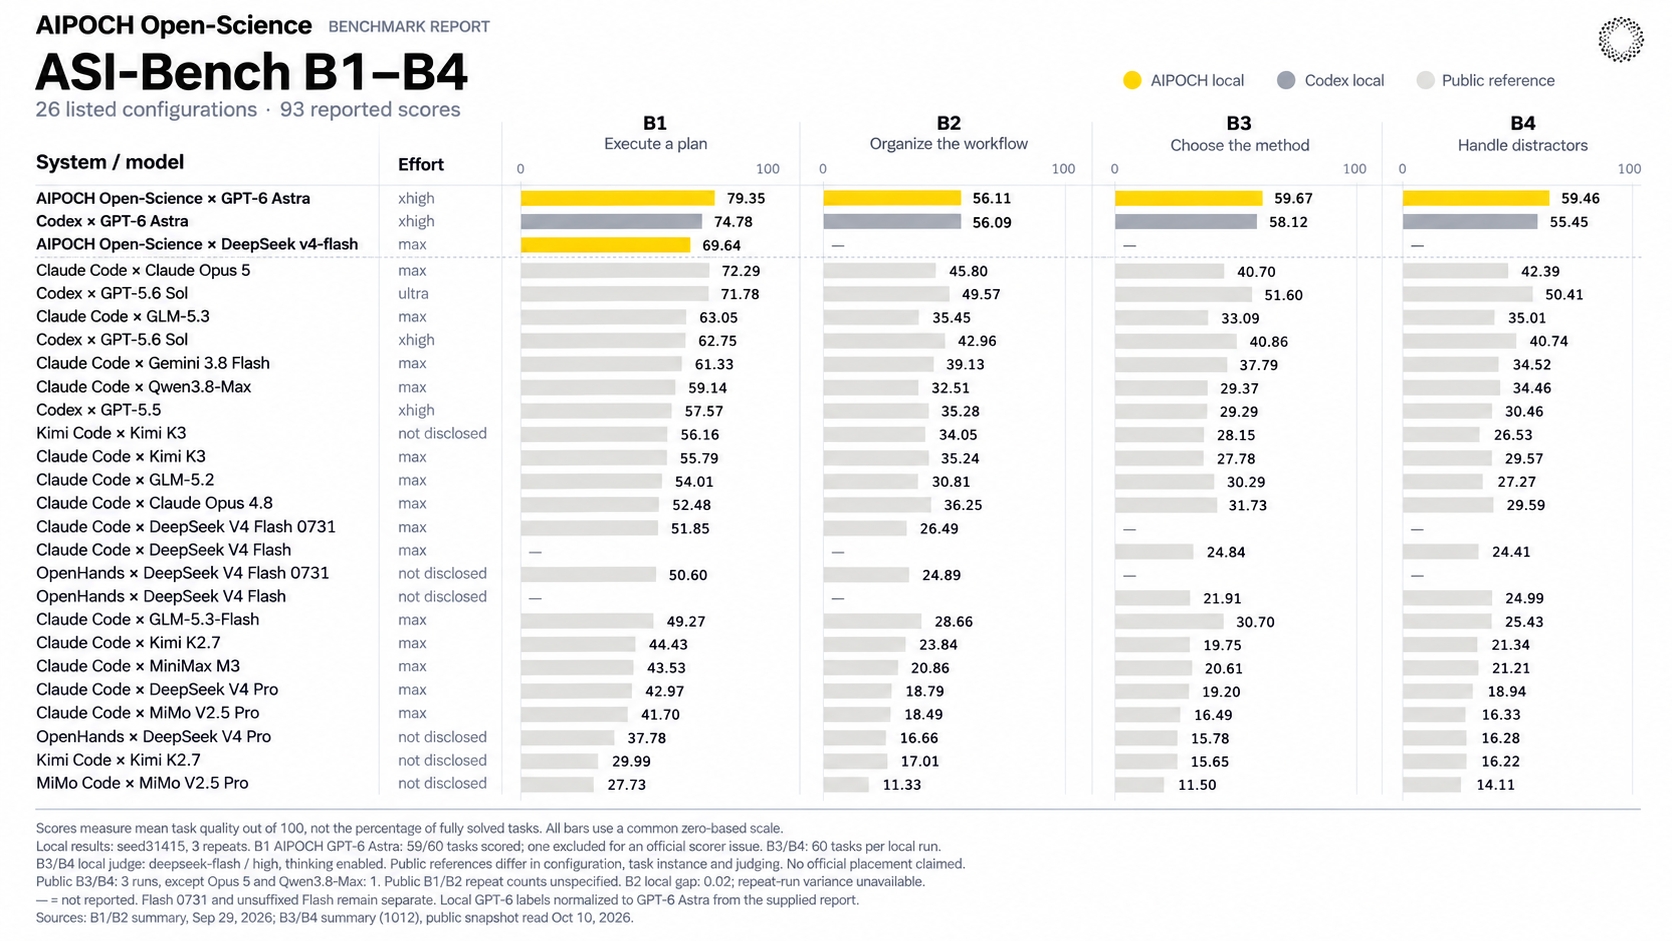
Open-Science scored 79.35, 56.11, 59.67, and 59.46 on B1–B4; the local Codex reference scored 74.78, 56.09, 58.12, and 55.45. The B2 scores were nearly identical. Other published runs differ in task instances, configurations, or judging.
The local B1 score covers 59 tasks after one scorer-related exclusion. Three local repeats were reported for B1/B2. B3/B4 used Open-Science v0.32.0 and a substitute judge; each score averages three 60-task runs.
BiomniBench-DA — Biomedical data analysis
On the Public 50 task set, the Gemini 3.1 Pro judge scored the outputs 81.04 and the DeepSeek v4-pro judge scored them 77.06. AIPOCH reports their equal-weight mean, 79.05, for the gpt-5.6-sol (xhigh) configuration.
Judge scores and historical references — judge coverage varies
The chart combines entries with different judge coverage. Its “#1” describes the ordering of that collection. A ranking under a common judging procedure would require comparable scoring for all entries.

79.05 is a mean judge score across this internal evaluation.
Evaluation scope: These reports cover local/internal runs from August to November 2026 with the stated models and splits; the evaluations were not rerun for the current release. Reference scores are historical snapshots, not live rankings. Scores from different benchmark families are not directly comparable, and numerical gaps do not establish statistical significance.
Read the AstaBench and ASI-Bench report and the BiomniBench-DA report for evaluation details.
Core Capabilities
AIPOCH Open-Science combines project management, multi-model agent execution, Python and R notebooks, scientific data connectors, immutable artifact versions with provenance, and permissioned human-in-the-loop control in one local workspace. The installed app and latest release notes are the source of truth for changing catalogs, packaging details, and newly added options.
| Area | Core capability |
|---|---|
| Scientific skills | Extend research workflows with 24 built-in skills and 525 skills available from the Skills Marketplace, with one-click installation and updates. Create skills through conversation or completed work, import packages or GitHub sources, and save GitHub repositories for reuse in the import workflow. Saving a repository does not install its skills. Marketplace contributions are published after review; local imports do not publish skills. |
| Connectors | Access scientific resources through 48 built-in connectors, or add custom local and remote MCP connectors. Some built-in sources are disabled by default and require per-source opt-in. Manage tool-level permissions and import or export connector configurations. |
| Specialists and delegation | Install 10 Specialists from the Specialist Marketplace, or create and customize personal specialists for delegation from the main agent. Specialist packages support import and export; marketplace contributions are reviewed before publication, and local imports do not publish them. |
| Models and agent backends | Use cloud models, compatible custom gateways, or Claude and Codex subscription logins. Choose from five agent backends — Claude Code, OpenCode, Codex, CodeBuddy, and Pi — with model connection checks, image input, and reasoning controls. |
| Projects, sessions, and research packages | Organize projects with pinned sessions, message branches, side chats, and recoverable history. Export a portable .science research package and import it into another project or computer with conversation branches, selected file versions, Notebook records, and verification evidence. Imports are read-only and do not execute code or restore credentials; side chats and bookmarks are excluded, and included files depend on the export selection. |
| Reviewer | Enable optional auto-review to check a completed agent turn's responses, execution logs, and related file evidence in a separate context. Get evidence-backed pass, warning, or failure checks, with a bounded cycle of main-agent corrections and re-review when issues are found. Review logs and issue-resolution states remain available; the review is limited to records available for that turn. |
| Python, R, notebooks, and HPC | Run Python, R, Notebook, and shell workloads locally using managed environments or your own interpreters, with background execution and recorded history. Connect to remote hosts through SSH or submit work through Slurm; remote workloads require the host, software, resources, and permissions described in the remote-compute FAQ. |
| Literature Library | Import and manage references and PDFs with collections, tags, project links, notes, and duplicate merging. Discover a paper’s references and citing works through Semantic Scholar, download and preview supplementary attachments, and drag and drop PDFs or bibliography files. Find open-access full text, read PDFs and extract figures and tables, and use library sources in conversations for AI-assisted analysis. For references with a valid DOI, manually check Crossref for known retractions or corrections; the check sends the DOI to Crossref, and incomplete coverage means no notice is not proof that a work is unaffected. Generate bibliographies, export references as BibTeX or RIS, and export Smart Screening decisions as CSV. Manually set reading status to Unread, In progress, or Finished reading, update selected references in bulk, and filter by status. Search personal notes from the existing reference search box. Generate paper overviews for up to five selected references, with two processed concurrently. Results are saved to each reference’s details; failures pause the remaining queue, which can be resumed or retried without regenerating saved results. |
| Scientific files and previews | Upload individual files up to 10 GiB, organize project files, and preview scientific data, PDFs, Office documents, images, code, and molecular structures. This upload limit does not guarantee that a model can read an entire file: model context, attachment parsing, and previews have separate limits. Large files usually need chunked reading or analysis with code. |
| Artifacts and provenance | Keep immutable artifact versions with available producer code, inputs, execution history, environment information, and review evidence. Import artifacts from authorized folders; AIPOCH Open-Science copies each imported file into managed artifact storage. In the desktop app, replay eligible versions with a complete recipe, required inputs, and a usable runtime, then compare outputs and export verification records. Missing evidence may prevent verification, and replay checks do not establish scientific validity. |
When querying the eQTL Catalogue by genomic coordinates, use the GRCh38 assembly. The connector checks the assembly before looking up matches.
Import references, tags, collections, and source links from Zotero 10 or later running on the same computer, with the option to copy local PDF attachments. This is a one-way import into Open-Science and does not modify Zotero.
Add a reference using a DOI, arXiv ID, PMID, PMCID, or supported article link, or paste up to 100 references with one per line. Review and edit a single reference before saving, or select which references to import in a batch. Full-text PDFs can be added separately.
Persistent PDF annotations and document notes are available. With a screening model configured, smart collections evaluate references against your inclusion/exclusion criteria; AI decisions remain separate from manual decisions and support human review.
In reading mode, agents can list, locate, and create notes and marks on linked PDFs. PDF annotations are tied to the annotated file version and do not sync across computers.
Open a paper's detail view to generate an AI paper overview with your configured main model. The card identifies its source (full text or abstract) and summarizes the research question, study population, methods, main findings, and limitations.
Optional OCR recognizes scanned PDF pages after the component and required language packs have been downloaded. Nine language packs are available: English, Simplified Chinese, Traditional Chinese, German, Spanish, French, Japanese, Korean, and Russian. Page-level coverage indicators show which pages still lack text.
Translated PDFs can optionally reflow body text and captions into a single-column, content-first layout while retaining images, tables, formulas, and the bibliography in their original form, with source-to-output page mappings for comparison. On new setups, Notebook and Shell folder restrictions are enabled by default and confine those runtimes to the workspace, approved folders, and files required by tools; this setting does not control agent-native tools or remote computers.
In the desktop app, artifact provenance can also be exported as RO-Crate 1.1. A version-bound environment bundle can create a managed environment only when the captured bundle is complete and compatible with the target platform; this is separate from a full machine backup.
Browse research cases in the resource center, filter by category, search by keyword, and download packages from case details.
Model Providers
AIPOCH Open-Science is model-agnostic at the product level: connect it to major cloud LLM providers, a custom gateway, or reuse an existing Claude or Codex subscription. Provider availability currently depends on the selected agent backend and the API protocols it supports. The following connection options are available:
| Provider mode | How it works |
|---|---|
| Built-in cloud providers | Choose from the provider list shown by the installed app and authenticate with the requested key. |
| Custom Gateway | Supply a Base URL and exact model ID with an API protocol supported by the selected agent backend (Messages, Chat Completions, or Responses), then run the connection test. Remote gateways require HTTPS and an API Key. Loopback endpoints such as localhost, 127.0.0.1, or [::1] may use HTTP without a key; presets include Ollama, LM Studio, llama.cpp, and vLLM. A default API format does not guarantee server or model compatibility. |
| Codex Subscription | Select the Codex agent framework, then choose Codex Subscription as the provider type. |
| Claude Subscription | Sign in with a Claude subscription in two modes: shared (a browser login that stores credentials in your default ~/.claude profile) or isolated (an app-managed claude setup-token run under an app-owned CLAUDE_CONFIG_DIR, fully isolated from ~/.claude/, with a browser flow plus a paste-a-token fallback). |
| xAI (Grok) OAuth | Use the built-in xAI (Grok) OAuth device sign-in. Access depends on your xAI account and the selected backend’s protocol support; validate the connection in the app. |
There are 25 preset provider options, including OpenAI, Anthropic, DeepSeek, NVIDIA Build, and others; available models and regional endpoints depend on the installed version and selected agent backend. Check the provider selector and connection test in the app.
Data, Permissions, and Trust
AIPOCH Open-Science stores project data, settings, artifact versions, and provenance evidence on the local computer. API Keys are kept locally and use the operating system's secure credential storage when it is available. Logs are local and are not uploaded automatically.
External data flow is still possible and should be reviewed:
- Model requests send the prompt and necessary context to the selected model provider.
- Web searches and remote connectors send their displayed parameters to external services.
- Local connectors may execute trusted commands on the computer.
- The application can also contact update servers, marketplace catalogs, and runtime or model download services.
- Attachments,
@references, logs, and generated reports may contain sensitive research data.
Choose the narrowest permission profile that fits the task:
| Mode | Behavior | Recommended use |
|---|---|---|
Ask for approval |
Requests approval for actions not already covered by scoped grants or trusted application tool policies | New workflows, sensitive data, unfamiliar scripts |
Auto-approve edits |
Uses the backend's native auto review when available; otherwise automatically allows clearly low-risk workspace operations | Trusted file-editing work with controlled external access |
Full access |
Automatically allows edits, commands, network, and connectors | Clearly scoped, fully trusted, unattended work |
The effective profile depends on the selected backend and existing grants. Connector, tool, and compute-network policies also apply; check the effective mode shown by the app.
Review connector parameters and tool activity before approving them. Never include API Keys, access tokens, patient identifiers, unpublished data, or sensitive local paths in screenshots or public issue logs.
Development & Packaging
AIPOCH Open-Science has an ordinary Node backend and an Electron desktop client, built with React, TypeScript, Prisma/SQLite, and an ACP-based agent runtime.
Prerequisites for source development:
- Node.js 24 (see
.nvmrc) with npm - Git
- Notebook execution optionally uses app-managed Python/R environments or a compatible interpreter you configure.
git clone https://github.com/aipoch/open-science.git
cd open-science
npm install
npm run dev
See the development command and packaging reference and contribution guide for build commands and the development workflow.
Localhost Web and standalone Node runtime
The same Web UI can run on an ordinary Node backend without Electron or a graphical display. Electron starts or attaches to that same Node service. One runtime owns each data directory.
npm run dev:web       # Build and run the Node backend + Web UI
npm run pack:backend  # Build a target-specific standalone npm tarball
For a published installation, use npm install --global @aipoch/open-science; the commands above
are for source development. Install the package or locally built tarball, then run
open-science start --no-open and open-science url to open the
existing UI. See the standalone runtime guide for installation,
secure credential storage, host capability boundaries and data compatibility.
The desktop app and browser share the same service. App connections and an explicit open-science start hold keep it running. Quitting the last App stops the service only when no explicit hold remains.
Mobile remote access
Scan a QR code to open the current workspace on a phone or tablet over local WiFi or a Pinggy tunnel. Local WiFi pairing stays on your network; internet tunnels route traffic through Pinggy’s servers, as disclosed in the connection dialog.
Headless CLI and SDK
The headless CLI and zero-dependency Node.js SDK use the same local daemon, projects, sessions, credentials, and permissions as the desktop and web interfaces. Detailed usage lives with the publishable package so there is one command reference to maintain:
- CLI guide - installation, service lifecycle, task automation, artifacts, output formats, and exit codes
- SDK package overview - Node.js quick start and package entry point
The standalone CLI can expose its research tools to external MCP clients through open-science mcp. Start and authenticate the selected profile's service first. The adapter uses that profile's existing permissions; it is not a separate sandbox or read-only view, so connected clients can persist changes and incur model costs. It does not expose arbitrary shell or RPC access, credential management, file import/export, download-to-path operations, or a remote HTTP MCP endpoint.
Frequently Asked Questions
Why does the model connection test fail?
A: Check the API Key for missing characters or spaces, verify the Base URL and region, use the provider's exact model ID, and confirm network access and account balance. For a Claude subscription, retry the shared browser login or refresh the isolated claude setup-token credential, depending on the selected mode.
Why is Continue disabled during setup?
A: The current step has not met its required condition. Fix any environment row marked Action needed, install or repair the selected agent runtime, or validate the model provider, depending on the active step. Notebook setup is optional and only affects Notebook execution.
How do I run jobs on a remote HPC cluster?
A: Remote Compute (SSH) is always enabled and does not need to be enabled in Settings. Register an SSH compute host under Settings → Connections → Compute, make it available to the current session, and then use natural language or /remote-compute-ssh. You need a reachable SSH host, valid authentication, permission for the required directories, and the software, dependencies, and compute resources required by the workload. Direct SSH does not require a scheduler; Slurm mode requires a working Slurm environment and permission to submit jobs. “Always enabled” refers to the skill, not to the availability of every registered host.
Is there a command-line interface?
A: Yes. Install the standalone CLI, or use Settings → General → Command line tool → Install command
…
Releases